What Are Inferential Statistics?
A plain-language, jargon-free explainer, with real-world examples


The 30-second summary
Inferential statistics use a sample to draw conclusions about the wider population, and tell you how much uncertainty those conclusions carry.
- Estimation gives a best guess for a population value, with a confidence interval that shows how precise that guess is.
- Hypothesis testing asks whether a pattern in your sample is bigger than chance would produce, and reports a test statistic and a p-value.
- Tests of difference, such as t-tests, ANOVA and chi-square tests, check whether groups really differ in the population.
- Tests of relationship, such as correlation and regression, measure how variables move together; regression also predicts one from the others.
- A significant result doesn't prove cause or a big effect, so report the effect size, and let your research design carry any causal claim.
For a one-page reference, the free statistics cheat sheet explains the main inferential tests in plain English, and which one to reach for.
Navigate
Inferential statistics are where your sample has to earn the right to speak for everyone else. Misread one result, and you’ll either claim a finding your data can’t support or throw away a real one because the p-value came in at .06.
Across the 10,000+ students we’ve coached, we’ve seen the arithmetic cause far less trouble than the logic behind it. In this post, I’ll explain how inference works, in plain English, walk you through the five tests you’re most likely to meet, and show you how three real dissertations reported and read their results.
What are inferential statistics?
Inferential statistics are the methods you use to draw conclusions about a population from a sample, while saying how confident you can be in those conclusions. Purdue’s writing lab sums up the goal in one sentence:
In practice, that splits into two jobs:
- Estimating a value in the population.
- Testing whether a pattern in your sample is likely to be real or just a product of chance.
The “real or just chance?” question is what statisticians call statistical significance, and it’s how inferential statistics let you test hypotheses and, in some cases, make predictions.
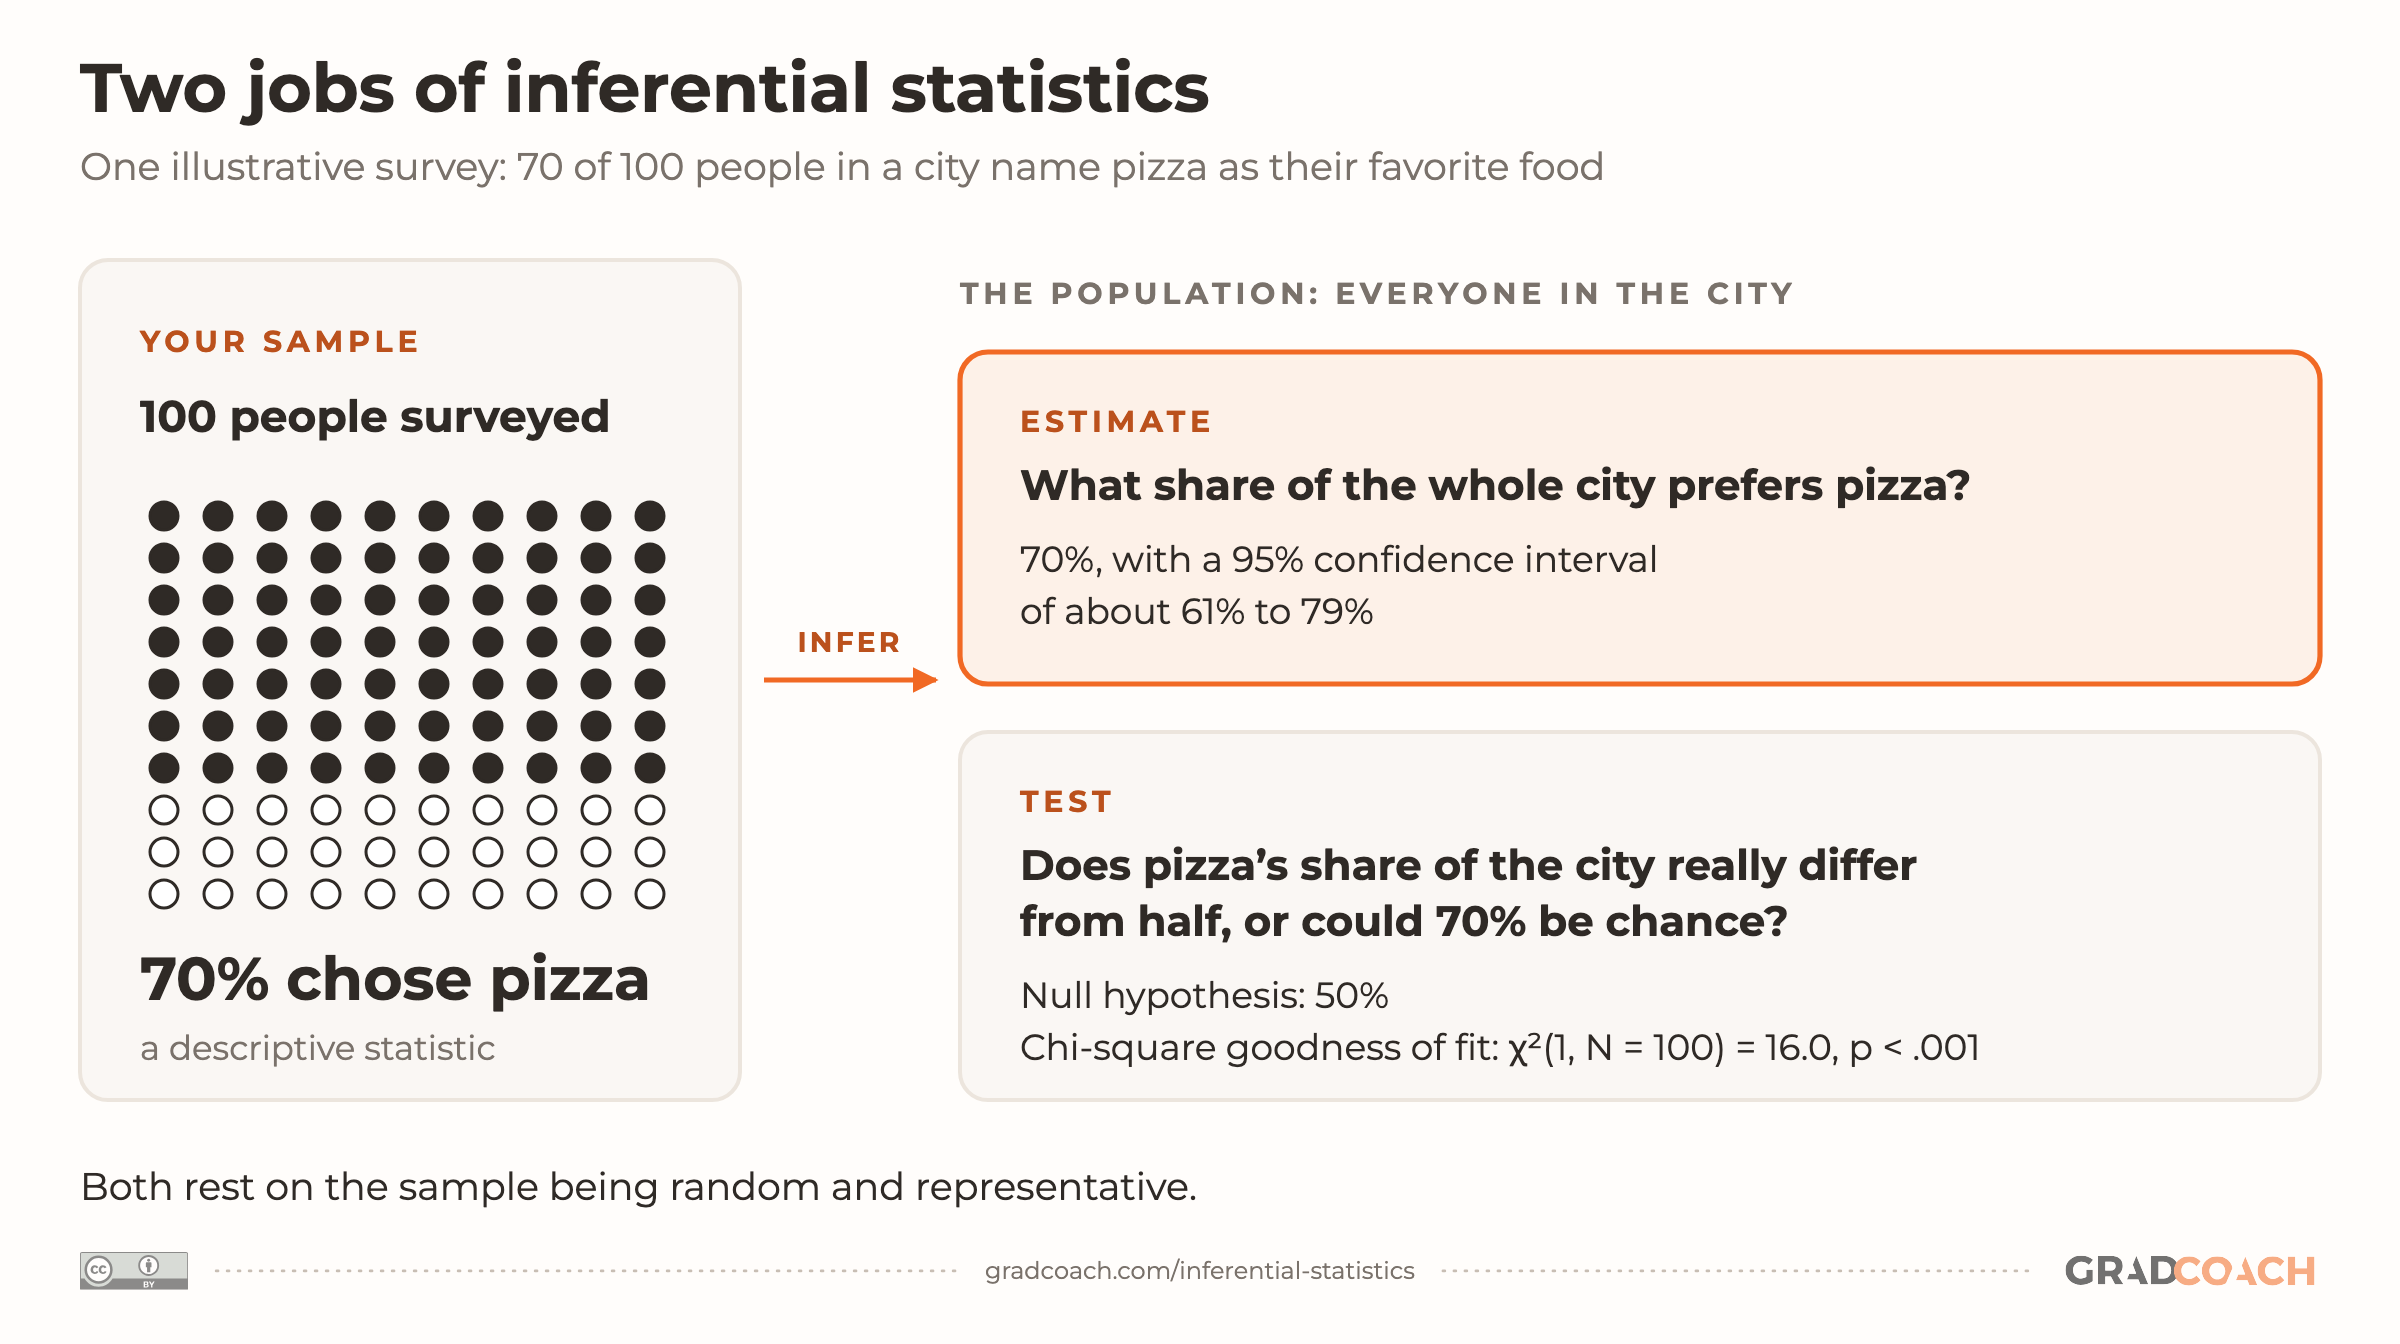
Let’s say you surveyed 100 people (your sample) in a city about their favorite type of food, and 70 of them chose pizza. That 70% describes your sample. Inferential statistics let you go further, in two ways. You could estimate what share of the whole city (your population) prefers pizza, with a margin of uncertainty around it. Or you could test whether pizza’s share of the city really differs from half, rather than the 70% being a quirk of the 100 people you happened to ask.
The figure below runs that same survey through both jobs:

Both answers depend on one condition. Inferential statistics work best when your sample is drawn at random and represents the population. Survey 100 people outside a pizzeria, and no test in the world will rescue your conclusion about the city. That’s why the sampling methods you choose matter as much as the statistics you run.
Inferential vs descriptive
Descriptive statistics are the other branch of the family. In short, descriptive statistics summarize the data you already have (your sample), while inferential statistics use that sample to say something about the broader population, and potentially to make predictions about it.
Let’s imagine you’re undertaking a study that explores shoe brand preferences among men and women. If you just wanted to report the proportions of each group who prefer different brands, you’d only need descriptive statistics. However, if you wanted to assess whether those proportions differ between men and women in the broader population (and that the difference isn’t just down to chance), you’d need inferential statistics.
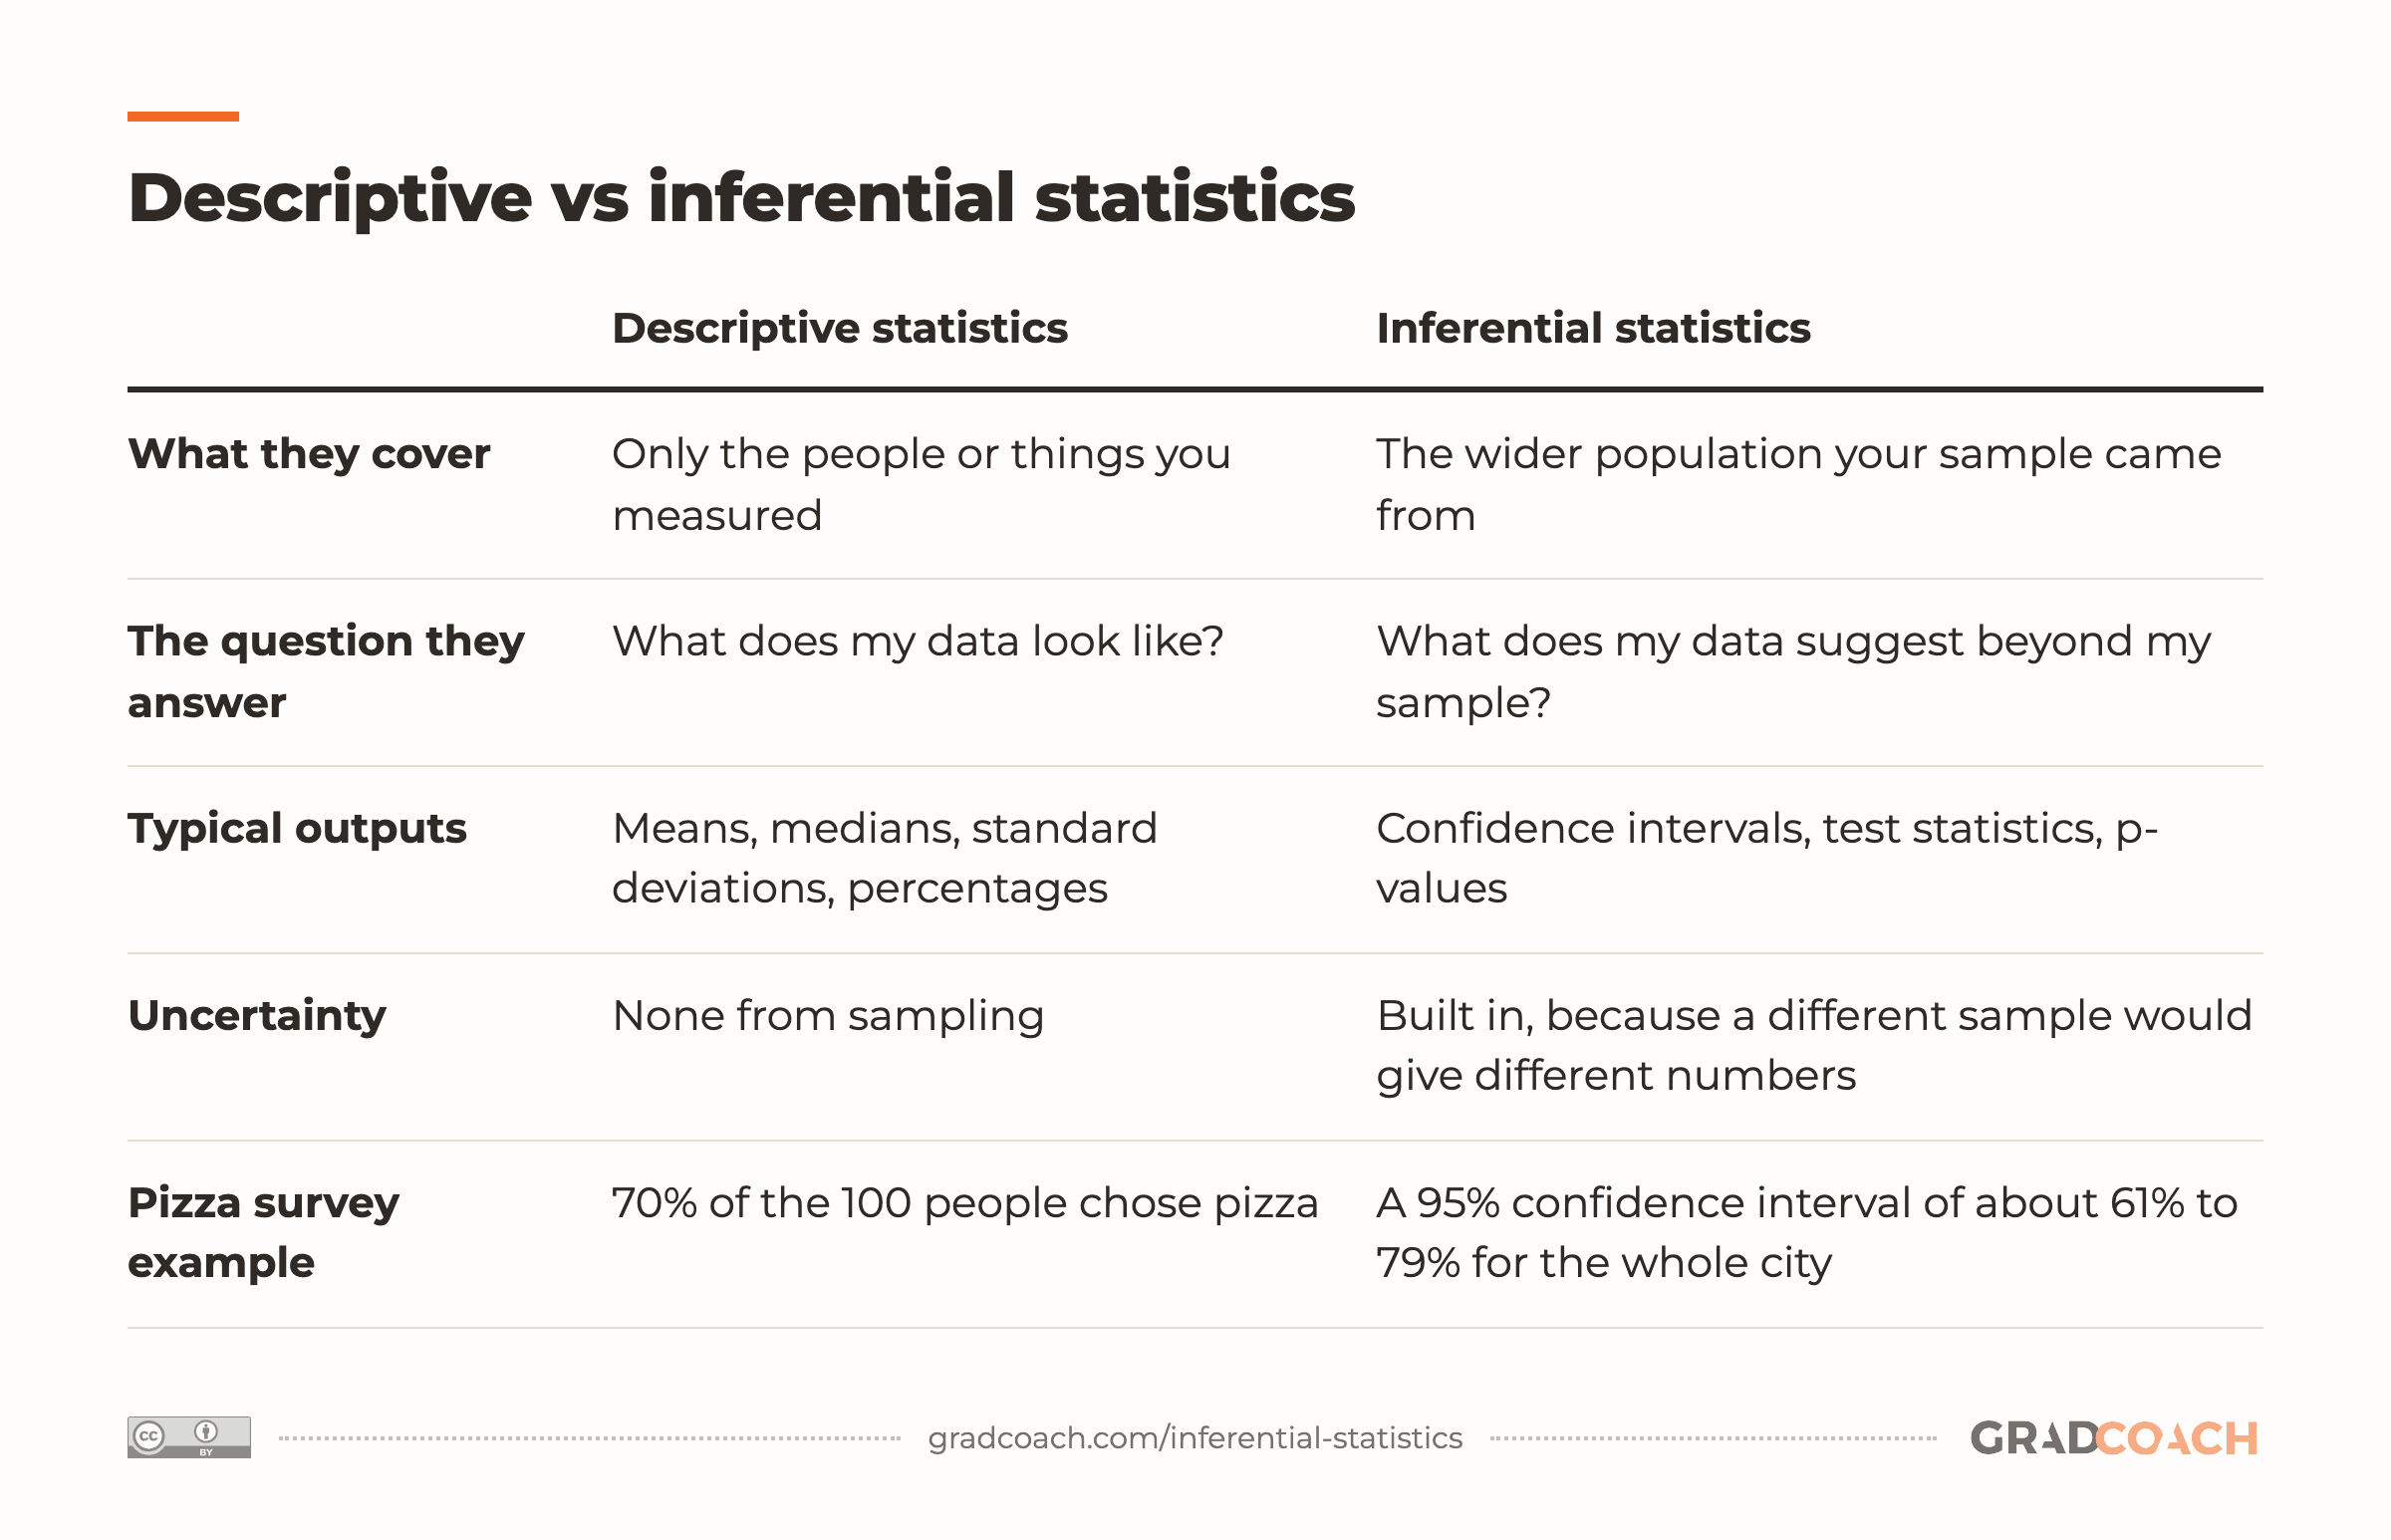
Side by side, the two differ on five counts:
| Descriptive statistics | Inferential statistics | |
|---|---|---|
| What they cover | Only the people or things you measured | The wider population your sample came from |
| The question they answer | What does my data look like? | What does my data suggest beyond my sample? |
| Typical outputs | Means, medians, standard deviations, percentages | Confidence intervals, test statistics, p-values |
| Uncertainty | None from sampling | Built in, because a different sample would give different numbers |
| Pizza survey example | 70% of the 100 people chose pizza | A 95% confidence interval of about 61% to 79% for the whole city |
In a dissertation, you’ll often need both, depending on your research aims. The descriptive statistics come first in your results chapter, and they also tell you which inferential tests your data can support, because many tests assume a particular shape of data. Our guide to descriptive statistics covers that first step in detail.
How do inferential statistics work?
Every inference starts from one awkward fact: a different sample would give you a different answer. Survey another 100 people in the same city, and you might get 66% or 73% instead of 70%. That gap between what your sample shows (a statistic) and the true value in the population (a parameter) is called sampling error, and it happens even with a perfectly random sample.
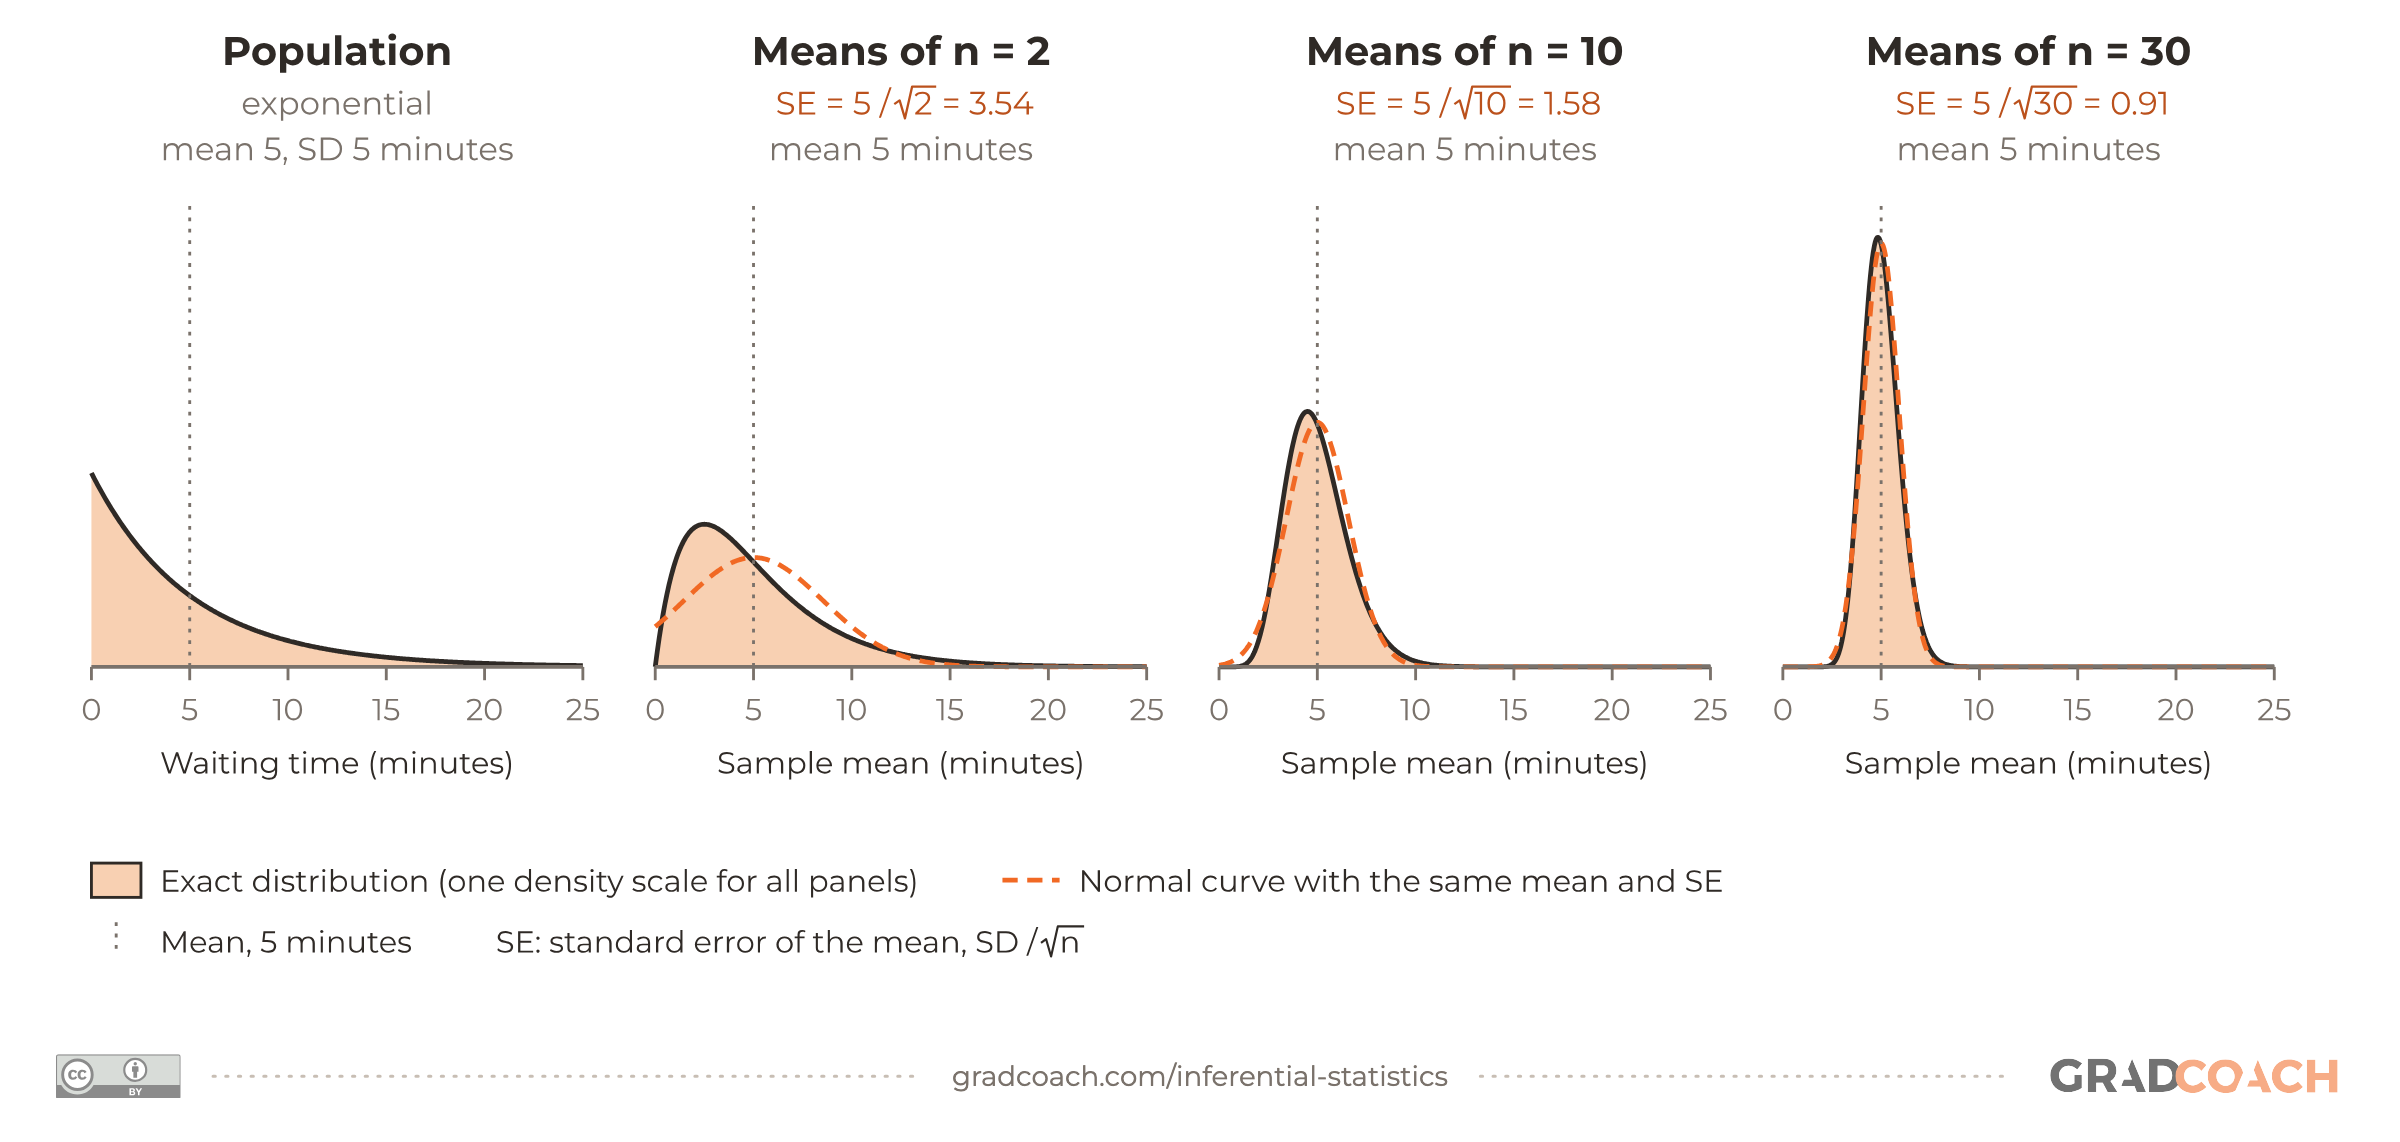
What makes inference possible is that sampling error behaves predictably. If you could draw sample after sample of the same size and calculate the mean of each, those means would cluster around the population mean. As the OpenStax statistics textbook explains, “those means tend to follow a normal distribution”, and they follow it more closely as the samples get bigger.
That’s the central limit theorem. It also holds when the data themselves are skewed (bunched up at one end, with a long tail of less common values stretching out toward the other), as long as the samples are large enough.
The drawing below shows it with waiting times, which are strongly skewed (most waits are short, a few are long):

Notice two things. Every panel has the same mean, 5 minutes, and the spread of the means shrinks as the sample grows: from 3.54 minutes with samples of two to 0.91 with samples of 30. That spread is the standard error of the mean, the standard deviation divided by the square root of the sample size, and almost every confidence interval and test you’ll run is built on a standard error.
Estimation and confidence intervals
The first job of inferential statistics is estimation. Your sample statistic (70% chose pizza) is your best single guess at the population value, and a confidence interval puts a range around it that reflects sampling error. For the pizza survey, a 95% confidence interval runs from about 61% to 79%.
Be careful how you read that range: in our coaching, it’s one of the numbers students misread most often. It doesn’t mean there’s a 95% chance the true figure sits between 61% and 79%. One widely cited guide to statistical misinterpretations is blunt about it: the true value is either inside a given interval or it isn’t. Its authors spell out what the 95% does refer to:
In other words, the 95% describes the method, not your particular interval.
What a confidence interval does tell you, at a glance, is precision. A narrow interval says your estimate is tight; a wide one says your sample left a lot of room for doubt.
Hypothesis testing and p-values
The second job is testing. You start from a null hypothesis: the default claim your test looks for evidence against. Usually that’s no effect, no difference or no relationship in the population, but it can also be a specific benchmark value. For the pizza survey, a natural benchmark is half, the line between a majority favorite and a minority one, so the null is that pizza is the favorite of exactly 50% of the city.
Your test then produces a p-value, which measures how surprising your result would be in a world where the null hypothesis (and the test’s assumptions) holds: it’s the probability of getting a result at least as extreme as yours. The smaller the p-value, the more surprising. Getting 70 out of 100 when you’d expect 50 would be very surprising (p < .001), so you’d reject the null.
Most social science and health research calls a result statistically significant when p falls below .05, though that threshold is a convention, not a law. If you’re interested, our explainer on what a p-value means covers the thresholds and how to report them.
Two misreadings come up most often in our coaching.
The first is mistaking significance for importance: the American Statistical Association’s statement on p-values warns that a p-value “does not measure the size of an effect or the importance of a result”, which is why you report an effect size beside it.
The second is reading a non-significant result as proof of no effect. The misinterpretations guide lists that reading among its fallacies, because a definitive conclusion of no association “cannot be deduced from a P value, no matter how large”. A study can simply be too small to detect a real effect, which is what checking statistical power before you collect data is for.
“So do I need a confidence interval or a test?”
Usually both, because they answer different questions. The test tells your committee whether there’s evidence of an effect; the interval and the effect size tell them how big it plausibly is. I’d go further: a results chapter that reports only p-values has answered the less useful of the two.
The most common inferential tests
There are many inferential tests, and the right one depends on your research question and your data. The five below are the ones you’re most likely to meet in a dissertation. They split into tests of difference (t-tests, ANOVA and chi-square) and tests of relationship (correlation and regression).
This isn’t a complete list, and each test comes with assumptions that your data need to meet. If you’re choosing one for your own study, our guide to choosing the right statistical test walks through the decision.
T-tests
A t-test compares the means (averages) of two groups to see whether the difference between them is bigger than chance would produce. That matters because two means can differ by a few points simply because of who happened to land in each group. The t-test weighs the gap between the means against how much the scores vary within each group and how many scores each group has, so a difference counts for more when the scores are tightly bunched and the groups are large.
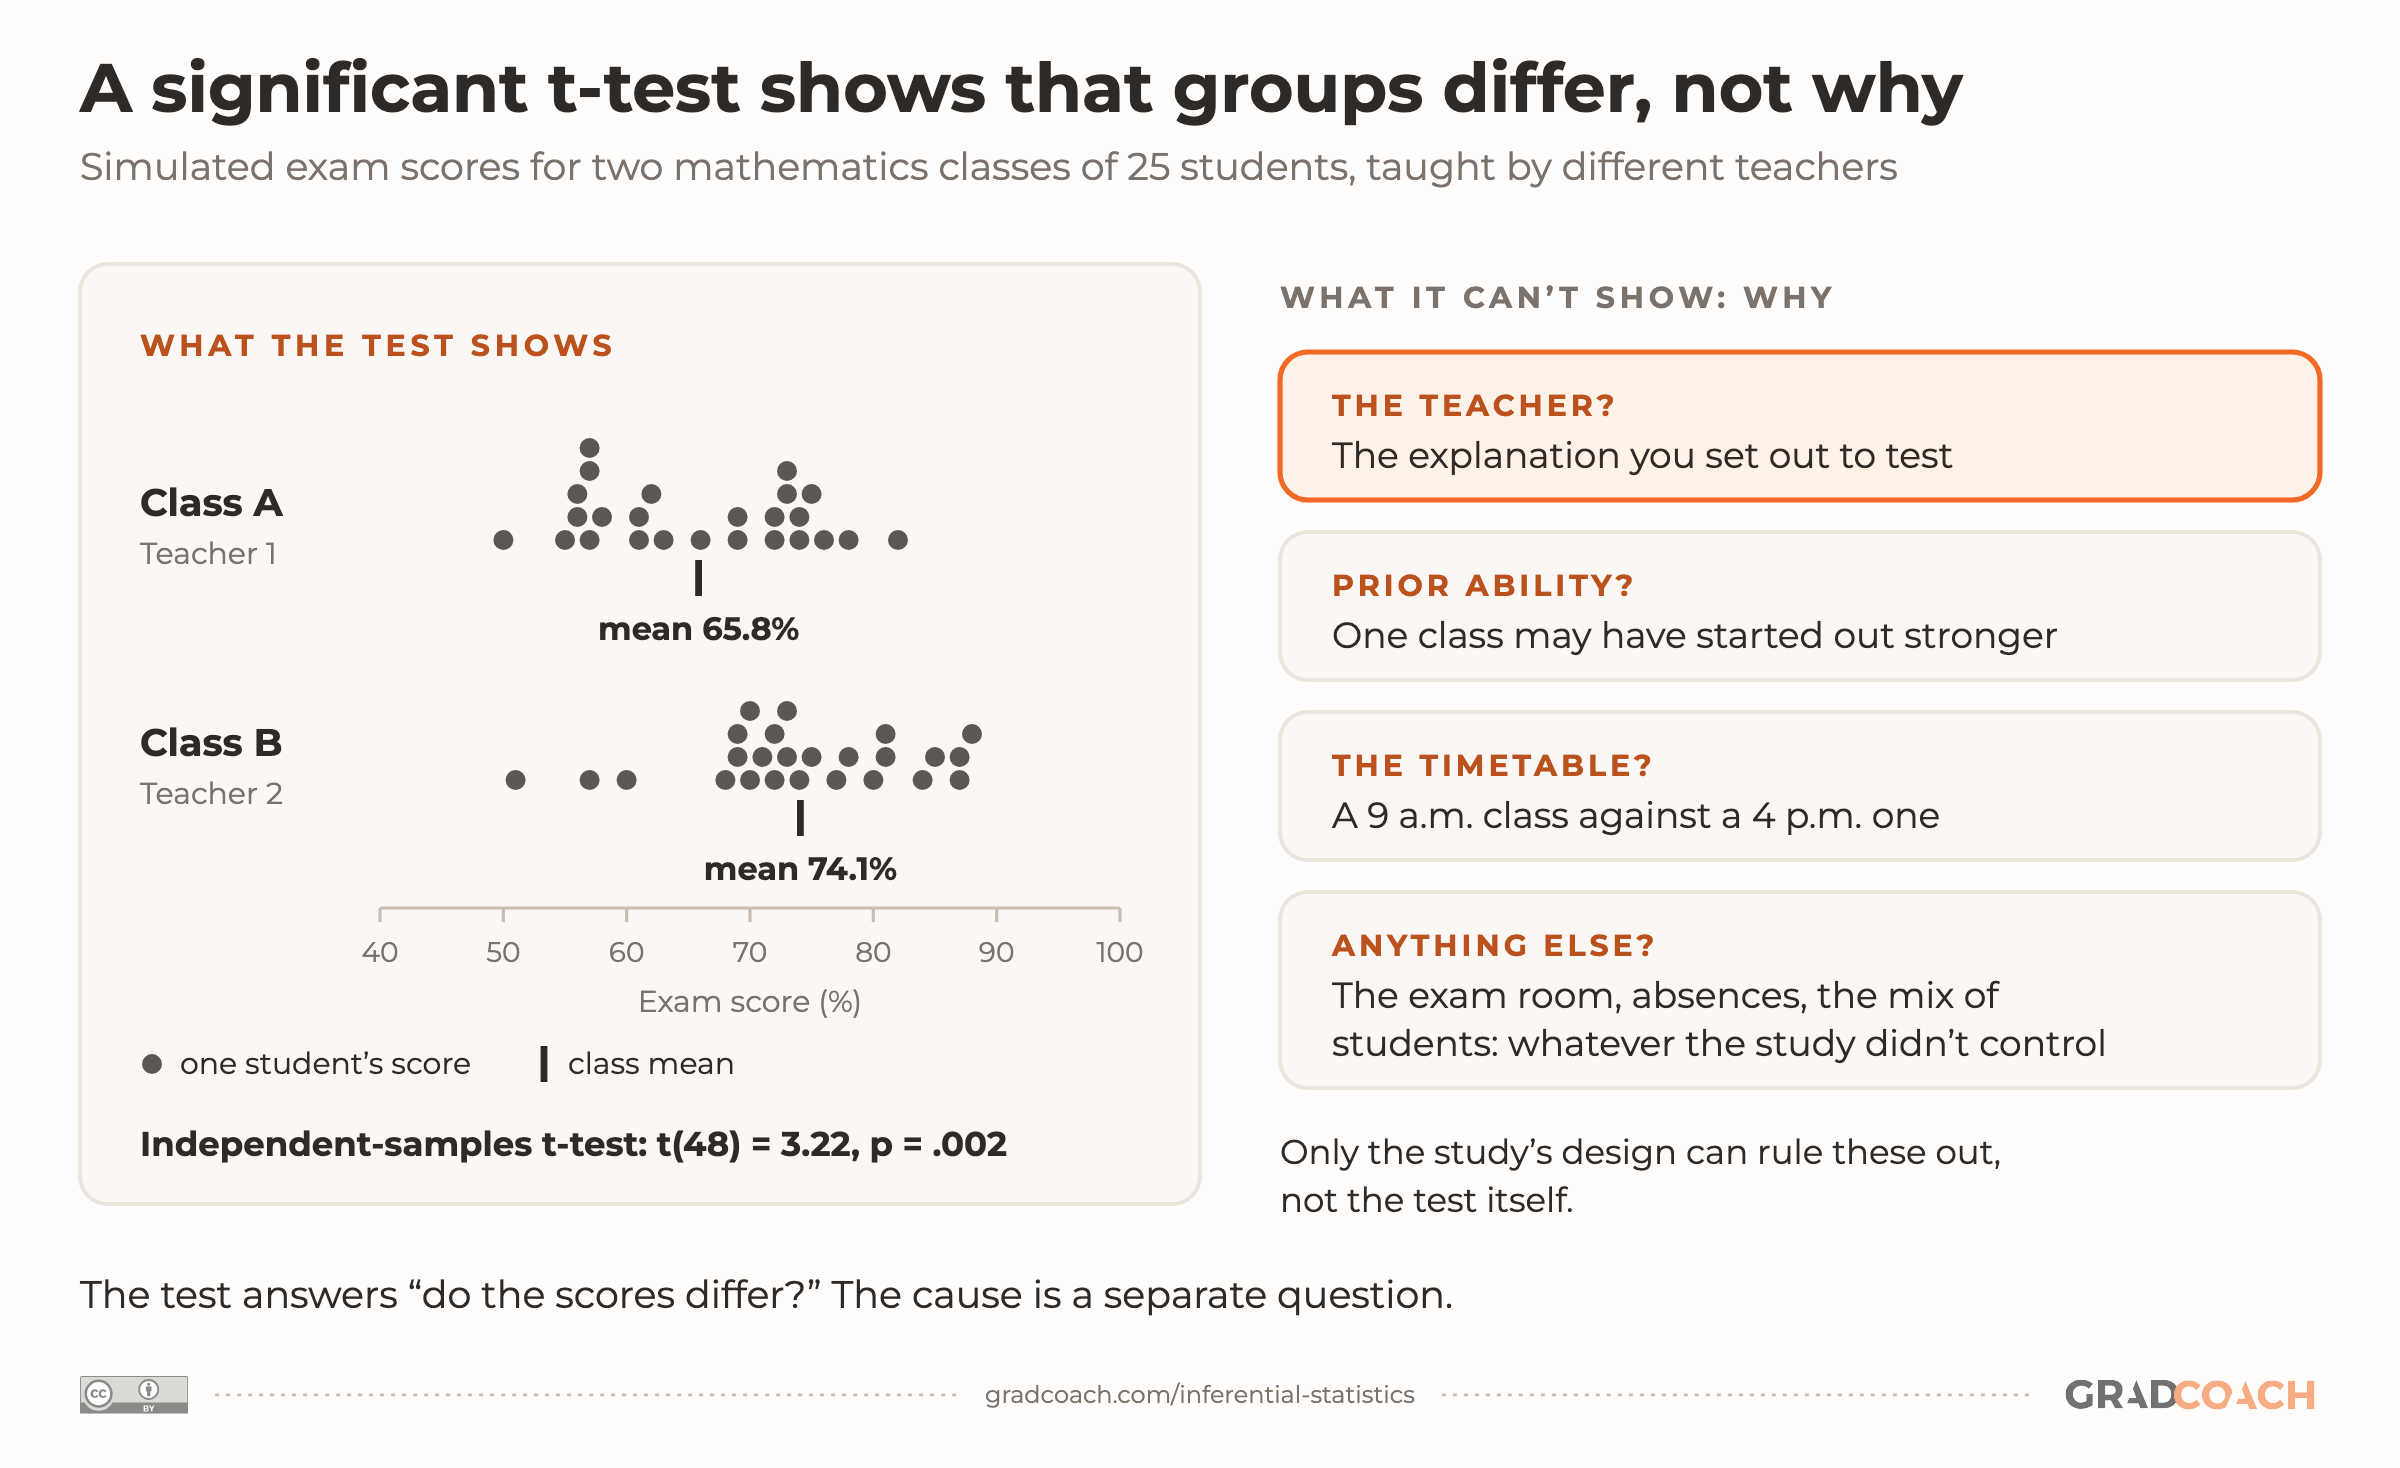
For example, you might use a t-test to see whether there’s a statistically significant difference between the exam scores of two mathematics classes taught by different teachers. A significant result tells you the gap between the classes is unlikely to be chance alone. Whether the teaching method caused that difference is a separate question, and it depends on how the study was designed: the classes might also differ in ability, timetable or anything else you didn’t control.
Here’s that example with some simulated scores:

There are three main types of t-test. The one-sample t-test compares one group’s mean with a fixed value, such as a national average. The independent-samples t-test compares two separate groups, like the two classes. The paired-samples t-test compares the same people measured twice, such as before and after a training course.
The extract below, from a clinical psychology doctorate, gives a clean paired example. Its 418 participants were UK professionals who hear about other people’s trauma at work: doctors, paramedics, psychologists, nurses, counselors and others. Of those, 318 completed a measure of vicarious trauma, the TMVT, twice, about two weeks apart. Watch what it reports beyond the p-value:
The result isn’t significant (p = .437), and the passage doesn’t stop there. It gives the size of the difference (0.87 points) and an effect size (Cohen’s d of .04, far below the 0.2 usually treated as small), and those two numbers point toward the group average holding steady over the two weeks.
If one of your own tests comes back non-significant, report it the same way: the statistic, the p-value and the effect size, never just “no difference was found”. And if a non-significant result has thrown your plans, the video below covers what to do next:
ANOVA
While a t-test compares the means of two groups, an ANOVA (analysis of variance) compares the means of three or more groups at once. Again, it assesses whether the differences between the means are bigger than chance alone would produce.
For example, if you wanted to know whether students’ test scores vary with the type of school they attend (public, private or homeschool), you could use ANOVA to compare the average standardized test scores of the three groups. Similarly, you could compare the average sales of a product across several stores to see whether sales differ by location.
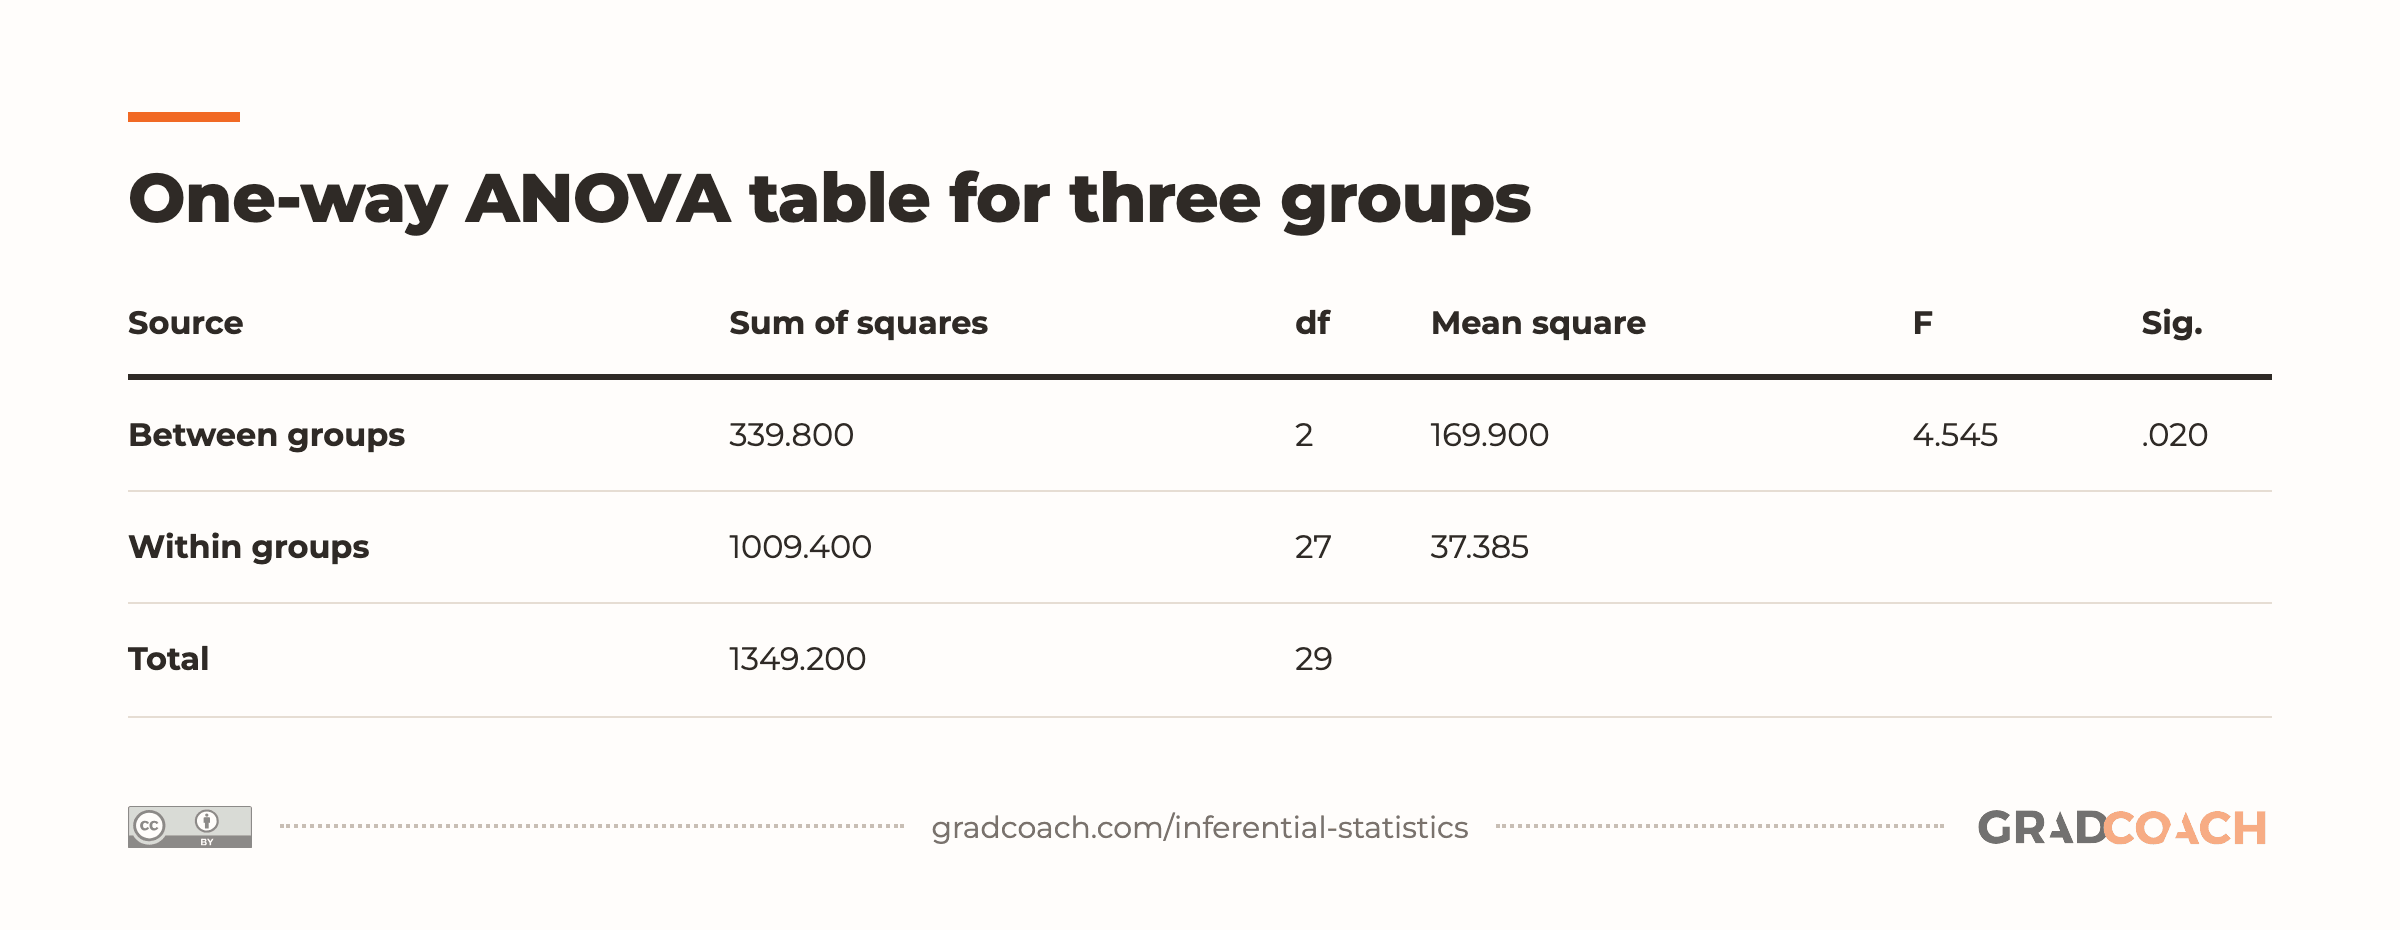
Here’s the kind of table SPSS produces for a one-way ANOVA, in this case for 30 people split into three groups (the data are illustrative):
| Source | Sum of squares | df | Mean square | F | Sig. |
|---|---|---|---|---|---|
| Between groups | 339.800 | 2 | 169.900 | 4.545 | .020 |
| Within groups | 1009.400 | 27 | 37.385 | ||
| Total | 1349.200 | 29 |
The F value is the ratio of the two mean squares (169.900 divided by 37.385): how much the group means vary compared with how much individuals vary within their groups. The “Sig.” column is the p-value. In APA style, you’d report this as F(2, 27) = 4.54, p = .020 (the exact ratio is 4.5446, which SPSS shows as 4.545). Since .020 is below .05, you’d conclude there’s evidence that at least one group mean differs from the others.
Add an effect size too. Eta squared (η²) is the between-groups sum of squares divided by the total: 339.8 / 1349.2 = .25, so about a quarter of the variation in scores lies between the groups.
What the ANOVA doesn’t tell you is which groups differ. For that, you follow it with post hoc tests, or planned comparisons between pairs of groups. Our quantitative data analysis guide walks through a real dissertation that follows its ANOVA with pairwise tests.
In these examples, we’re talking about a one-way ANOVA, which has one grouping variable. There are other types for other designs, such as the repeated-measures ANOVA for the same people measured three or more times, so check which one fits your study before you run it.
Chi-square
While t-tests and ANOVA compare means, the chi-square test works with categories. In its most common form, the chi-square test of independence, it assesses whether two categorical variables are related, such as sex and handedness. If you’re unsure what makes a variable categorical, this guide to data types covers it.
A second form, the goodness-of-fit test, checks whether the counts for one variable match an expected pattern. That’s the test behind the pizza survey: 70 against the 50 you’d expect under a null hypothesis that pizza is the favorite of exactly half the city.
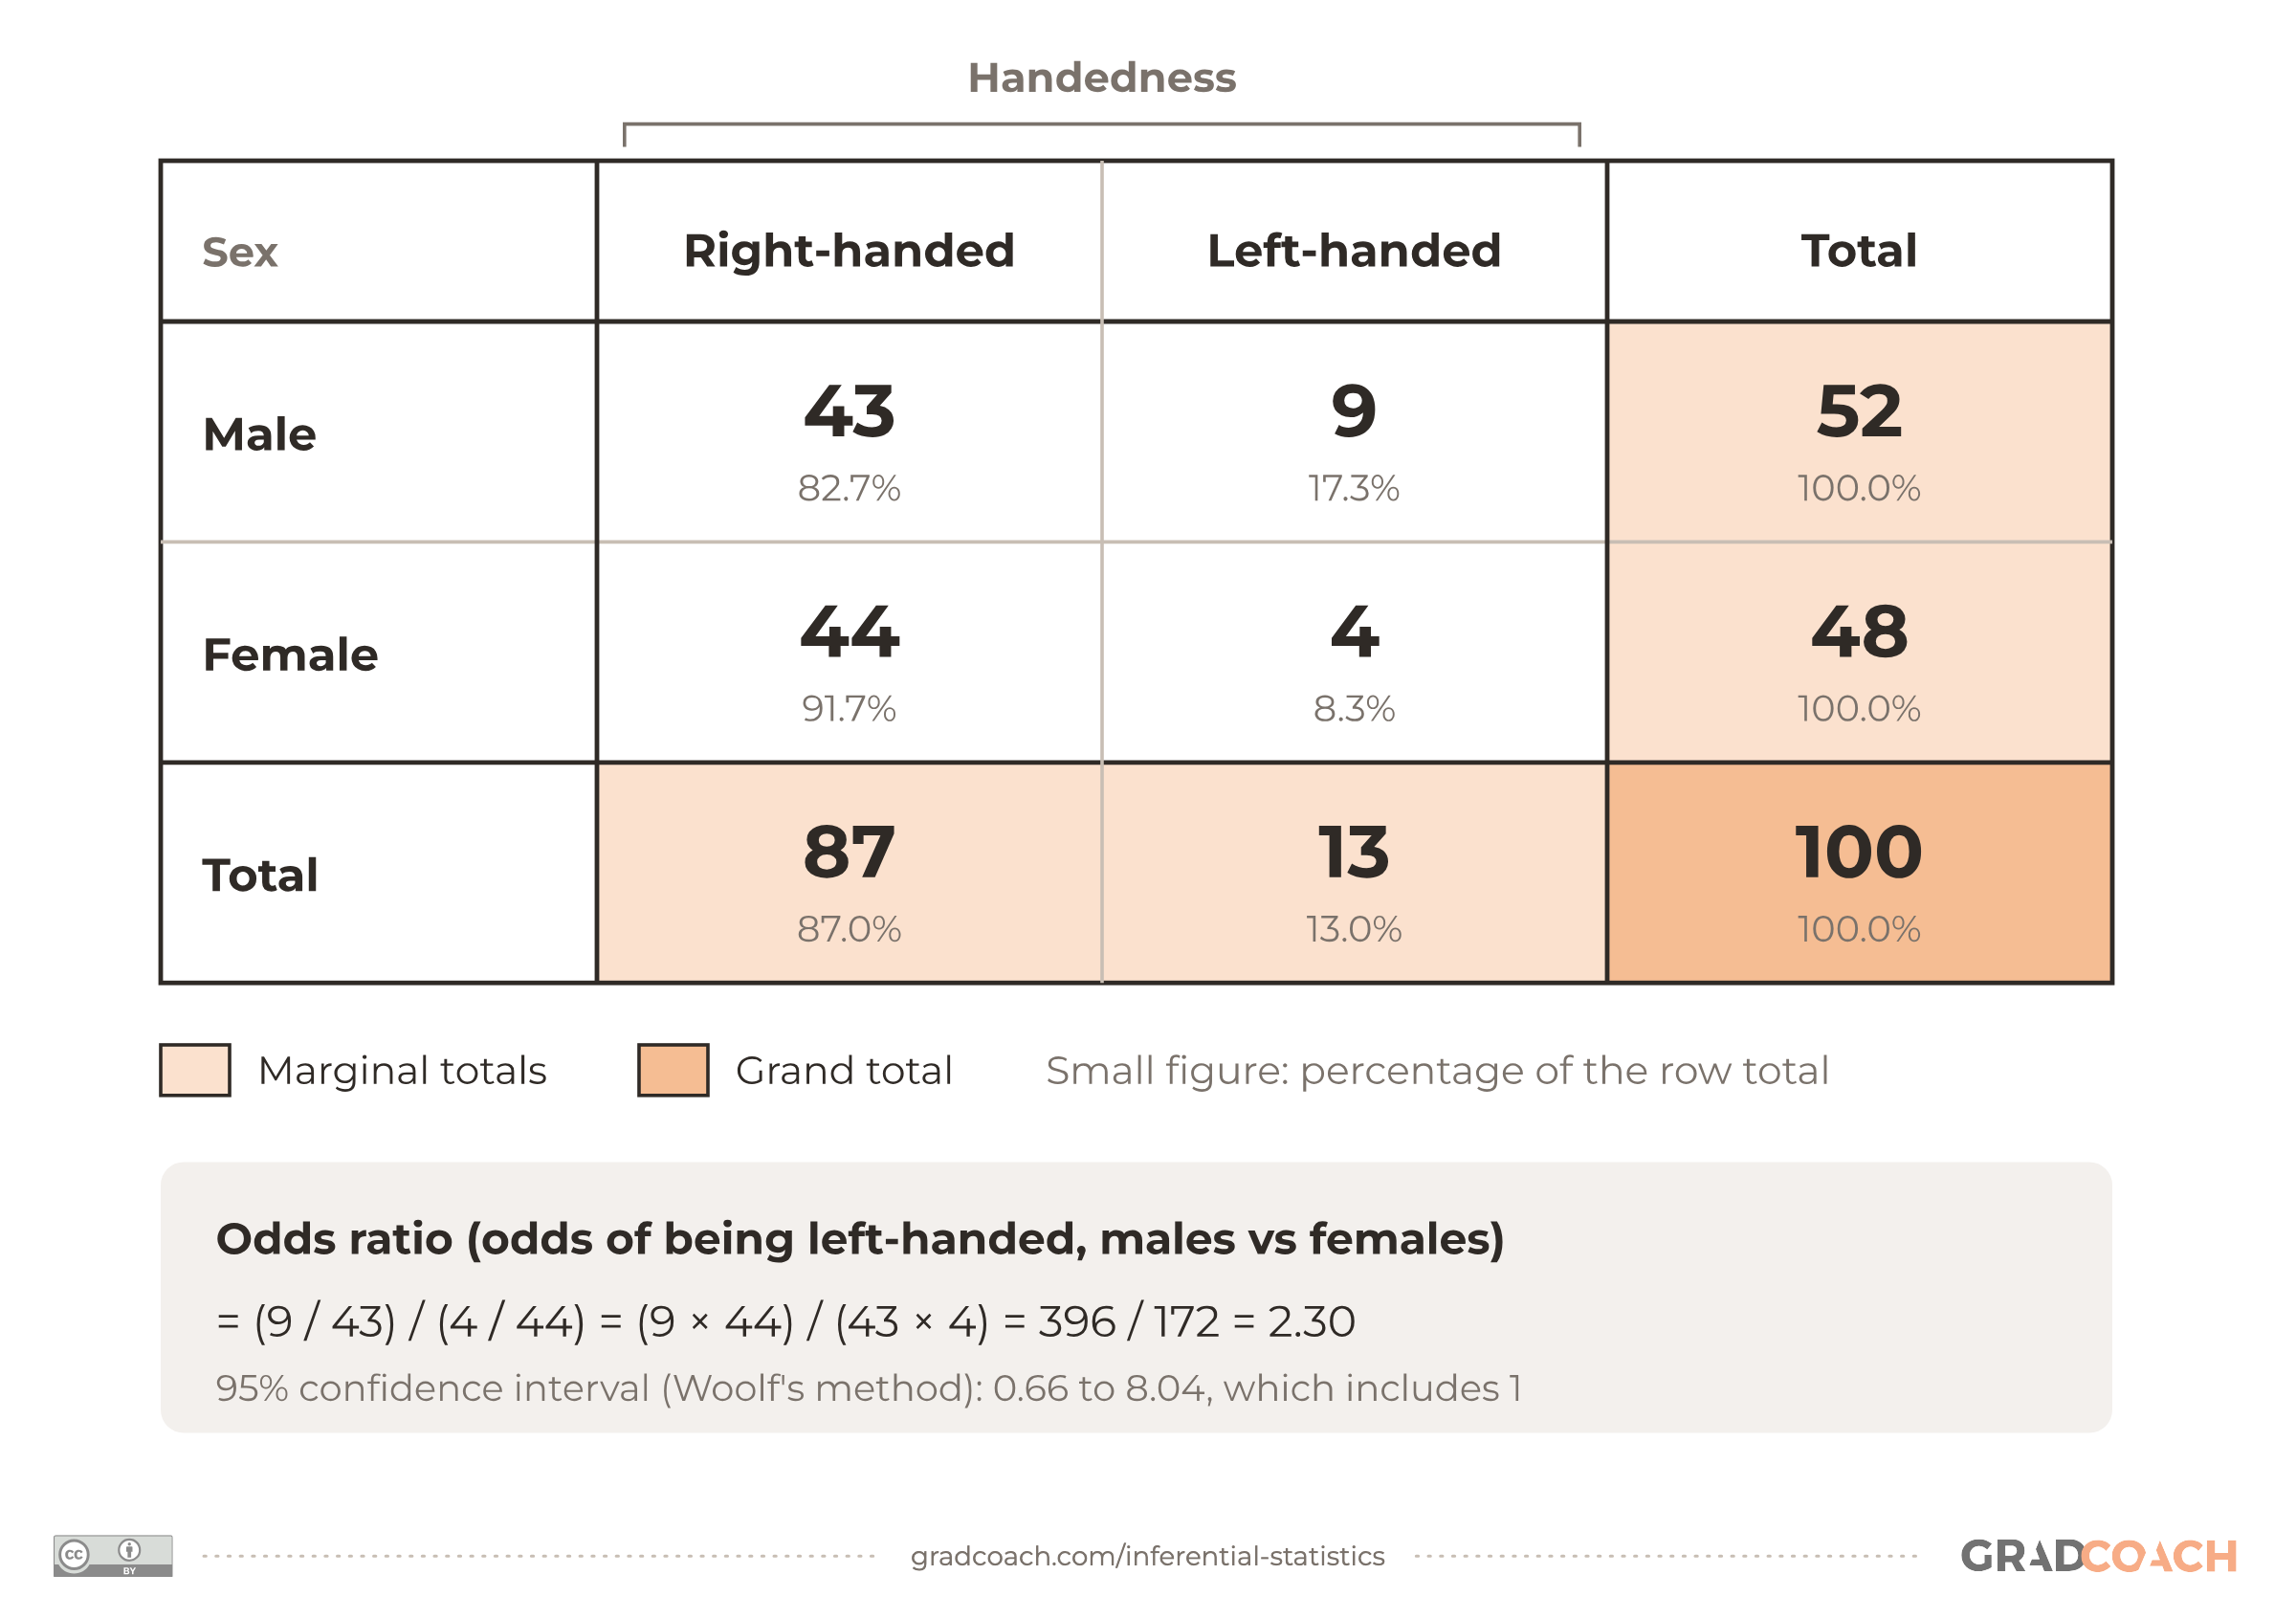
A chi-square test of independence starts from a contingency table (a cross-tabulation) of counts, like this one of sex against handedness for 100 people:

Left-handedness is twice as common among the men here (17.3% against 8.3%), but with only 13 left-handed people in the sample, that gap could easily be chance. A chi-square test of independence on these counts says as much: χ²(1, N = 100) = 1.78, p = .18 (Pearson’s version, without a continuity correction), with every expected count above 5, so the difference isn’t significant.
The drawing looks at the same gap a second way, through the odds ratio worked on the table: 2.30, with a 95% confidence interval of 0.66 to 8.04. Because that interval includes 1 (equal odds), the two views agree: the sample gives no clear evidence of a difference.
Let’s look at a real-world example. This Doctor of Nursing Practice project from UMass Amherst tested whether the share of patient records showing a health care proxy (HCP) rose after a nurse-led intervention on a hospital unit. Its 687 records with usable proxy data form a 2 × 2 table (before or after, proxy present or absent), so this is a test of independence, chosen because each record simply did or didn’t show a proxy (nominal data). Look at how the result is stated:
The project’s own table shows the counts behind it: 69.0% of the 403 pre-intervention records with usable proxy data showed a proxy, against 76.1% of the 284 post-intervention ones. The two periods involve different patients, so a before-and-after comparison like this can’t, on its own, show that the intervention caused the rise.
Notice the shape of the result: the test, its degrees of freedom and sample size in parentheses, the statistic and the p-value, after a sentence saying what was tested. Report yours in that order. I’d also give the percentages in the text, so your reader can see the size of the change and not just that it’s significant, and add an effect size such as phi, which here works out at about .08, a small effect.
Correlation
Correlation analysis looks at the relationship between two numerical variables to assess whether they move together. The result is a correlation coefficient, usually Pearson’s r, a number between -1 and 1. A value close to 1 means the two variables tend to rise together, a value close to -1 means one tends to fall as the other rises, and a value close to zero means there’s no clear straight-line relationship.
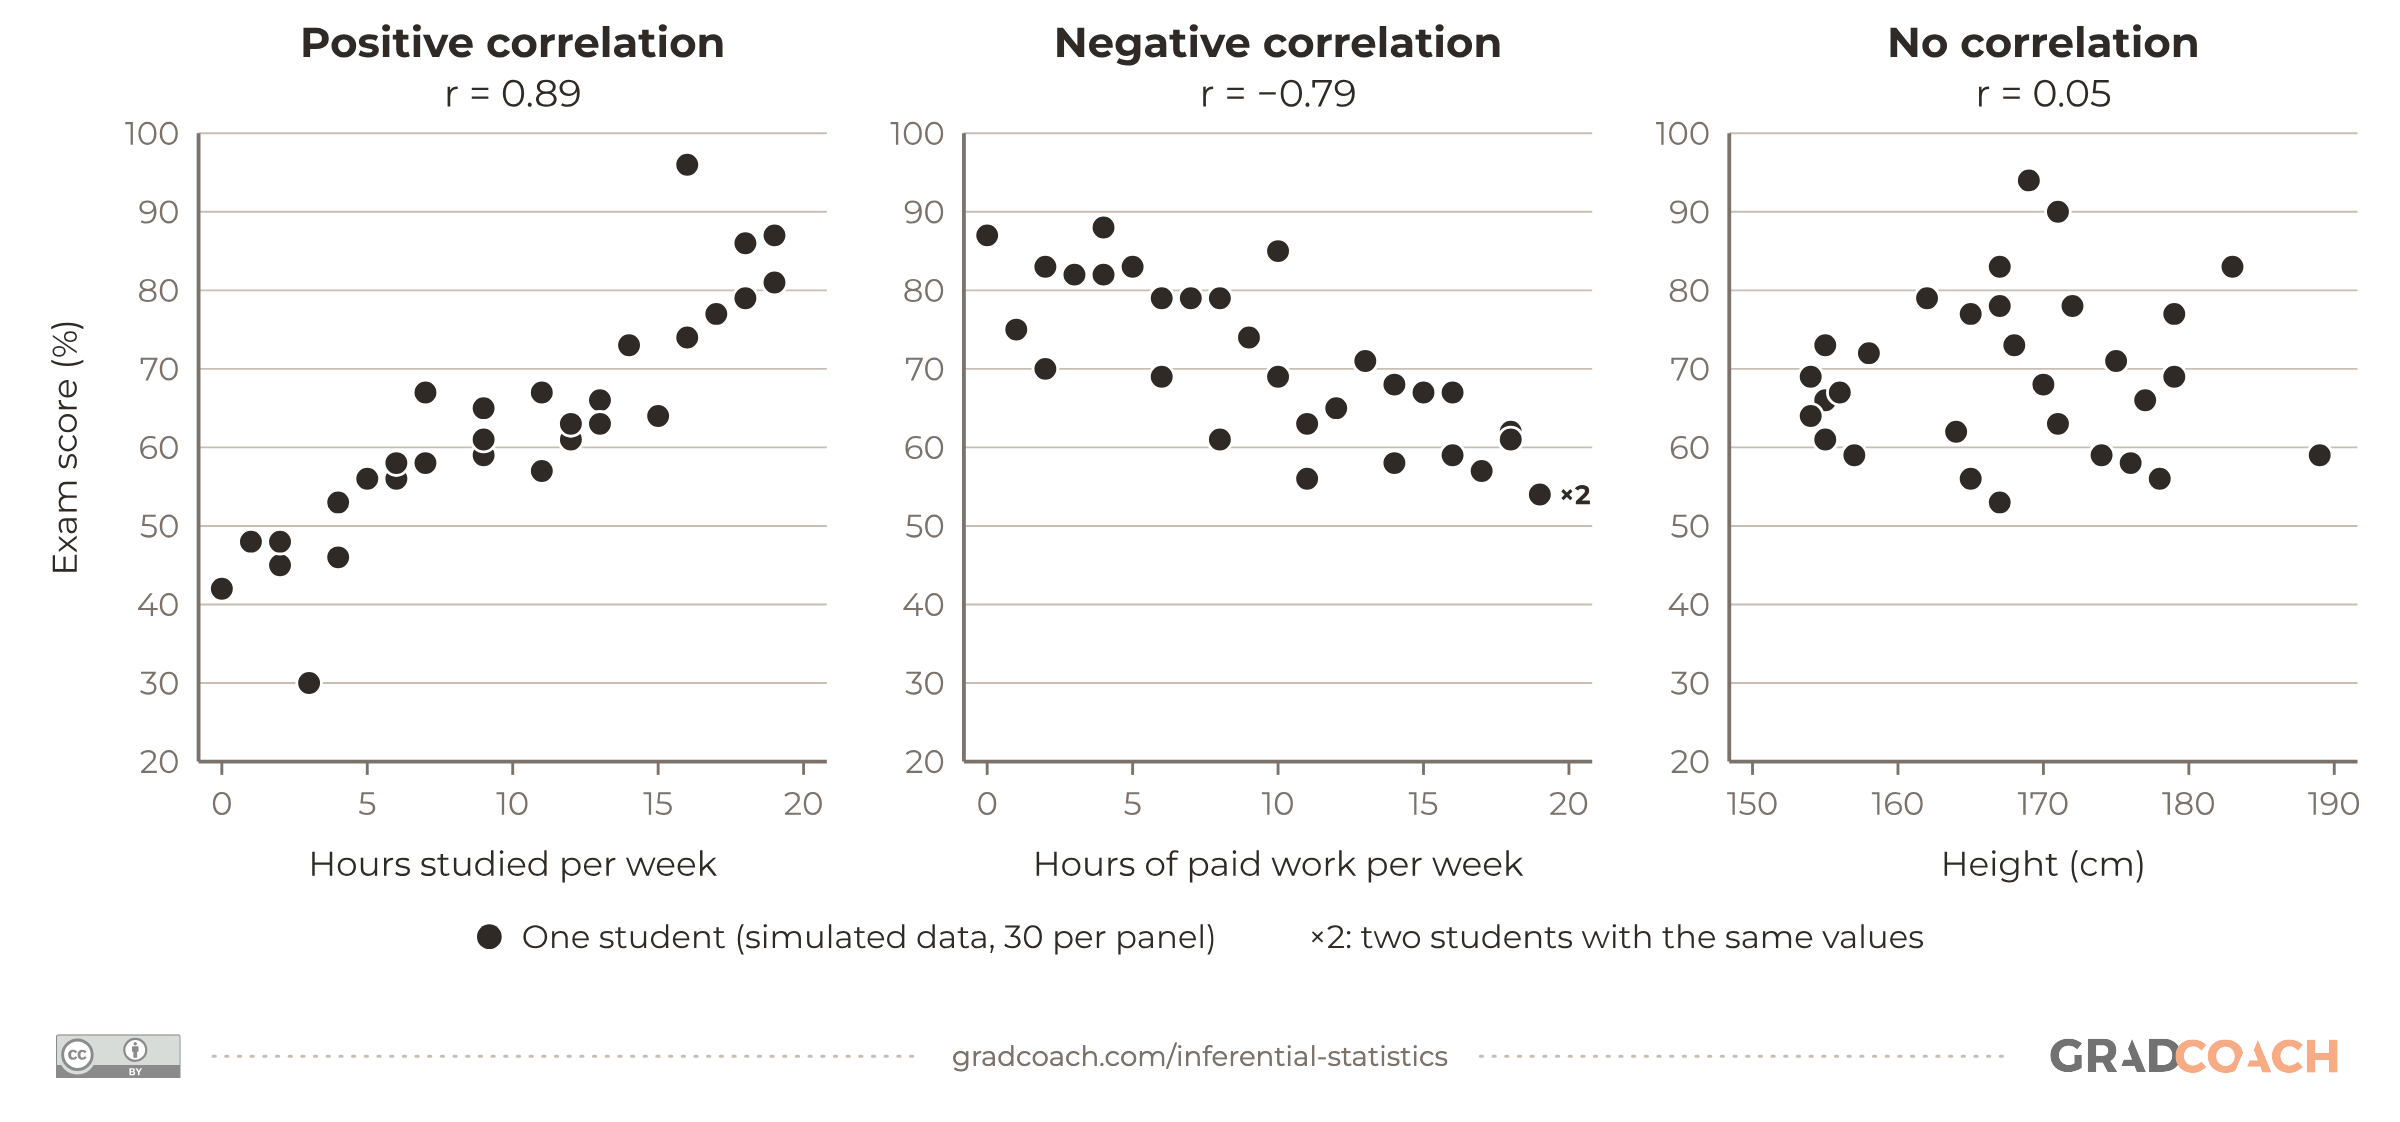
For example, you might find that the more hours students spend studying, the higher their exam scores tend to be (a positive correlation), and that the more hours they spend in paid work, the lower their scores tend to be (a negative correlation):

One caution the no-correlation panel hides: an r near zero rules out only a straight-line relationship, and a curved one can produce it too.
On its own, r only describes your sample; it becomes inferential when you test whether the relationship holds in the population, which is where the p-value beside it comes from. Both halves show up in an education PhD from Purdue, which surveyed undergraduates about their teachers’ practices and their own confidence in their academic ability (academic self-efficacy). Notice what it adds after the p-value:
The passage names the strength in words (“moderate”), gives r, the sample size and the p-value, then squares r (.47 × .47 ≈ .22) to say how much of the variation the relationship accounts for. That last step is worth following, because with 921 students, even a weak correlation would come out significant. Just be careful with the word “explained”: it’s statistical shorthand for shared variance, not a claim that one variable causes the other.
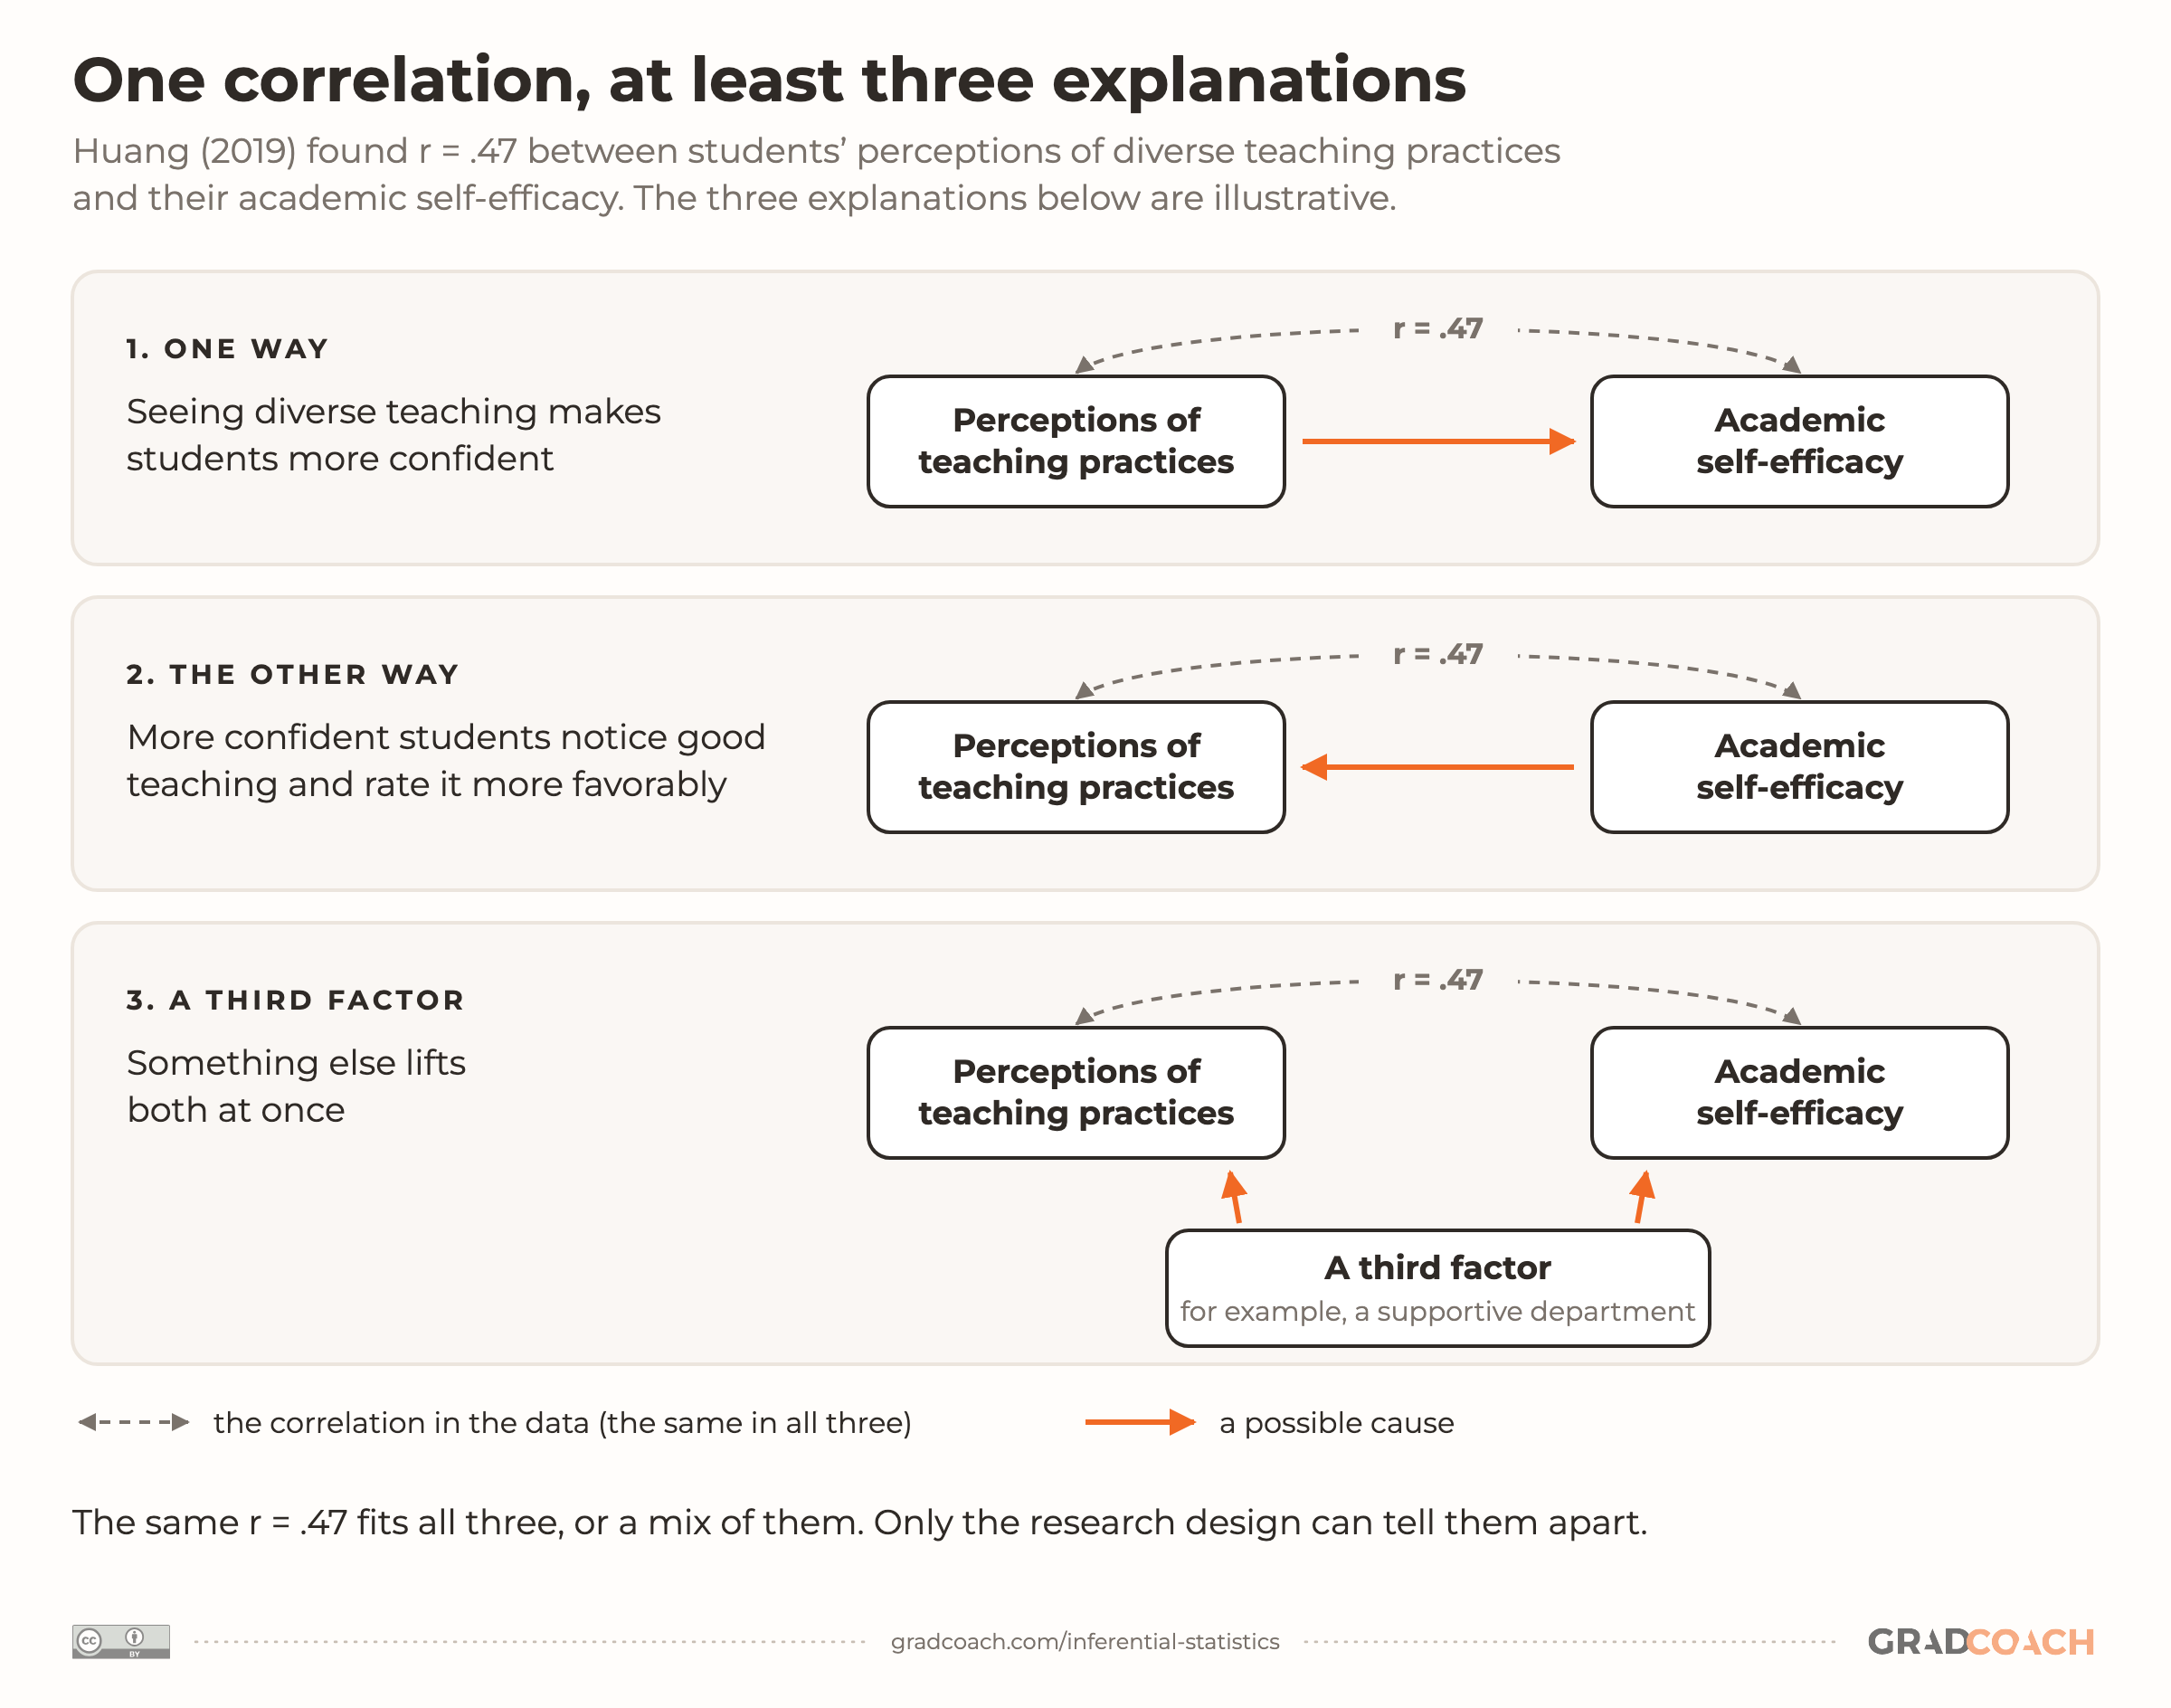
That’s the point to hold on to in your own write-up: correlation can show you how two variables are related, but it doesn’t prove that one causes the other. The same r = .47 fits at least three different stories:

Regression
While correlation shows whether two numerical variables are related, regression goes a step further by letting you predict the value of one variable (the dependent variable) from the values of one or more others (the independent variables).
For example, you could use regression analysis to predict house prices from the number of bedrooms, the location and the age of the house. The analysis gives you an equation that lets you plug in those factors to estimate a house’s price. Similarly, you could predict a person’s weight from their height, age and daily calorie intake.
In these examples, we’re talking about multiple regression, because there’s more than one independent variable. There are many other types, including simple linear regression (one predictor) and logistic regression (an outcome with two categories, such as pass or fail). The kind of outcome variable you have largely decides which one fits.
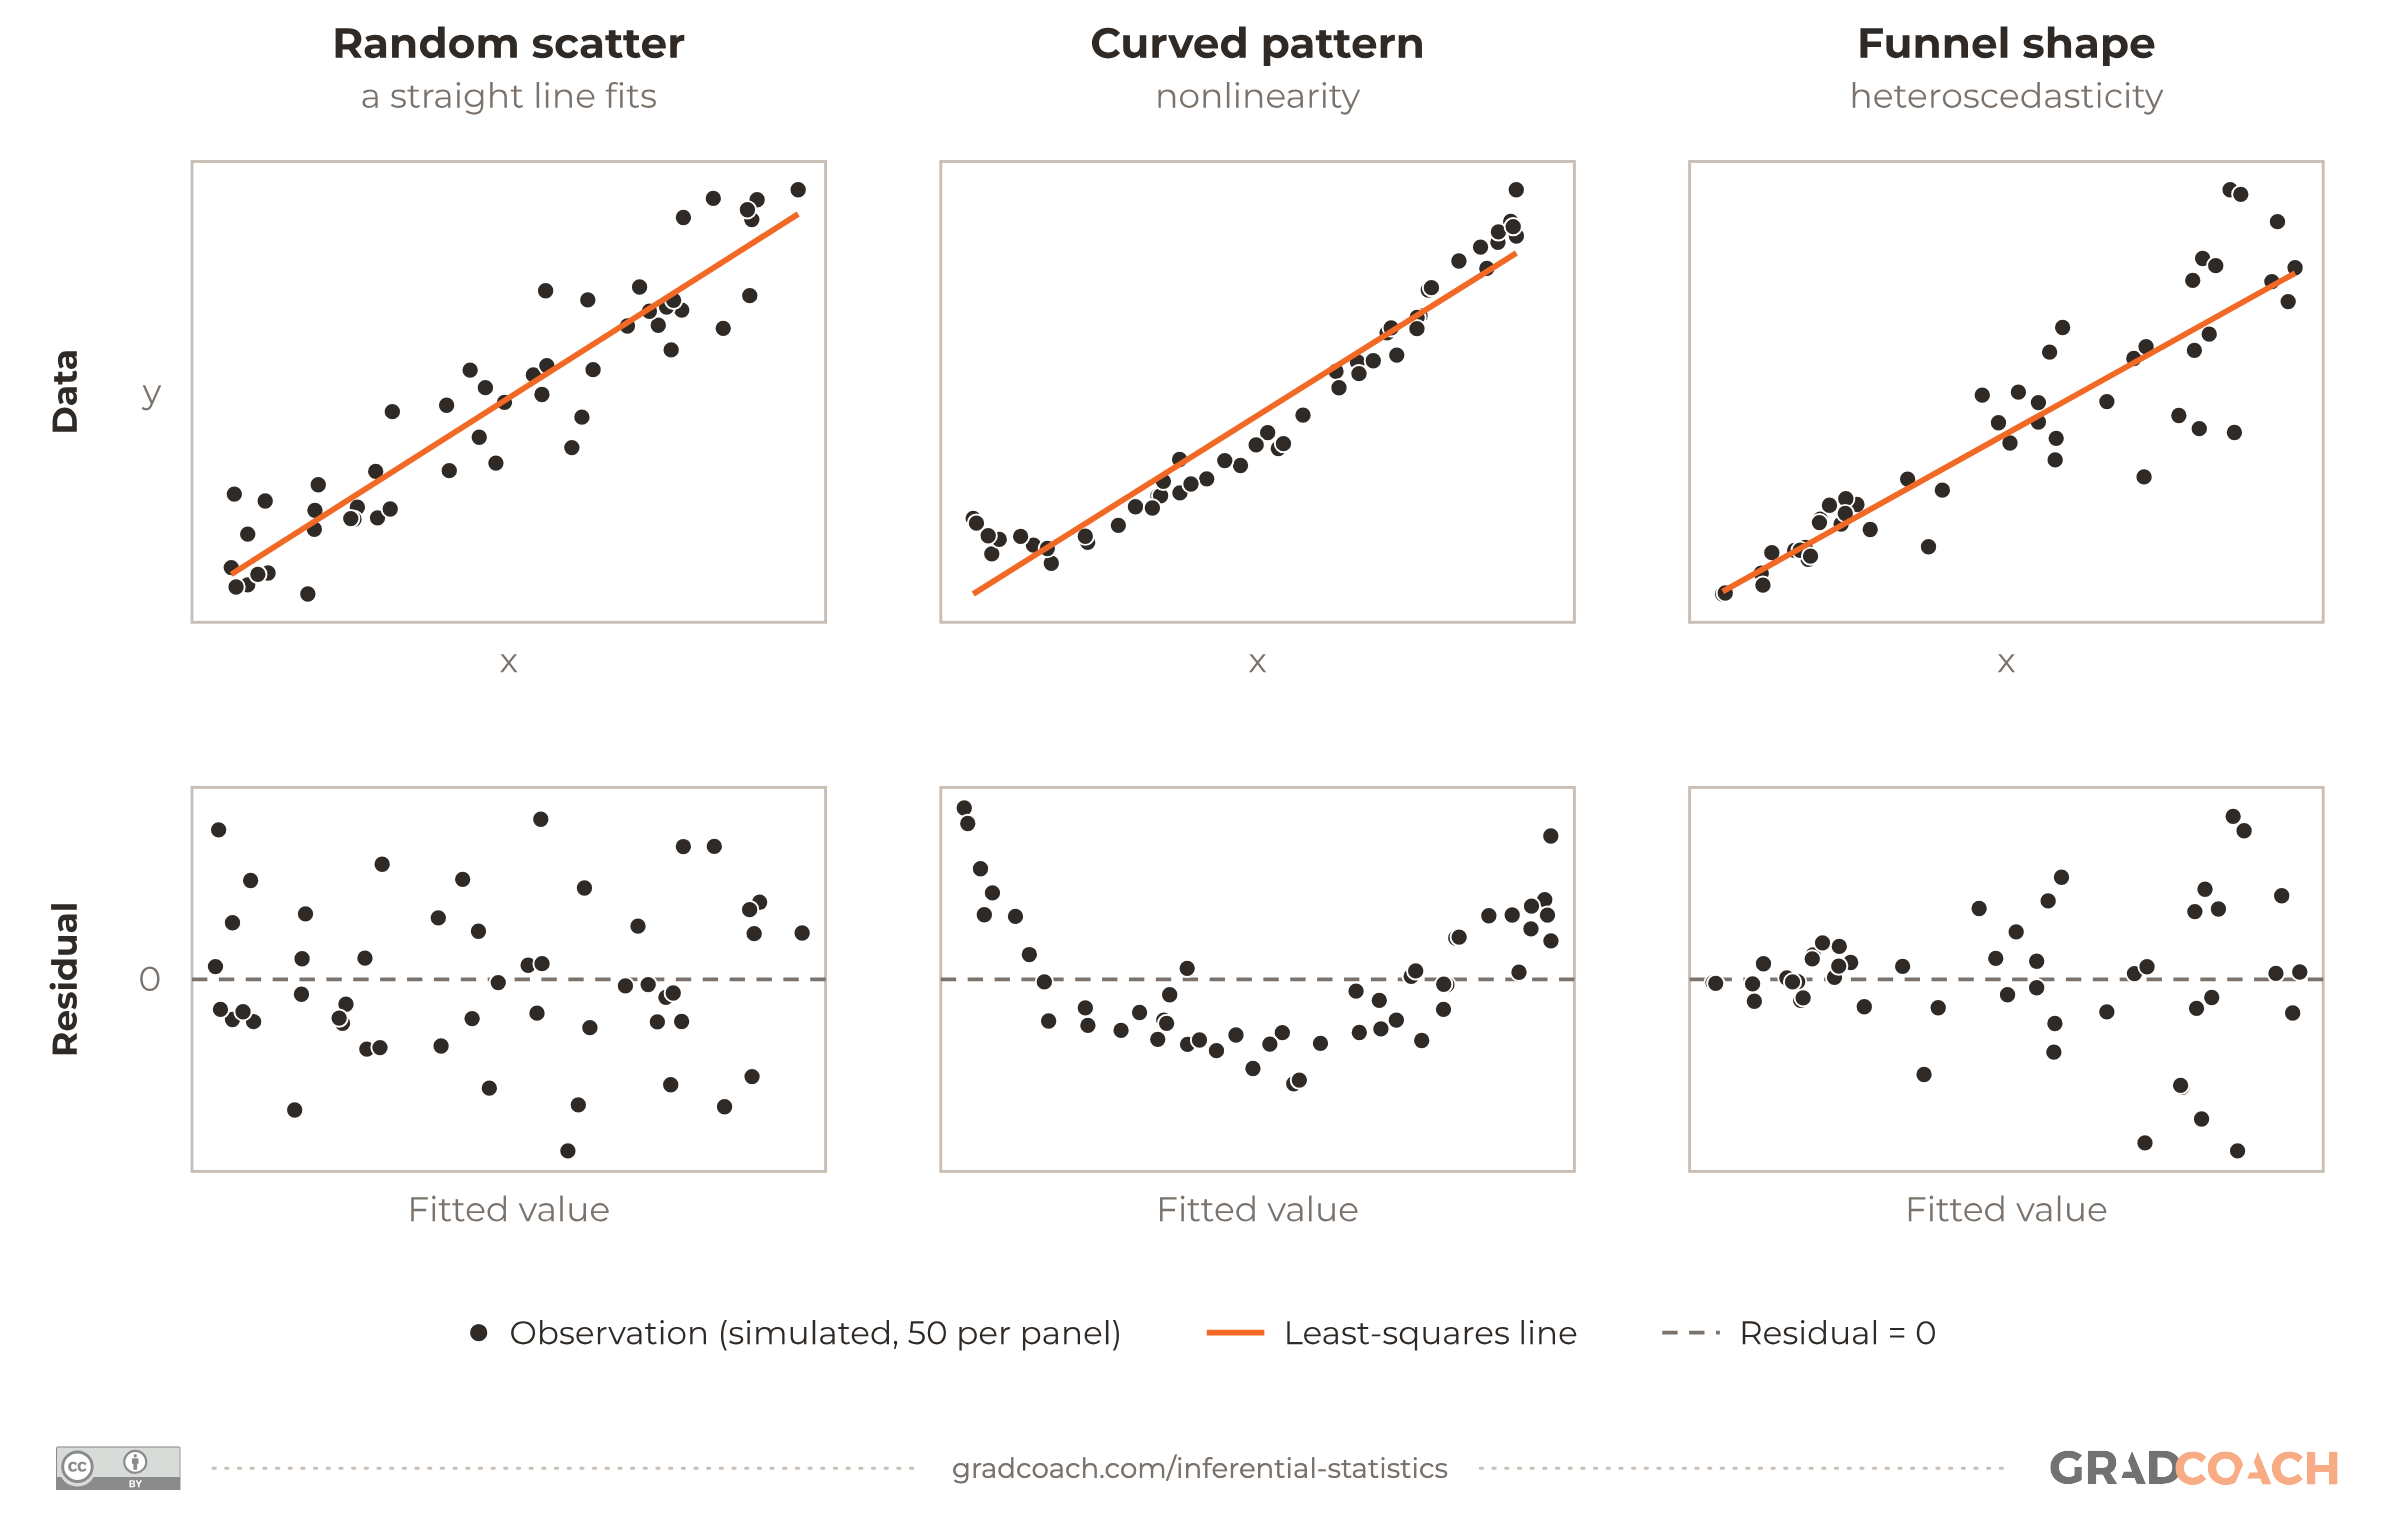
Before you trust a regression, check its residuals: the gaps between each observed value and the value the model predicts. Plot them against the fitted values (the model’s predictions). A straight-line model that fits should leave a random, even band of residuals around zero. A curve or a funnel tells you something’s wrong, as these residual plot examples show:

If your own plot shows a curve, the relationship probably isn’t a straight line; a funnel means your significance tests may be less trustworthy than they look.
As with correlation, regression alone doesn’t prove causation: factors you haven’t included could be driving the results, and a causal claim needs a design that rules them out, such as a randomized experiment.
Each of these tests comes with its own assumptions and checks, and the tutorial video below covers six things you need to do when you work with inferential statistics:
Once your tests are run, the next job is writing them up, and our guide to writing up quantitative results covers the whole chapter, from your sample to your hypotheses.
Still have questions?
What is an example of inferential statistics?
Every test has one. A clinical trial uses a t-test to judge whether a new drug speeds recovery compared with a placebo; a school study uses ANOVA to compare test scores across three types of school; a hospital project uses a chi-square test to check whether proxy completion differs before and after an intervention; and an education survey uses correlation to measure how closely students’ views of their teaching track their confidence in their own ability. Each one uses a sample to say something about a wider population.
How do descriptive and inferential statistics differ?
The difference is uncertainty. Descriptive statistics, such as a mean or a percentage, describe the data you collected, with no sampling uncertainty attached. Inferential statistics reach beyond that data to a population you didn’t fully measure, so every result comes with uncertainty, expressed as a confidence interval or a p-value, because a different sample would have given different numbers.
Is correlation descriptive or inferential?
It can be either. A correlation coefficient such as Pearson’s r is descriptive when it simply summarizes how two variables move together in your sample. It becomes inferential when you test whether the relationship is likely to hold in the population, which gives you a p-value or a confidence interval alongside r.
Is a z-score descriptive or inferential?
A z-score on its own is descriptive: it tells you how many standard deviations a single value sits above or below the mean of its distribution. The same standardizing idea is used inside inferential methods, though, such as the z-test and the critical values behind many confidence intervals.
Are inferential statistics hard to learn?
The calculations are rarely the hard part, since software does them for you. What takes practice is the logic: choosing a test that fits your research question and data, checking its assumptions, and reading the output correctly. If you understand sampling error, confidence intervals and what a p-value does and doesn’t mean, most tests follow the same pattern.
What are the limitations of inferential statistics?
Inferential statistics are only as good as the sample behind them, so a biased or unrepresentative sample gives misleading conclusions, however careful the analysis. Results also carry uncertainty, tests make assumptions about the data that may not hold, and a significant result doesn’t show that an effect is large or that one variable causes another. Causal claims depend on the research design.
Can’t find your answer here? Ask a Grad Coach directly – the initial chat is free.
Speak with a friendly coach →


Cite-worthy sources
Cite this article
Jansen, D. (2023). What Are Inferential Statistics?. Grad Coach. https://gradcoach.com/inferential-statistics/
- Baldassari, J. (2026). Improving health care proxy procurement rates for hospitalized adults - A nurse led intervention [Doctor of Nursing Practice project, University of Massachusetts Amherst].
- Greenland, S., Senn, S. J., Rothman, K. J., Carlin, J. B., Poole, C., Goodman, S. N., & Altman, D. G. (2016). Statistical tests, P values, confidence intervals, and power: A guide to misinterpretations. European Journal of Epidemiology, 31(4), 337-350.
- Huang, Y. (2019). Undergraduate students’ perceptions of culturally responsive teaching and their sense of belonging and academic self-efficacy in higher education [Doctoral dissertation, Purdue University].
- Illowsky, B., & Dean, S. (2023). Introductory statistics 2e (Section 7.1). OpenStax.
- Purdue Online Writing Lab. (n.d.). Basic inferential statistics: Theory and application. Purdue University.
- Tunstall, C. M. (2026). Confirmatory factor analysis and further validation of the Trent Measure of Vicarious Trauma (TMVT) [Doctoral thesis, University of Lincoln].
- Wasserstein, R. L., & Lazar, N. A. (2016). The ASA statement on p-values: Context, process, and purpose. The American Statistician, 70(2), 129-133.
Found this helpful?
Keep us near the top of your Google results.