Nominal, Ordinal, Interval & Ratio:
A Plain-Language Explainer
What each level means for your analysis, with real examples


The 30-second summary
Nominal, ordinal, interval and ratio describe how much information your data’s values carry, from simple labels to true measurements.
- Nominal: categories with no order, such as blood type or yes/no answers.
- Ordinal: ordered categories with no set gap between them, such as education level or a single Likert item.
- Interval: equal gaps but no true zero, such as °C or year of birth.
- Ratio: equal gaps and a true zero, such as age in years or income.
Writing up your methods now? Our free methodology template walks you through the data analysis section, with space to justify each choice.
Navigate
Get your variables’ level of measurement wrong and every test you run on them inherits the mistake. A t-test on a variable that’s really ordinal, or a mean of categories that only look like numbers, gives you output that looks fine and means very little. In my experience, your committee (your examiners, in the UK) will spot it in the methodology chapter, where you’re expected to say what each variable is and why your analysis suits it.
We’ve helped 10,000+ students through their dissertations, and we’ve seen this trip people up far more often than it should. In this post, I’ll explain the four levels in plain terms, give you a simple way to tell which one your data is, and settle the cases that cause the most arguments, such as age, Likert scales and IQ. Along the way, you’ll see how three real dissertations stated their levels and chose their tests.
Levels of measurement 101
Every variable you collect sits at one of four levels of measurement, and that level decides what you can do with it in quantitative analysis. The labels come from the psychologist S. S. Stevens, who set them out in 1946 as four kinds of scale, and argued that each one permits a different set of statistics.
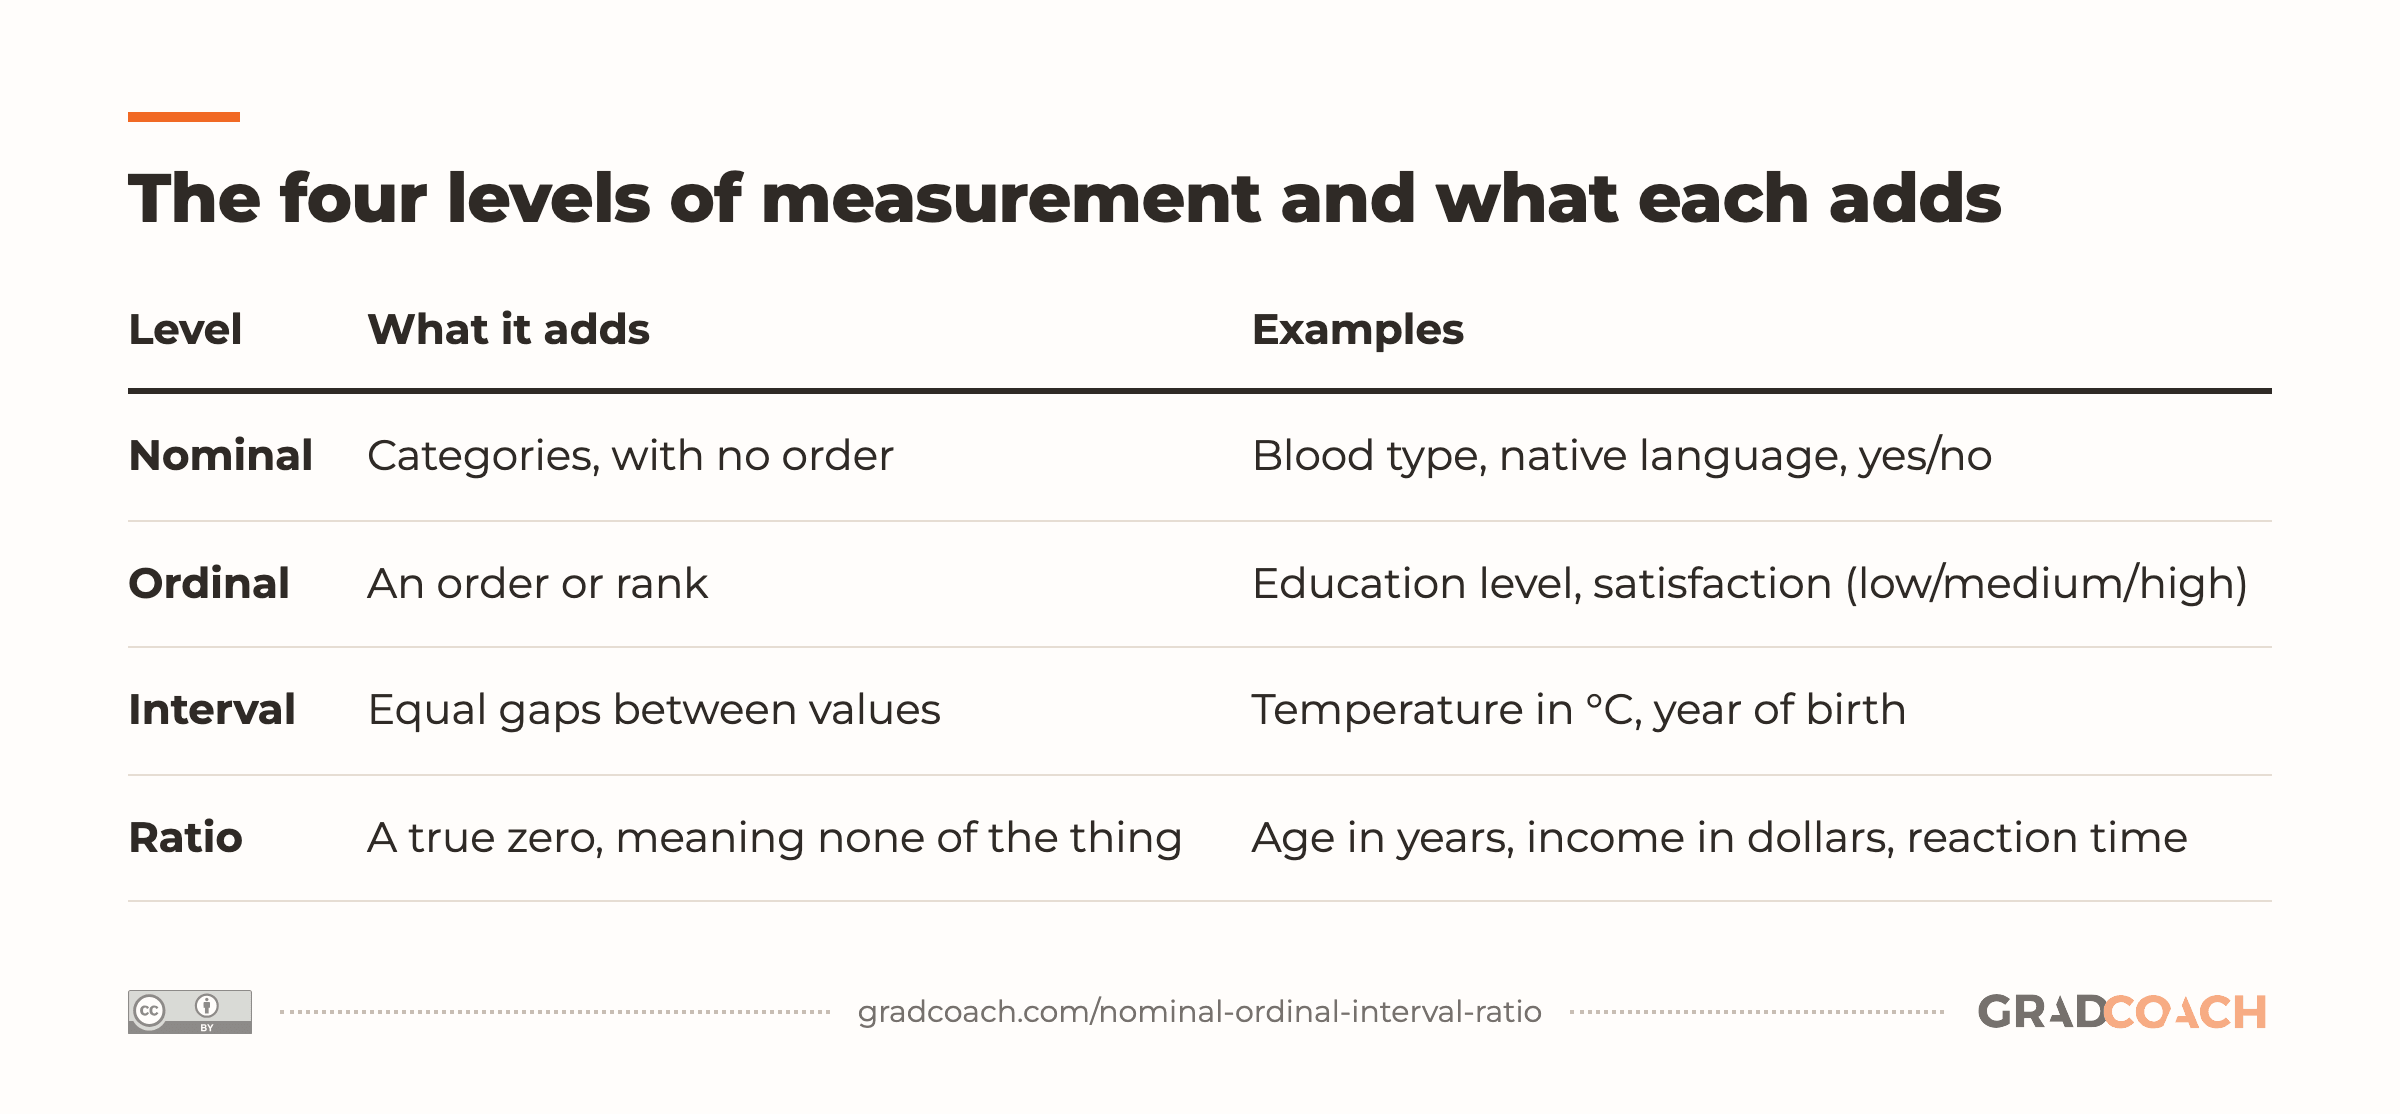
The levels are cumulative. Each one keeps everything the level below it has and adds one more property:
| Level | What it adds | Examples |
|---|---|---|
| Nominal | Categories, with no order | Blood type, native language, yes/no |
| Ordinal | An order or rank | Education level, satisfaction (low/medium/high) |
| Interval | Equal gaps between values | Temperature in °C, year of birth |
| Ratio | A true zero, meaning none of the thing | Age in years, income in dollars, reaction time |
Nominal and ordinal data are categorical: the values are groups, even when you code them as numbers (1 for yes, 0 for no). Interval and ratio data are numerical: the numbers themselves carry the information. That split is the first one to get right, because it decides whether you’re counting things or measuring them.
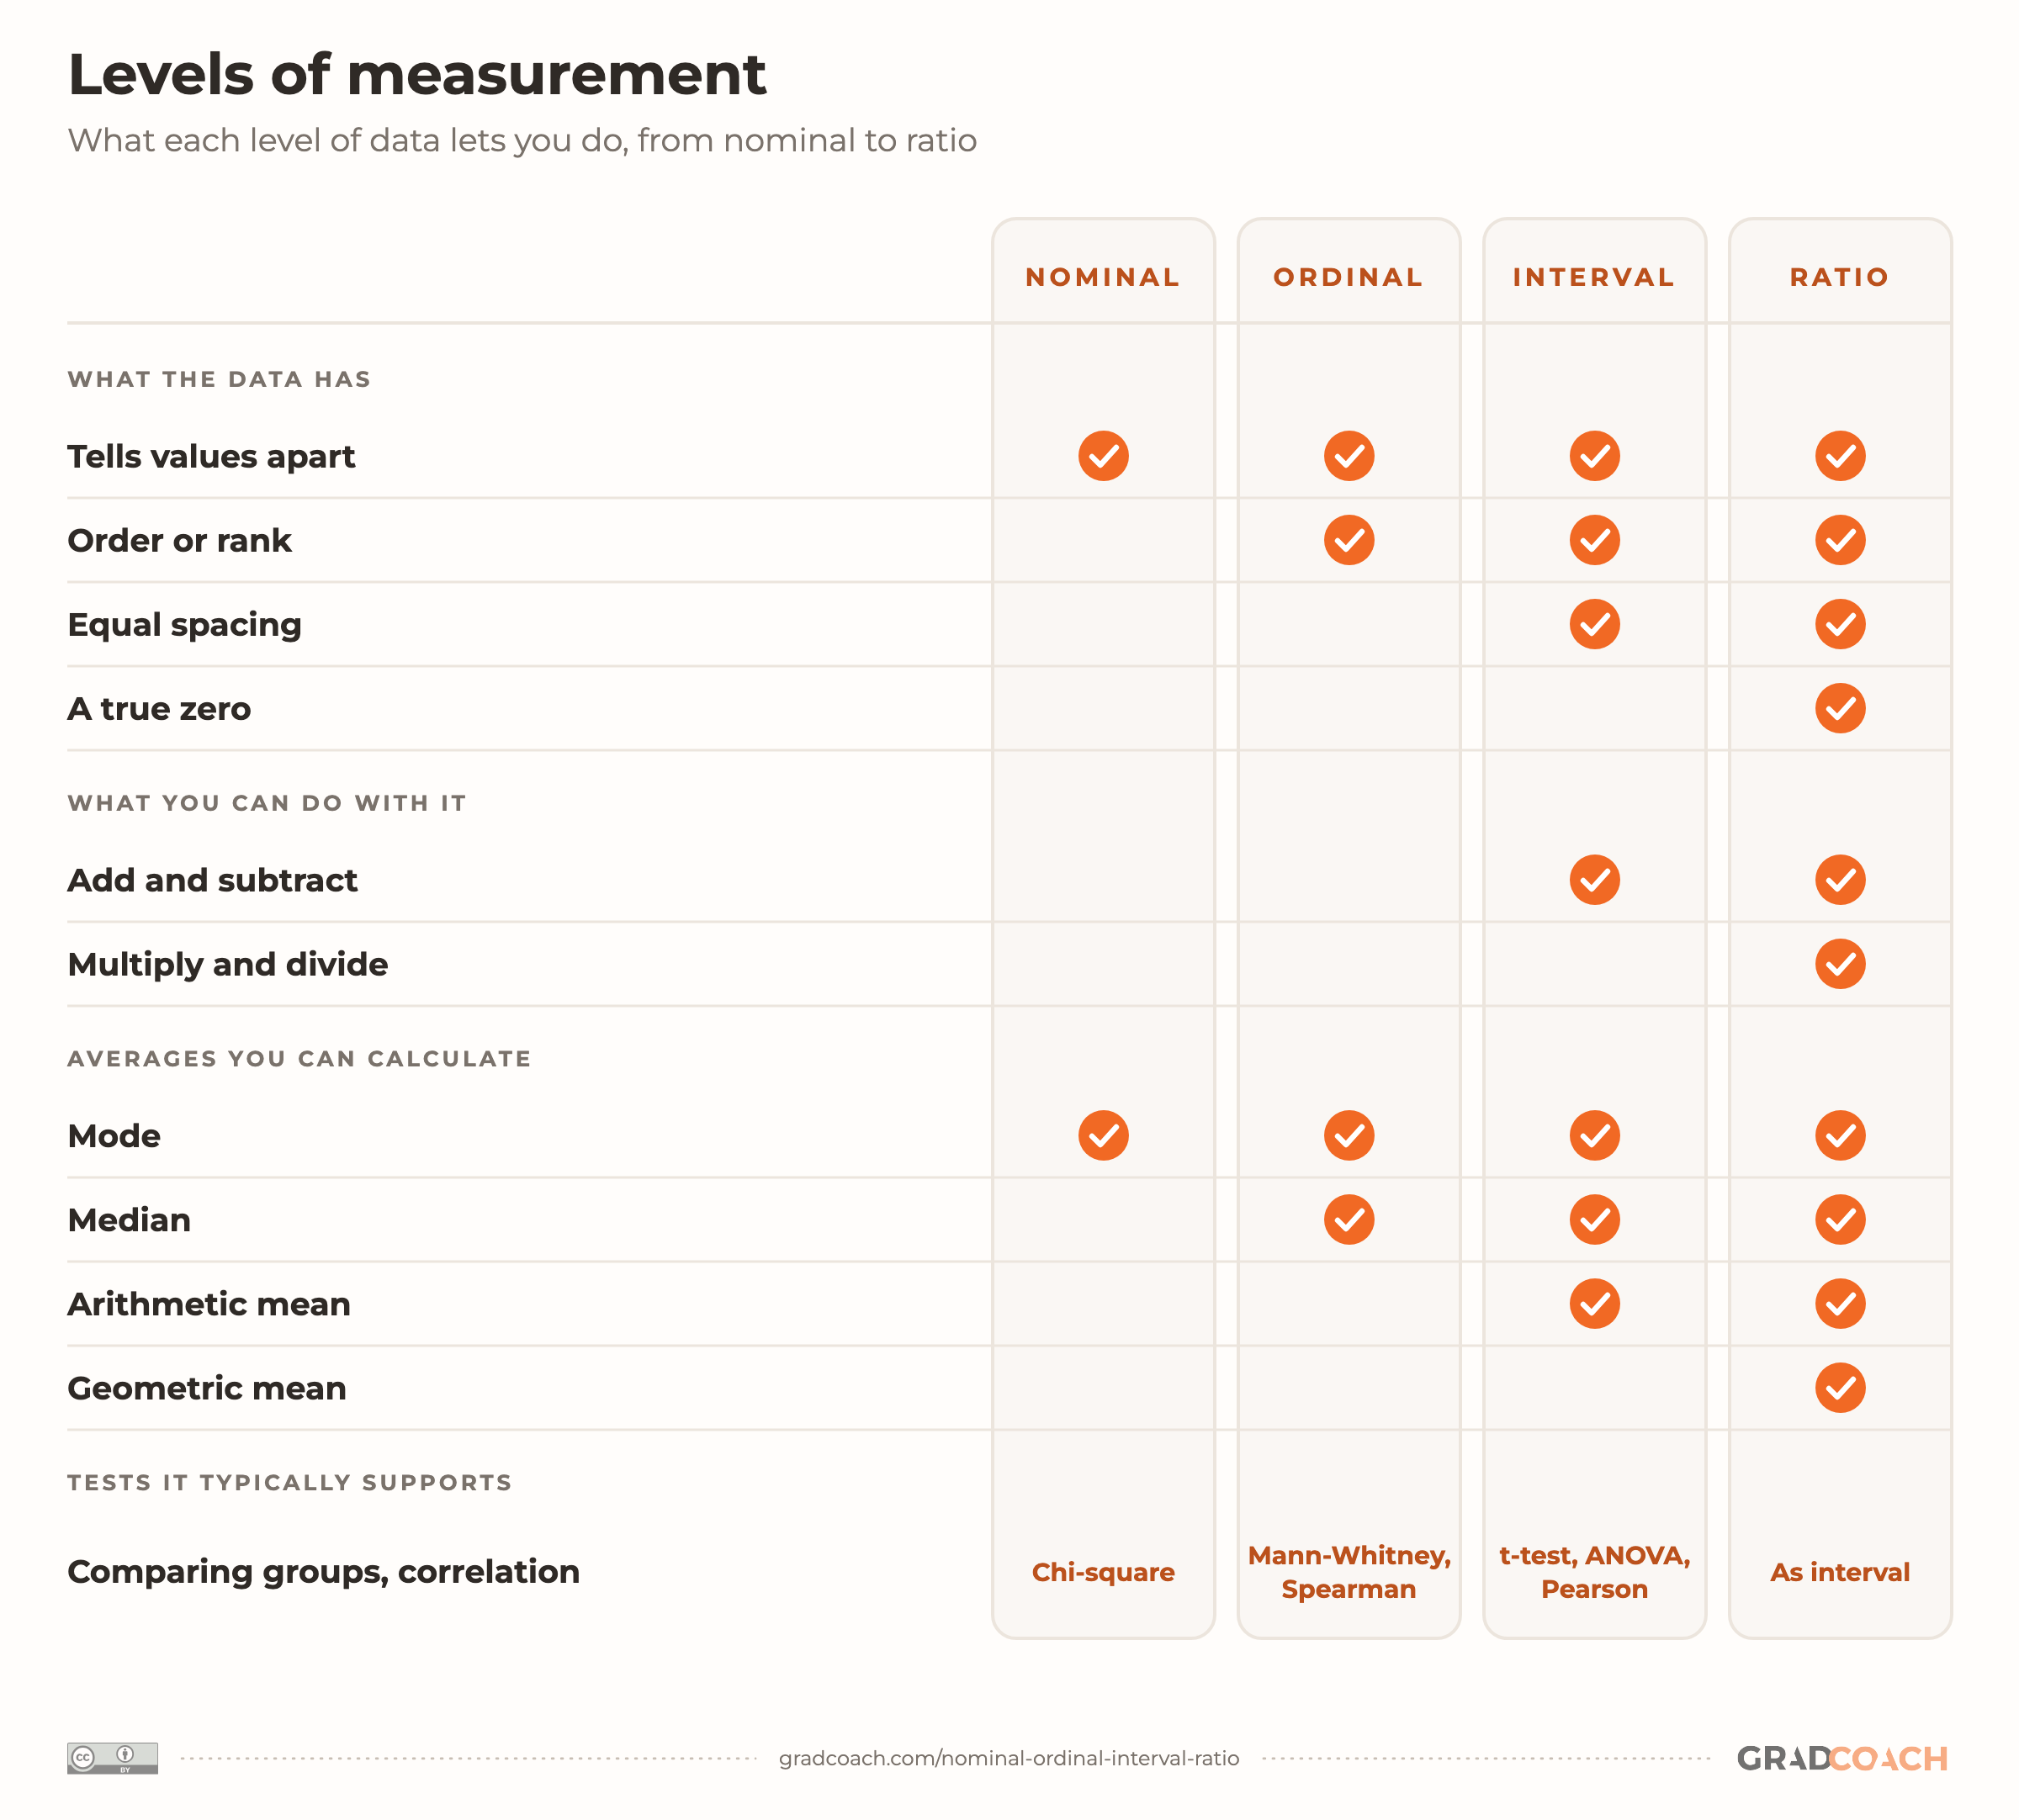
The more properties your data has, the more you can do with it. In this figure, read each column from top to bottom: every tick is something that level has, lets you do or lets you calculate.

Most mistakes are a tick the data hasn’t earned, usually a mean of something that’s really ordinal. Let’s take each level in turn.
What is nominal data?
Nominal data puts things into categories that have no natural order. No category is higher, better or bigger than another. They’re just different. Examples include:
- Blood type, eye color, native language
- Brand of phone, preferred political candidate
- Any yes/no answer, such as “Have you completed a health care proxy form?”
A yes/no variable is the simplest case: two categories, no order. The UCLA statistical consulting group describes a binary variable as categorical with “no intrinsic ordering”. Coding “yes” as 1 and “no” as 0 doesn’t change that, because the numbers are only labels.
With nominal data, you can count. You can report how many cases fall in each category, find the most common one (the mode, one of the descriptive statistics you’ll report) and test whether two categorical variables are related, usually with a chi-square test. You can’t take a mean, because there’s nothing to add up.
Here’s that reasoning in a real nursing doctorate, which tested whether a nurse-led intervention raised the share of hospital patients who completed a health care proxy form, then compared completion across patient groups:
Notice two things. The author names the level and ties the test to it in one short sentence, which is all your committee needs. And age, normally ratio data, has been collapsed into two groups, which turns it into an ordered category: you can always move down a level, but never back up.
Do the same for each variable in your own methodology chapter: name its level, then the test that level allows.
What is ordinal data?
Ordinal data is categorical too, but the categories have a meaningful order. What it lacks is equal spacing: you know one option ranks above another, but not by how much. Examples include:
- Education level (high school, bachelor’s, master’s, doctorate)
- Income bands (under $30,000, $30,000 to $60,000, over $60,000)
- A single Likert item (strongly disagree, disagree, neutral, agree, strongly agree)
- Rankings, such as finishing positions in a race
The gap between “agree” and “strongly agree” isn’t necessarily the same as the gap between “neutral” and “agree”. So with ordinal data, you can use the median and percentiles, and rank-based tests such as the Mann-Whitney U test (two groups), the Kruskal-Wallis test (three or more) and Spearman’s correlation.
Take this public health PhD from New Zealand, which compared Māori with favorable and adverse health outcomes using the Mann-Whitney U test. It gives three reasons for that choice, and the first is the one to watch, because one of its “ordinal” variables is a 1-to-10 index:
NZDep, a deprivation index, runs from 1 to 10, so it looks numerical. Later in the thesis, Munn calls it “a ten-category ordinal scale rather than an interval metric”.
A number on a scale doesn’t make a variable interval. So when one in your study looks numerical, check whether the gaps between its values really are equal. If you can’t say they are, treat it as ordinal.
What is interval data?
Interval data is numerical, ordered and evenly spaced, so the difference between two values means the same thing anywhere on the scale. What it doesn’t have is a true zero: its zero point is arbitrary, chosen as a reference. Examples include:
- Temperature in Celsius or Fahrenheit
- Calendar years, such as year of birth
- Standardized test scores, such as the SAT or GRE (usually treated as interval)
Zero degrees Celsius is just the freezing point of water. That’s why 20°C isn’t twice as hot as 10°C, even though 20 is twice 10. Calendar years work the same way: the calendar’s starting point is a convention, so it makes no sense to say one date is “twice” another.
With interval data, you can add and subtract, so the mean and standard deviation make sense, and so do the inferential tests built on them: t-tests, ANOVA and Pearson’s correlation, provided their other assumptions hold. What you can’t do is multiply or divide meaningfully, so a claim like “a test score of 80 shows twice the knowledge of 40” is off the table.
If t-tests, ANOVA and correlation are new to you, our inferential statistics tutorial walks through each one, with examples:
What is ratio data?
Ratio data has everything interval data has, plus a true zero, where zero means none of the thing you’re measuring. That’s what lets you multiply and divide: 20 minutes really is twice as long as 10 minutes. Examples include:
- Age in years, height, weight
- Income in dollars, number of children
- Reaction time, duration, distance
- Temperature in kelvin
Kelvin is a useful contrast with Celsius. Zero kelvin is absolute zero, the lowest temperature possible, so 200 K really is twice 100 K. Nothing can actually reach absolute zero, and it doesn’t matter: the test is what zero means.
Ratio data supports every statistic the other levels do, plus a few that need a true zero, such as the geometric mean and the coefficient of variation. In practice, interval and ratio data take the same tests, and SPSS puts them under one setting. The difference shows up in how you describe results: if you’re reporting that one group scored “twice as high”, or a percentage change, check the variable is ratio first.
How to tell which level your data is
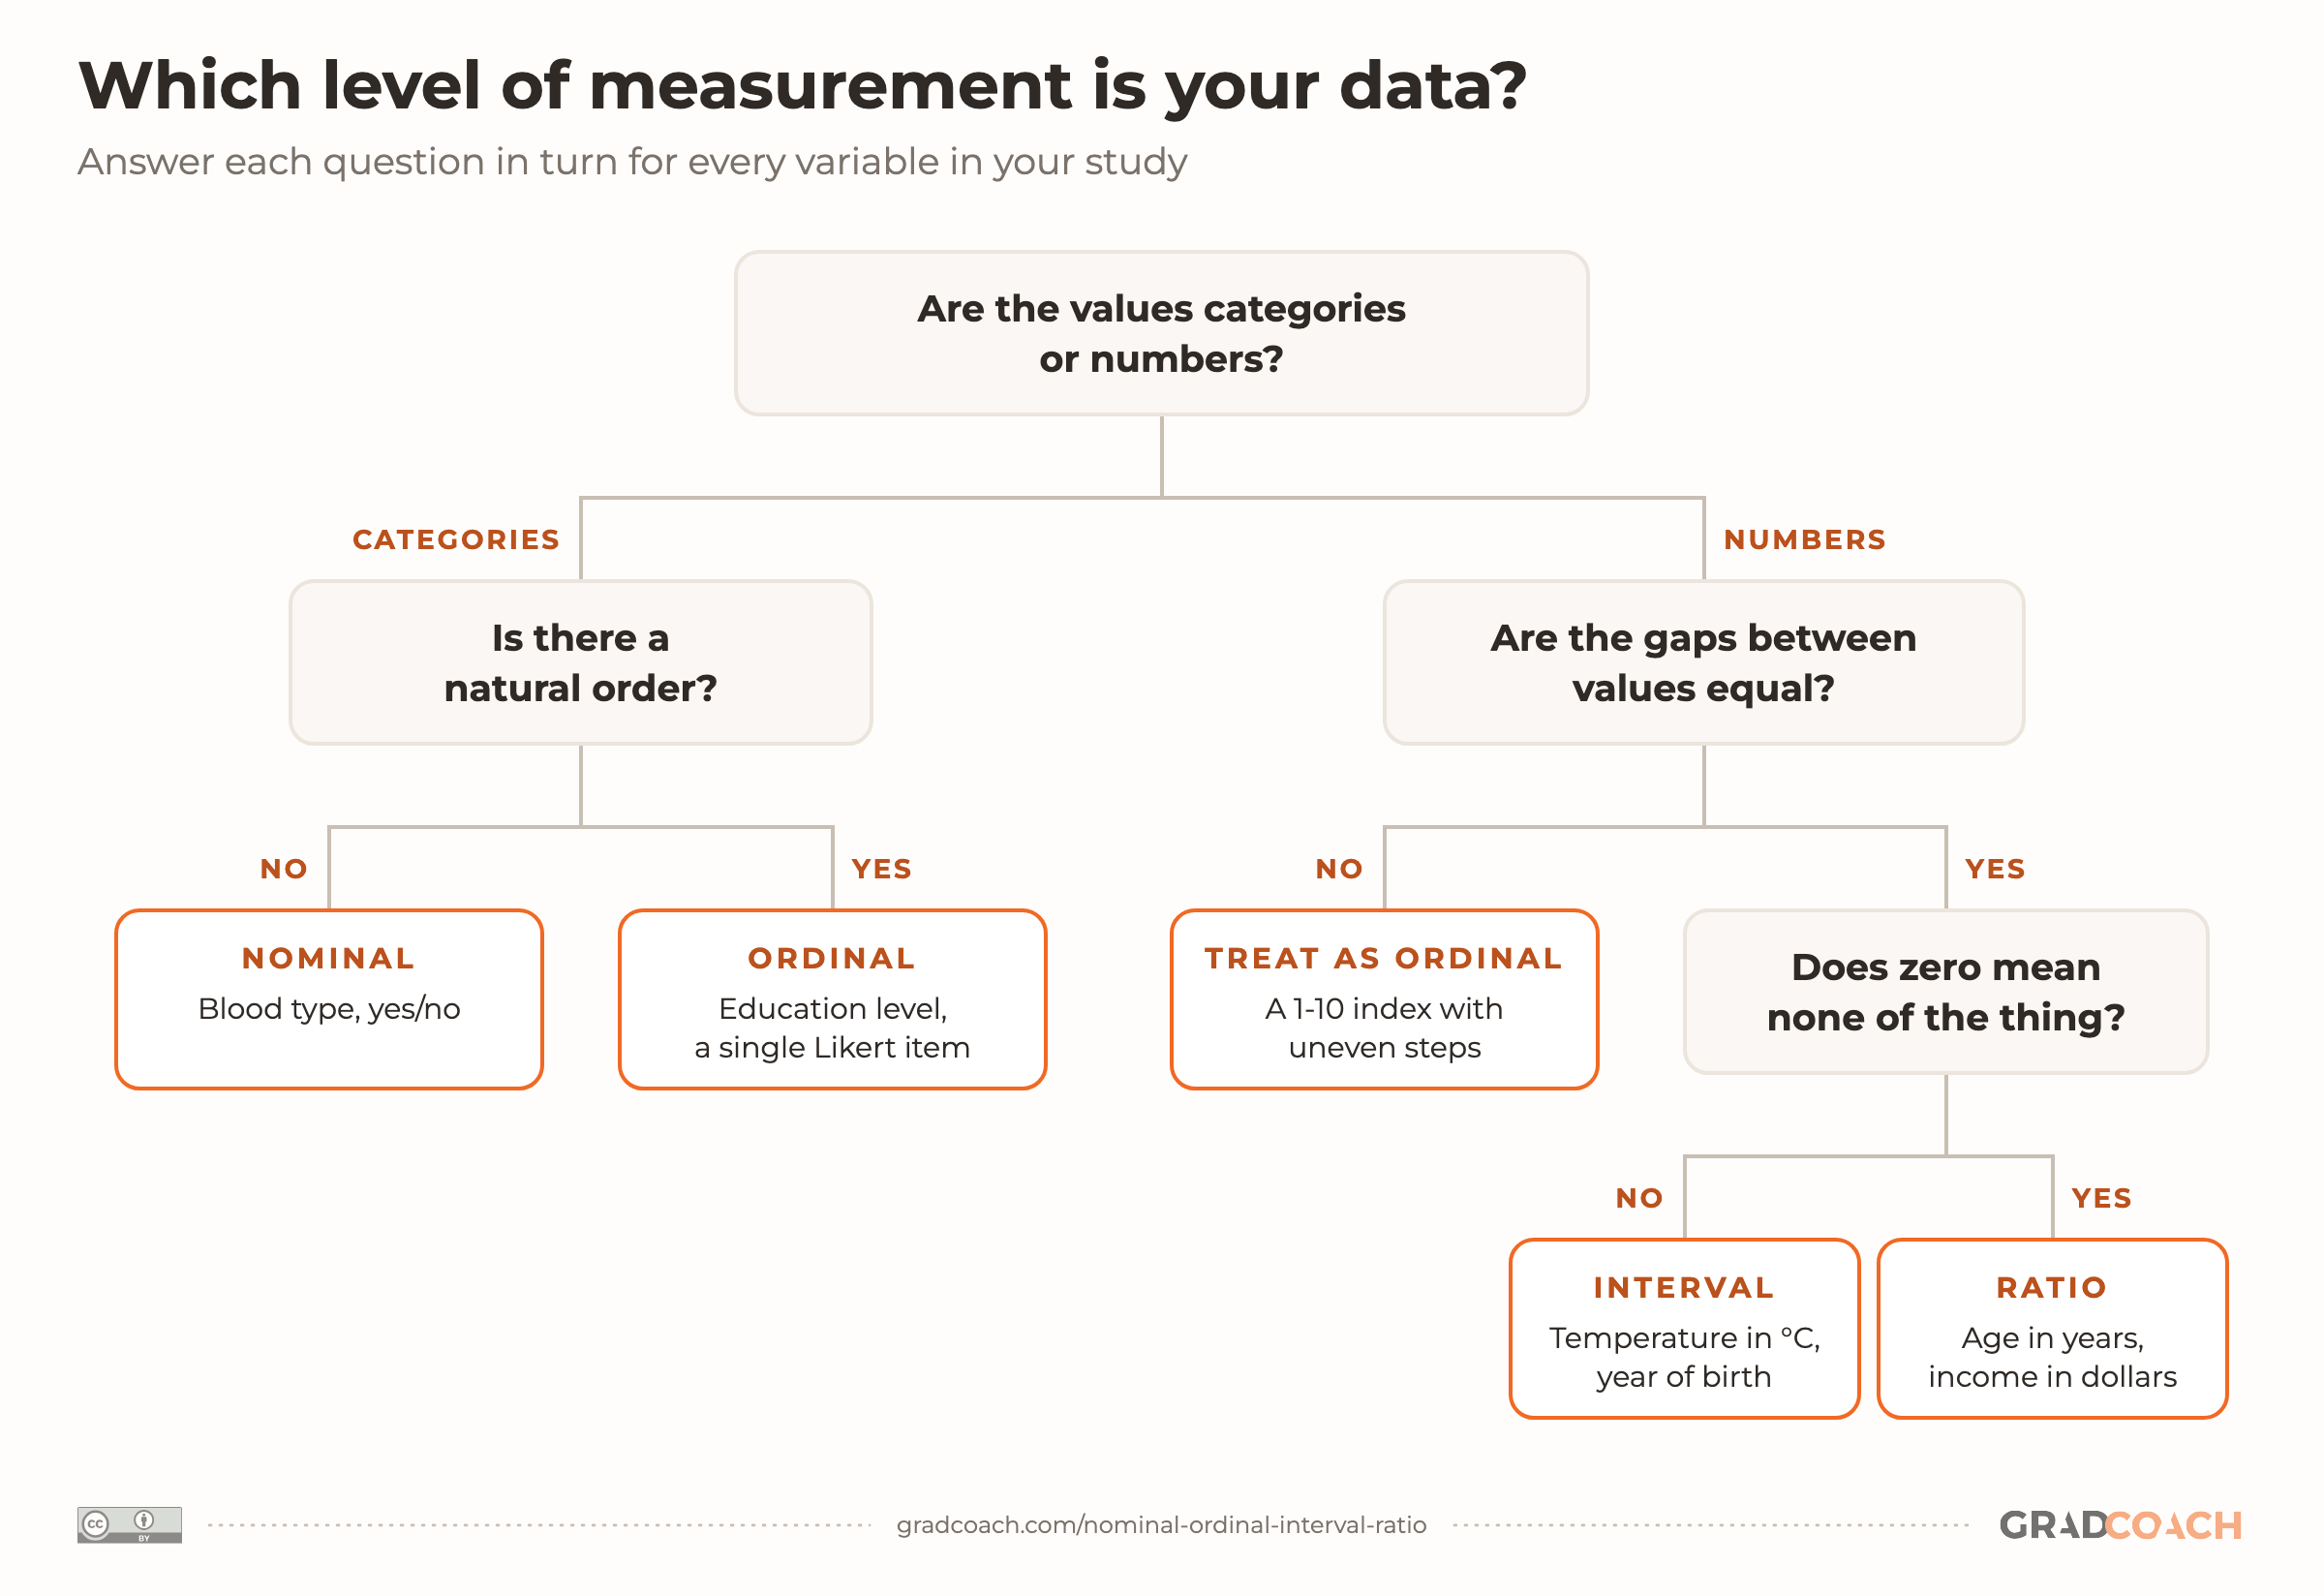
Most variables fall into place after two or three questions. Start at the top of this flowchart with one variable from your study and follow your answers down:

The question people skip is the one about equal gaps. Numbers with unequal gaps belong on the ordinal branch, however much they look like a measurement. Run every variable in your study through the chart, and do it before you choose a single test.
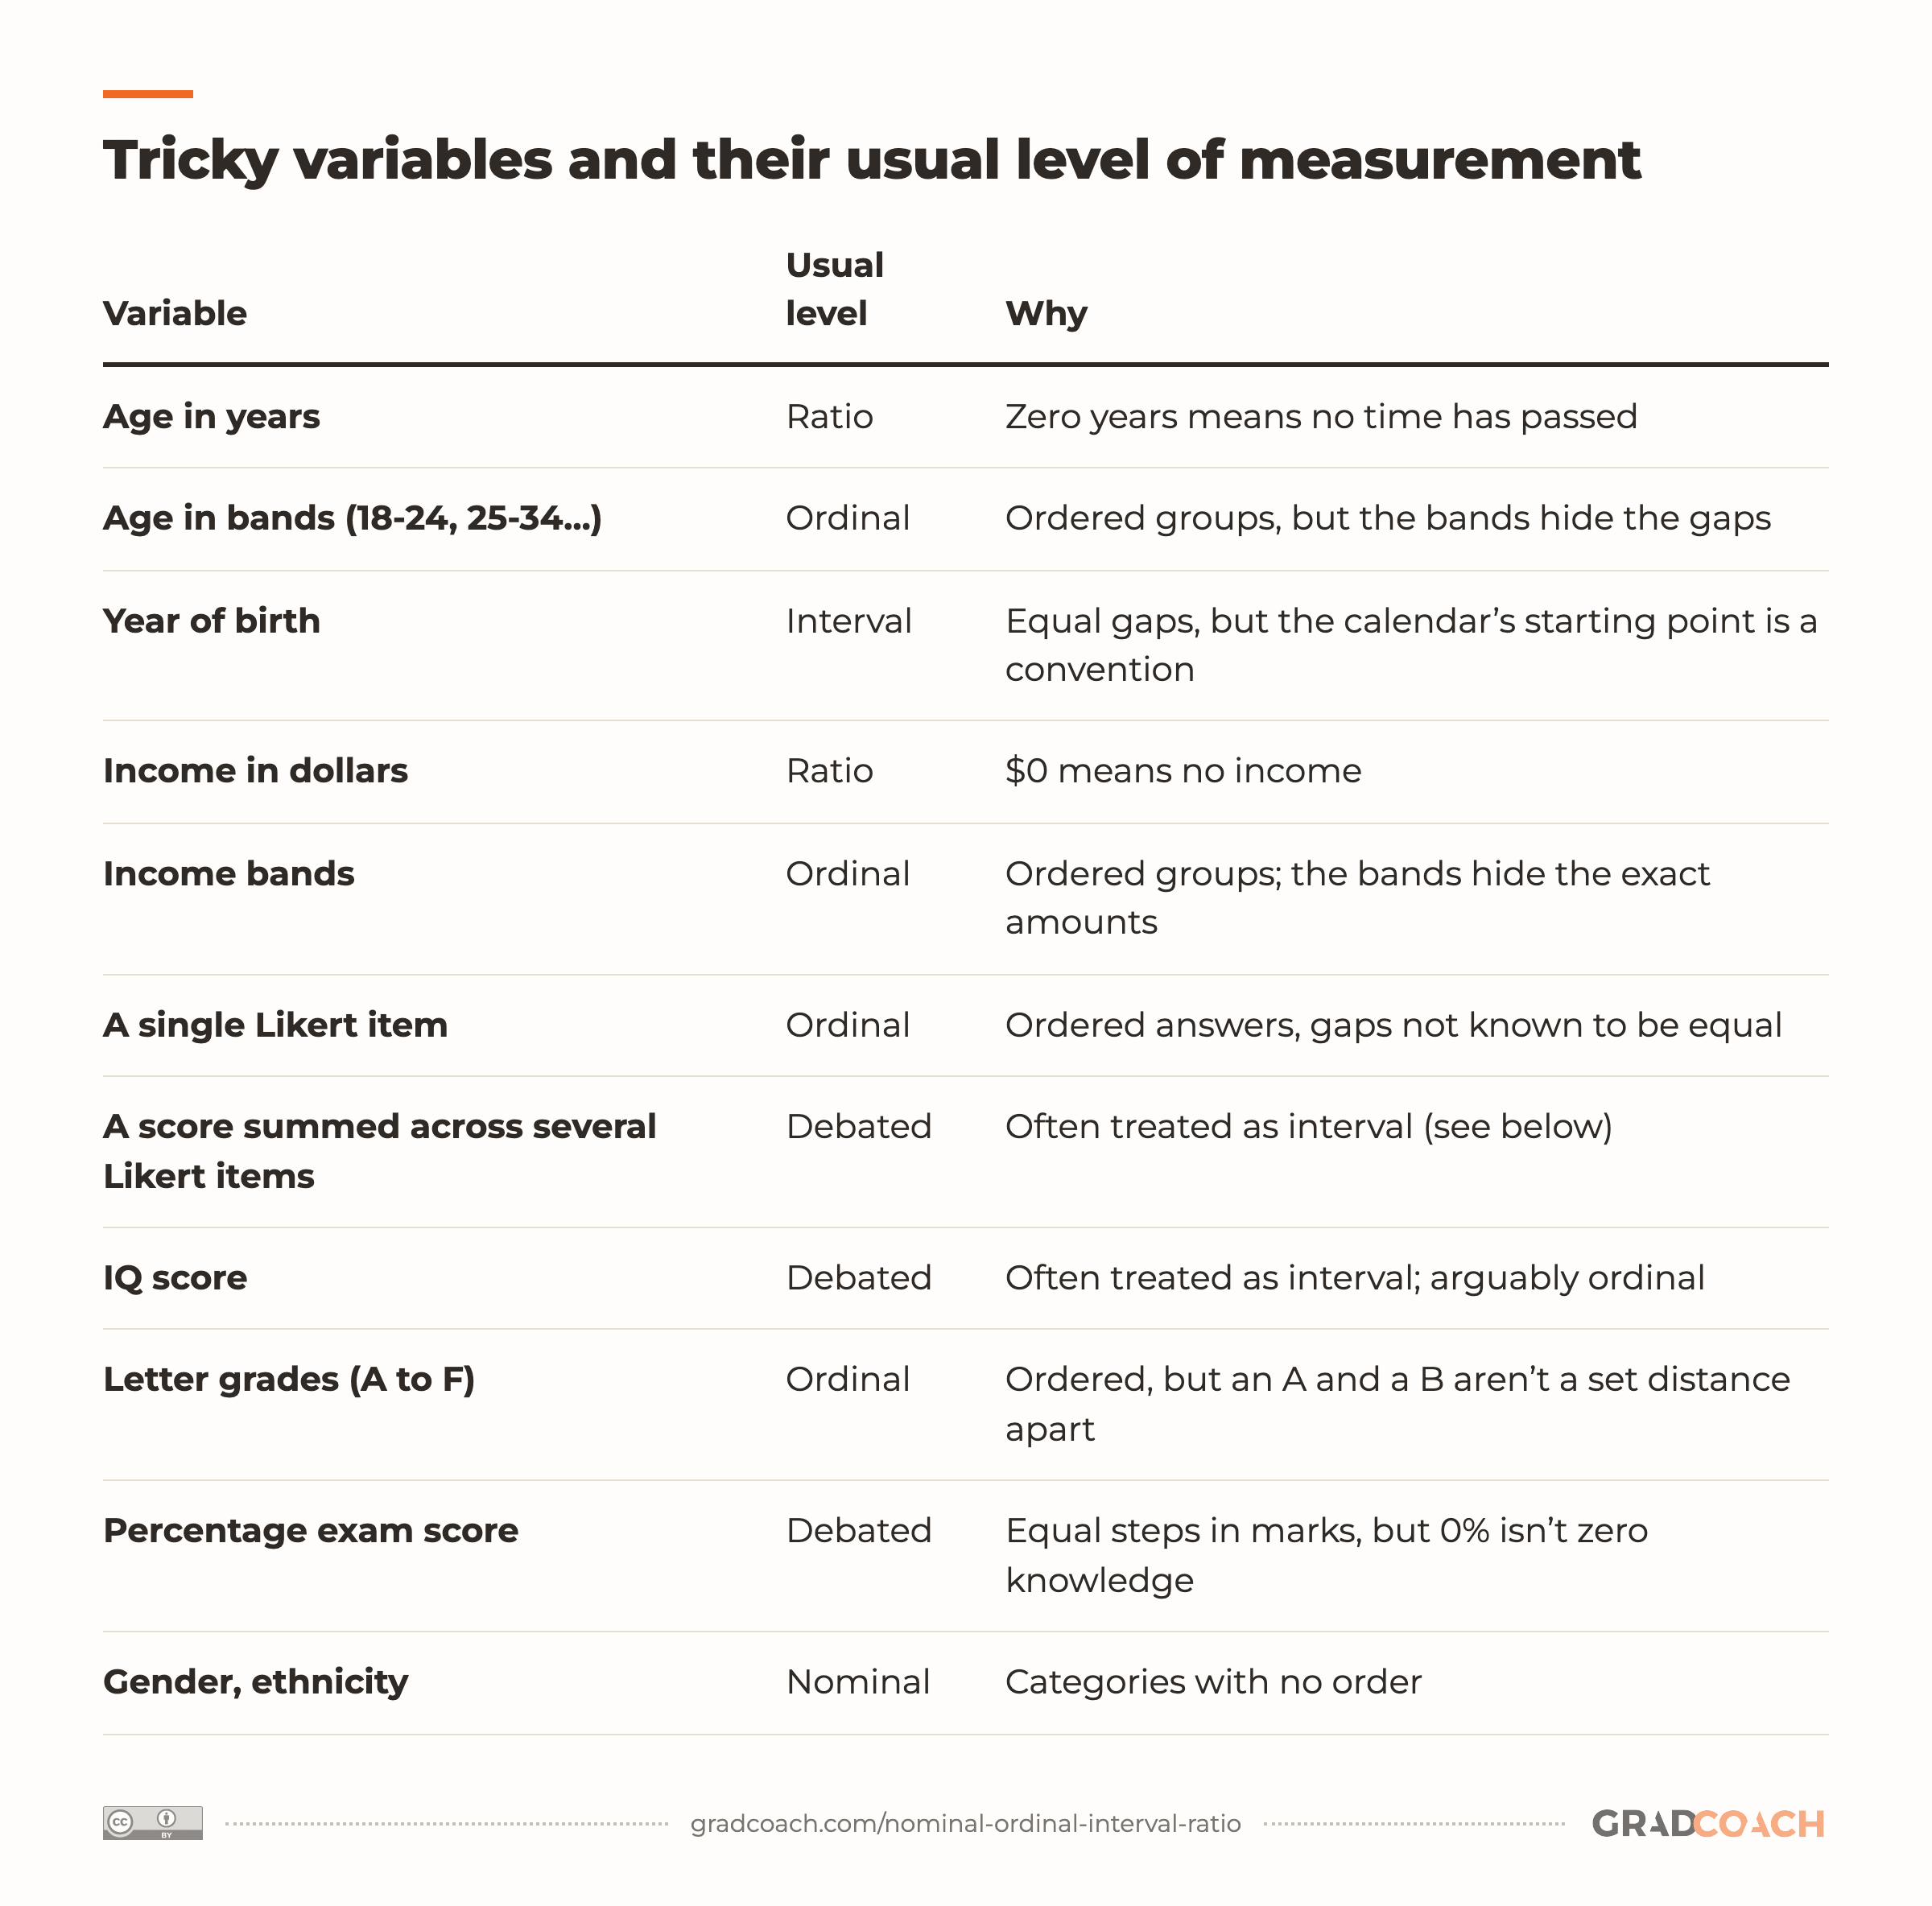
Some cases are hard to call, and in my experience they’re the ones committees query most:
| Variable | Usual level | Why |
|---|---|---|
| Age in years | Ratio | Zero years means no time has passed |
| Age in bands (18-24, 25-34…) | Ordinal | Ordered groups, but the bands hide the gaps |
| Year of birth | Interval | Equal gaps, but the calendar’s starting point is a convention |
| Income in dollars | Ratio | $0 means no income |
| Income bands | Ordinal | Ordered groups; the bands hide the exact amounts |
| A single Likert item | Ordinal | Ordered answers, gaps not known to be equal |
| A score summed across several Likert items | Debated | Often treated as interval (see below) |
| IQ score | Debated | Often treated as interval; arguably ordinal |
| Letter grades (A to F) | Ordinal | Ordered, but an A and a B aren’t a set distance apart |
| Percentage exam score | Debated | Equal steps in marks, but 0% isn’t zero knowledge |
| Gender, ethnicity | Nominal | Categories with no order |
The Likert rows need more than a line, and there’s one software trap worth knowing before you set up your data file.
The Likert debate
A single Likert item is ordinal, and few people dispute that. The argument is about what happens when you add or average several items into a scale score.
One side, put most clearly by Susan Jamieson in a 2004 Medical Education article, argues that Likert scales are ordinal because “the intervals between values cannot be presumed equal”, so they should get ordinal methods.
The other side argues that a scale built from several items behaves well enough to treat as interval. Carifio and Perla write that “many studies have shown” that Likert scales, “as opposed to single Likert response format items”, produce interval data, and a 2010 paper points to studies going back to the 1930s showing that parametric tests are robust enough to use with this kind of data.
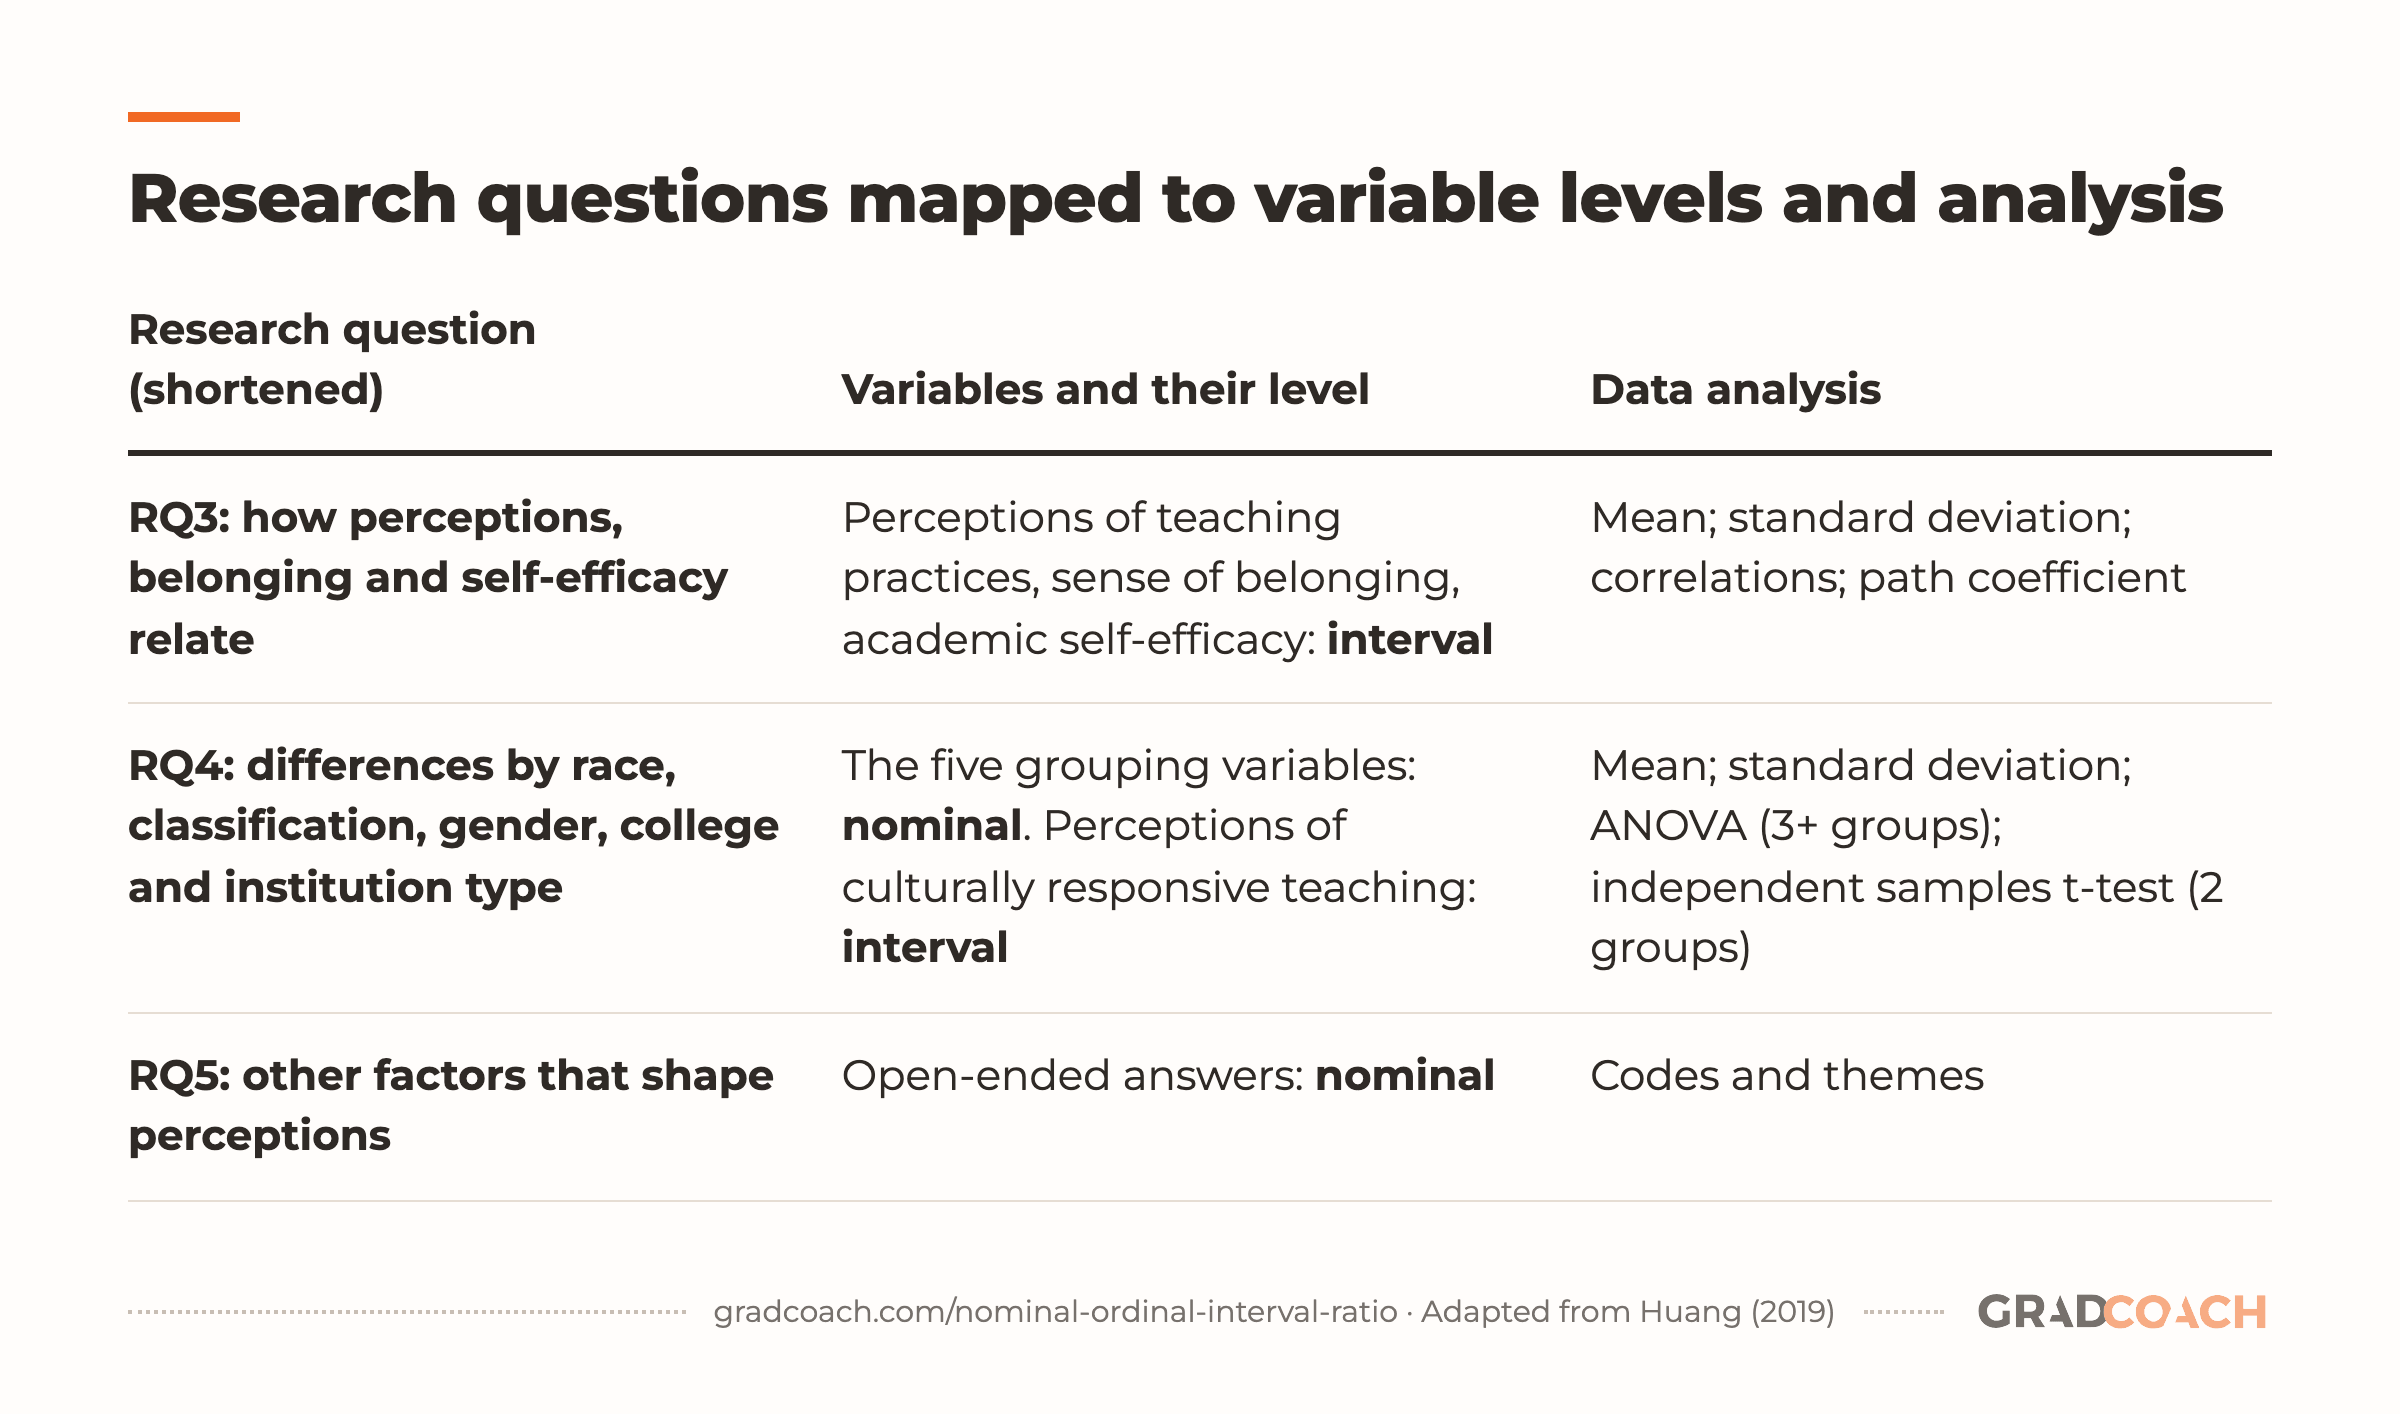
Even Jamieson, who argues for ordinal methods, reports the observation that “it has become common practice to assume that Likert-type categories constitute interval-level measurement”, and plenty of dissertations do. A Purdue education PhD shows a habit worth copying: it built its scales from five-point Likert items, then set out each research question’s variables, levels and analysis in one table. Here are three of its rows:
| Research question (shortened) | Variables and their level | Data analysis |
|---|---|---|
| RQ3: how perceptions, belonging and self-efficacy relate | Perceptions of teaching practices, sense of belonging, academic self-efficacy: interval | Mean; standard deviation; correlations; path coefficient |
| RQ4: differences by race, classification, gender, college and institution type | The five grouping variables: nominal. Perceptions of culturally responsive teaching: interval | Mean; standard deviation; ANOVA (3+ groups); independent samples t-test (2 groups) |
| RQ5: other factors that shape perceptions | Open-ended answers: nominal | Codes and themes |
Source: Yujie Huang, Undergraduate Students’ Perceptions of Culturally Responsive Teaching and Their Sense of Belonging and Academic Self-Efficacy in Higher Education, PhD, Purdue University, 2019, Table 1 (p. 80). Columns combined and wording shortened; the original lists independent and dependent variables separately, with RQ5’s left blank.
A table like this gives your committee one place to check every variable’s level against its test. Notice, though, that the scale scores are labeled interval without a word of justification. That’s common, and usually accepted, but it leaves the choice undefended.
My advice: if your scale has several items and a published validation, treat the score as interval and say so in one cited sentence. If it’s a single item, stay with ordinal methods. IQ is similar: most studies treat IQ scores as interval, and if yours uses them, acknowledge the debate in a sentence.
Why SPSS only offers three options
When you set up variables in SPSS, the Measure column gives you three choices:
- Scale, for both interval and ratio data (there’s no separate setting for each)
- Ordinal
- Nominal
SPSS also guesses the level for you, and the guess can be wrong in either direction: a nominal code typed in as 1, 2 and 3 can land on Scale, and an imported Likert item can land on Nominal. That column is the first thing to check in a new data file.
Why does it matter?
Your level of measurement narrows down which tests you can use. For the two jobs most dissertations need, comparing groups and testing a relationship, the rule of thumb looks like this:
- Nominal outcome: a chi-square test
- Ordinal outcome: the Mann-Whitney U test (or Kruskal-Wallis for three or more groups), and Spearman’s correlation for relationships
- Interval or ratio outcome: a t-test (or ANOVA for three or more groups), and Pearson’s correlation for relationships, provided their assumptions hold
That mapping comes from the UCLA table I’d recommend bookmarking, What statistical analysis should I use?, which describes itself as “general guidelines” rather than “hard and fast rules”. That caveat is worth taking seriously. In a well-known critique of Stevens’ system, two statisticians argued that the level “depends upon the questions we intend to ask of the data”, not on the data alone. So use the levels as a guide to your choices, and justify any choice that bends them.
The level also matters before you collect a single response. If your study needs a t-test, design your questions to produce numerical data. Ask for age in years rather than in bands, and income as an amount rather than a range, where you can. You can always group ratio data later; you can’t ungroup it. Our guide to survey design covers how to plan questions around the analysis you need, and once your data’s in, our post on choosing a statistical test takes it from there.
For the short version, this walkthrough covers how to pick the right test for your data:
Still have questions?
Is age nominal, ordinal, interval or ratio?
Age measured in years (or months, or days) is ratio data, because zero means no time has passed and someone aged 40 really is twice as old as someone aged 20. Age collected in bands, such as 18-24 and 25-34, is ordinal: the bands are ordered, but you lose the exact gaps between people. Collect age in years if your analysis might need a mean or a t-test.
Is a Likert scale ordinal or interval?
A single Likert item, such as one statement rated from “strongly disagree” to “strongly agree”, is ordinal. A score added up or averaged across several items is debated: many researchers treat it as interval and use t-tests or ANOVA, while others argue it should still get ordinal methods. If you treat a summed scale as interval, say so in your methodology and cite a source for the convention.
How do I know which level of measurement my data is?
Up to three questions, depending on your answers. Are the values categories or numbers? If categories, do they have a natural order (ordinal) or not (nominal)? If numbers, are the gaps between values equal? And if they are, does zero mean “none of the thing” (ratio) or is it arbitrary (interval)? Numbers whose gaps you can’t show are equal, such as a 1-to-10 deprivation index its own author calls ordinal, are safest treated as ordinal.
Is gender nominal or ordinal?
Gender is nominal. Its categories have no natural order, so none is “higher” than another, even if you code them as 1, 2 and 3 for your software. That means you can report counts and percentages and use tests such as chi-square, but a mean of the codes would be meaningless.
Is IQ interval or ordinal data?
IQ scores are usually treated as interval data: they’re scored on a standardized scale (mean 100, standard deviation 15), each point is treated as an equal step, and zero doesn’t mean “no intelligence”. Some researchers argue it’s better seen as ordinal, because there’s no guarantee that the gap from 100 to 120 reflects the same difference in ability as the gap from 120 to 140. If your study leans on IQ, acknowledge the debate in a sentence.
What’s the difference between interval and ratio data?
Both are numerical with equal gaps between values. The difference is zero: on a ratio scale, zero means none of the thing being measured (zero kilograms, zero dollars), so you can say one value is twice another. On an interval scale, such as temperature in Celsius, zero is an arbitrary point, so 20°C isn’t twice as hot as 10°C.
Can I treat ordinal data as interval?
Sometimes, and it’s common with scale scores built from several Likert items. It’s harder to defend for a single item or a short ranking. If you do it, state the decision, give a reason (such as a multi-item scale with a reasonable spread of scores), and cite a source that supports the convention, so your committee can see it was a choice rather than an oversight.
Is categorical data the same as nominal data?
The two terms are often used interchangeably. UCLA’s statistical consulting group, for instance, describes “a categorical variable (sometimes called a nominal variable)”. Many textbooks, though, use “categorical” as the wider term, covering both nominal data (categories with no order, such as blood type) and ordinal data (ordered categories, such as education level). Either way, nominal data is always categorical.
Is ordinal data qualitative or quantitative?
Ordinal data is categorical, so many textbooks group it with nominal data as qualitative, even when the categories are coded as numbers. Others count anything you can rank as quantitative. What matters for your analysis is the level itself: treat ordinal data with the median, percentiles and rank-based tests such as Mann-Whitney U or Spearman’s correlation.
Can’t find your answer here? Ask a Grad Coach directly – the initial chat is free.
Speak with a friendly coach →


Cite-worthy sources
Cite this article
Jansen, D. (2020). Nominal, Ordinal, Interval & Ratio: A Plain-Language Explainer. Grad Coach. https://gradcoach.com/nominal-ordinal-interval-ratio/
- Baldassari, J. (2026). Improving health care proxy procurement rates for hospitalized adults: A nurse led intervention [Doctor of Nursing Practice project, University of Massachusetts Amherst].
- Carifio, J., & Perla, R. J. (2007). Ten common misunderstandings, misconceptions, persistent myths and urban legends about Likert scales and Likert response formats and their antidotes. Journal of Social Sciences, 3(3), 106-116.
- Huang, Y. (2019). Undergraduate students’ perceptions of culturally responsive teaching and their sense of belonging and academic self-efficacy in higher education [Doctoral dissertation, Purdue University].
- Jamieson, S. (2004). Likert scales: How to (ab)use them. Medical Education, 38(12), 1217-1218.
- Munn, S. (2026). Understanding survival and suffering: An individual-level joint-burden approach for measuring health loss among Māori and non-Māori [Doctoral dissertation, Te Herenga Waka, Victoria University of Wellington].
- Norman, G. (2010). Likert scales, levels of measurement and the “laws” of statistics. Advances in Health Sciences Education, 15(5), 625-632.
- Stevens, S. S. (1946). On the theory of scales of measurement. Science, 103(2684), 677-680.
- Velleman, P. F., & Wilkinson, L. (1993). Nominal, ordinal, interval, and ratio typologies are misleading. The American Statistician, 47(1), 65-72.