What Are Descriptive Statistics?
Explainer with real-world examples and sample calculations


The 30-second summary
Descriptive statistics summarize your data, showing its typical value, its spread and its shape at a glance, before you run any statistical test.
- Central tendency shows a typical value: the mean, median or mode. Use the median when your data are skewed or have outliers.
- Dispersion tells you how spread out the values are, using the range, interquartile range, variance or standard deviation.
- Frequencies and percentages describe categories, such as the share of your sample who are female or who agree with a statement.
- Shape (skewness) tells you whether the values lean to one side, which affects how you summarize them and which tests you can run.
- In a dissertation, report a center and a spread for each key variable, matched to its level of measurement.
Want a head start? Our free statistics cheat sheet puts the core descriptive and inferential statistics on one reference sheet, in plain English.
Navigate
Descriptive statistics look like the easy part of a quantitative dissertation, so they’re often rushed. That shortcut costs you later: a mean reported for skewed data, or a summary that hides a problem in your dataset, misleads your committee before you’ve run a single test.
Having guided 10,000+ students through their dissertations, we know the descriptives are where many results chapters first slip, and where they’re easiest to fix. In this post, I’ll explain what descriptive statistics are and which ones to use, work through every common measure on one small dataset, and show you how to report them, with two real dissertations as models.
What are descriptive statistics?
A descriptive statistic is a single number that stands in for many: one figure that captures what a typical value looks like, how spread out the values are or what shape they take. Together, they let you understand your sample without reading every raw response, whether that’s 15 survey answers or 15,000.
Some are as simple as a count. The number of men and women in your sample, or the percentage of respondents in each age group, are descriptive statistics. So is the humble average, which statisticians call the mean. If you asked 200 people to rate a product from 1 to 10, the average rating would summarize all 200 answers in a single number.
What descriptive statistics don’t do is reach beyond your data. They describe the people or things you actually measured, and nothing more. That limit is what separates them from the other branch of quantitative data analysis.
Inferential statistics use your sample to draw conclusions about a wider population. Descriptive statistics tell you that the 200 people in your survey rated the product 6.4 on average; inferential statistics tell you how confident you can be that customers in general feel the same way, or whether two groups really differ.
In a dissertation, you need the descriptives either way, and they come first in your results chapter. The inferential statistics guide covers the tests themselves.
Why do descriptive statistics matter?
Descriptive statistics are simple mathematically, but they do three jobs that the rest of your analysis depends on:
- They let you understand your sample before you test anything: who responded, what a typical answer was, and how much the answers varied.
- They help you spot problems in your data, such as missing responses, suspicious outliers or impossible values (a rating of 11 on a 1-to-10 scale is a data entry error, not a finding). Spotting an outlier isn’t the same as being free to delete it, though: deciding what to do with one is a judgment call of its own.
- They show you the shape of your data, which decides which inferential tests you can use, since many tests assume roughly normal data.
It’s tempting to treat the descriptives as a warm-up and race to the more complicated inferential tests. I’d urge you not to. A t-test run on badly skewed data from a small sample, or on a dataset with an entry error nobody caught, gives you a result your committee can pick apart in one question.
“Can a dissertation use only descriptive statistics?”
It can, if your research questions are descriptive. A question like “what proportion of nurses on this unit have completed the training?” is answered completely by counts and percentages. If your questions ask whether groups differ or variables are related, you’ll need inferential statistics as well. Check what your program expects before you plan your analysis, because some departments want an inferential test in every quantitative dissertation.
Types of descriptive statistics
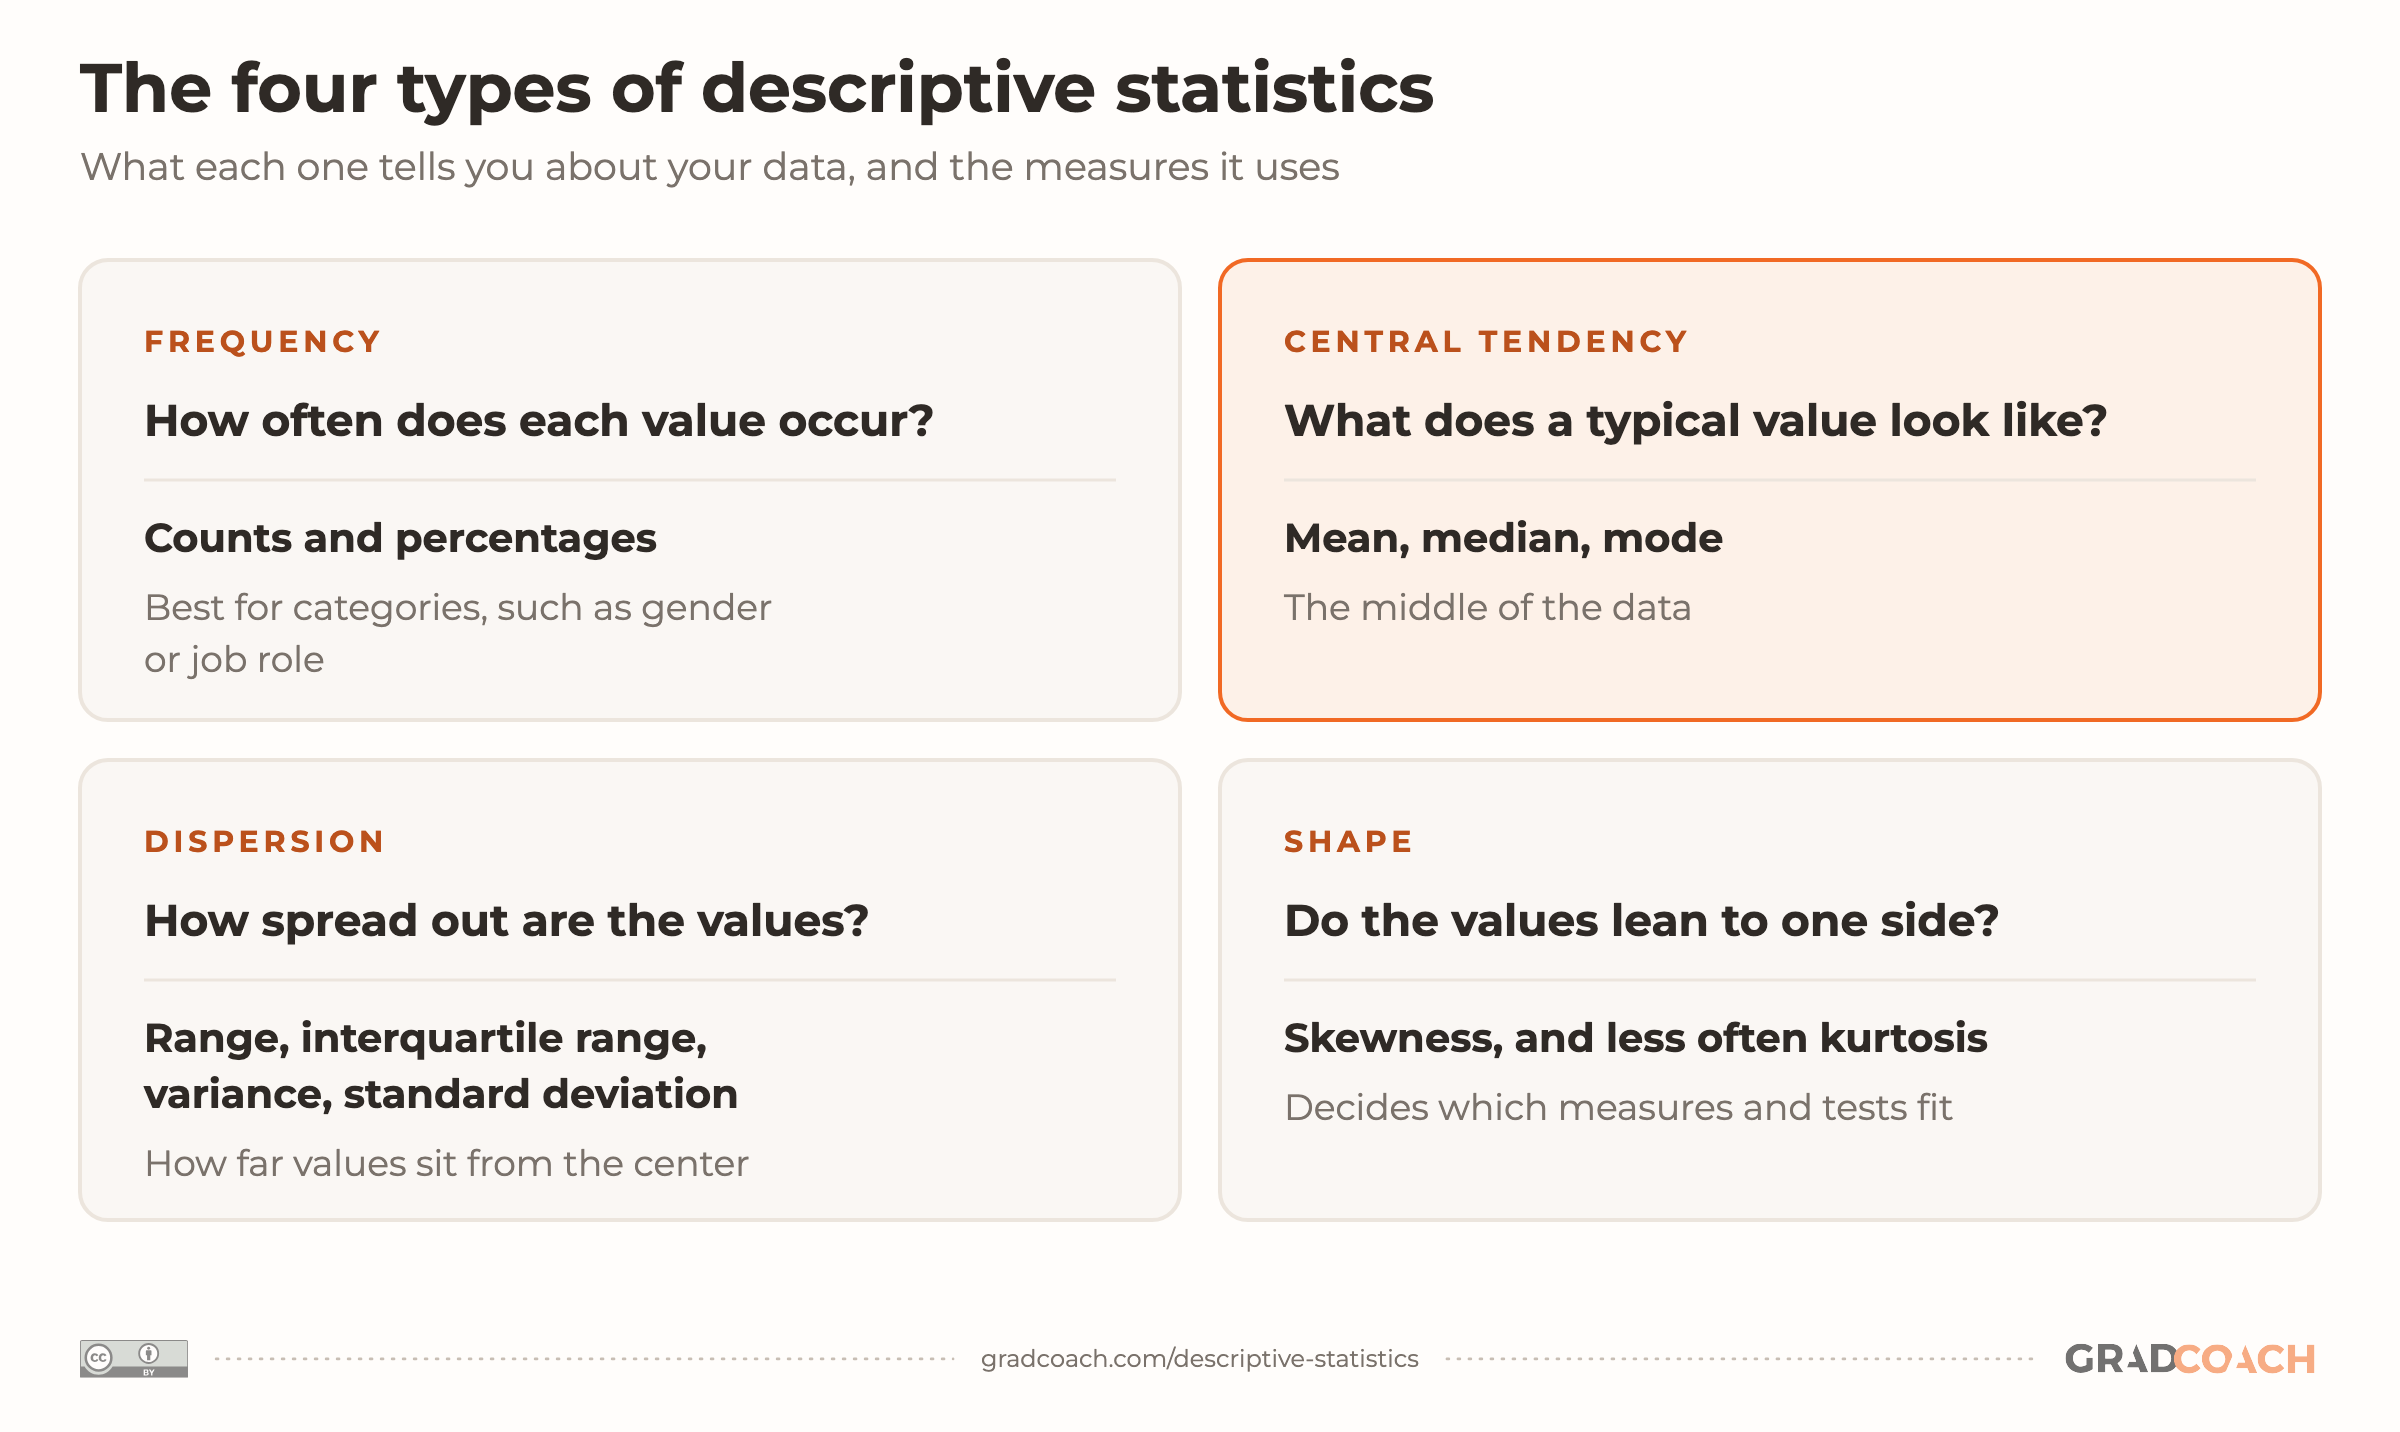
Descriptive statistics fall into a handful of families, each answering a different question about your data. One widely cited review groups them into three: measures of frequency, central tendency and dispersion. Some guides add a fourth, shape, which covers skewness.

Let’s look at each of these in a bit more detail.
Frequencies and percentages
A frequency is simply a count of how often each value occurs, and a percentage puts that count in proportion to the whole sample. They’re the natural way to describe categories, such as gender, language or job role, where an average would mean nothing.
The nursing doctorate below, a nurse-led intervention on a hospital unit, describes the patients in its first data collection period this way:
Notice the pattern: the count first, then the percentage in parentheses, with the total stated up front so every percentage has a base. The percentages are what let you compare groups of different sizes, which this project goes on to do with a second group of 312 records. Describe your own categorical variables the same way, and always give the n (the number of people or records behind each figure) alongside the percentage. A capital N is your whole sample; a lowercase n is a subgroup of it.
Measures of central tendency
True to the name, measures of central tendency describe the center of a dataset: what a typical data point looks like. The three most common are:
- The mean: The sum of all the values divided by how many there are. It’s what most people mean by “the average”.
- The median: The middle value once the values are sorted from lowest to highest. With an even number of values, it’s halfway between the two middle ones.
- The mode: The value that occurs most often. A dataset can have one mode, several, or none at all if no value repeats.
Each one captures “typical” in a different way, so they don’t always agree. Comparing the three is useful in itself, as the example below shows.
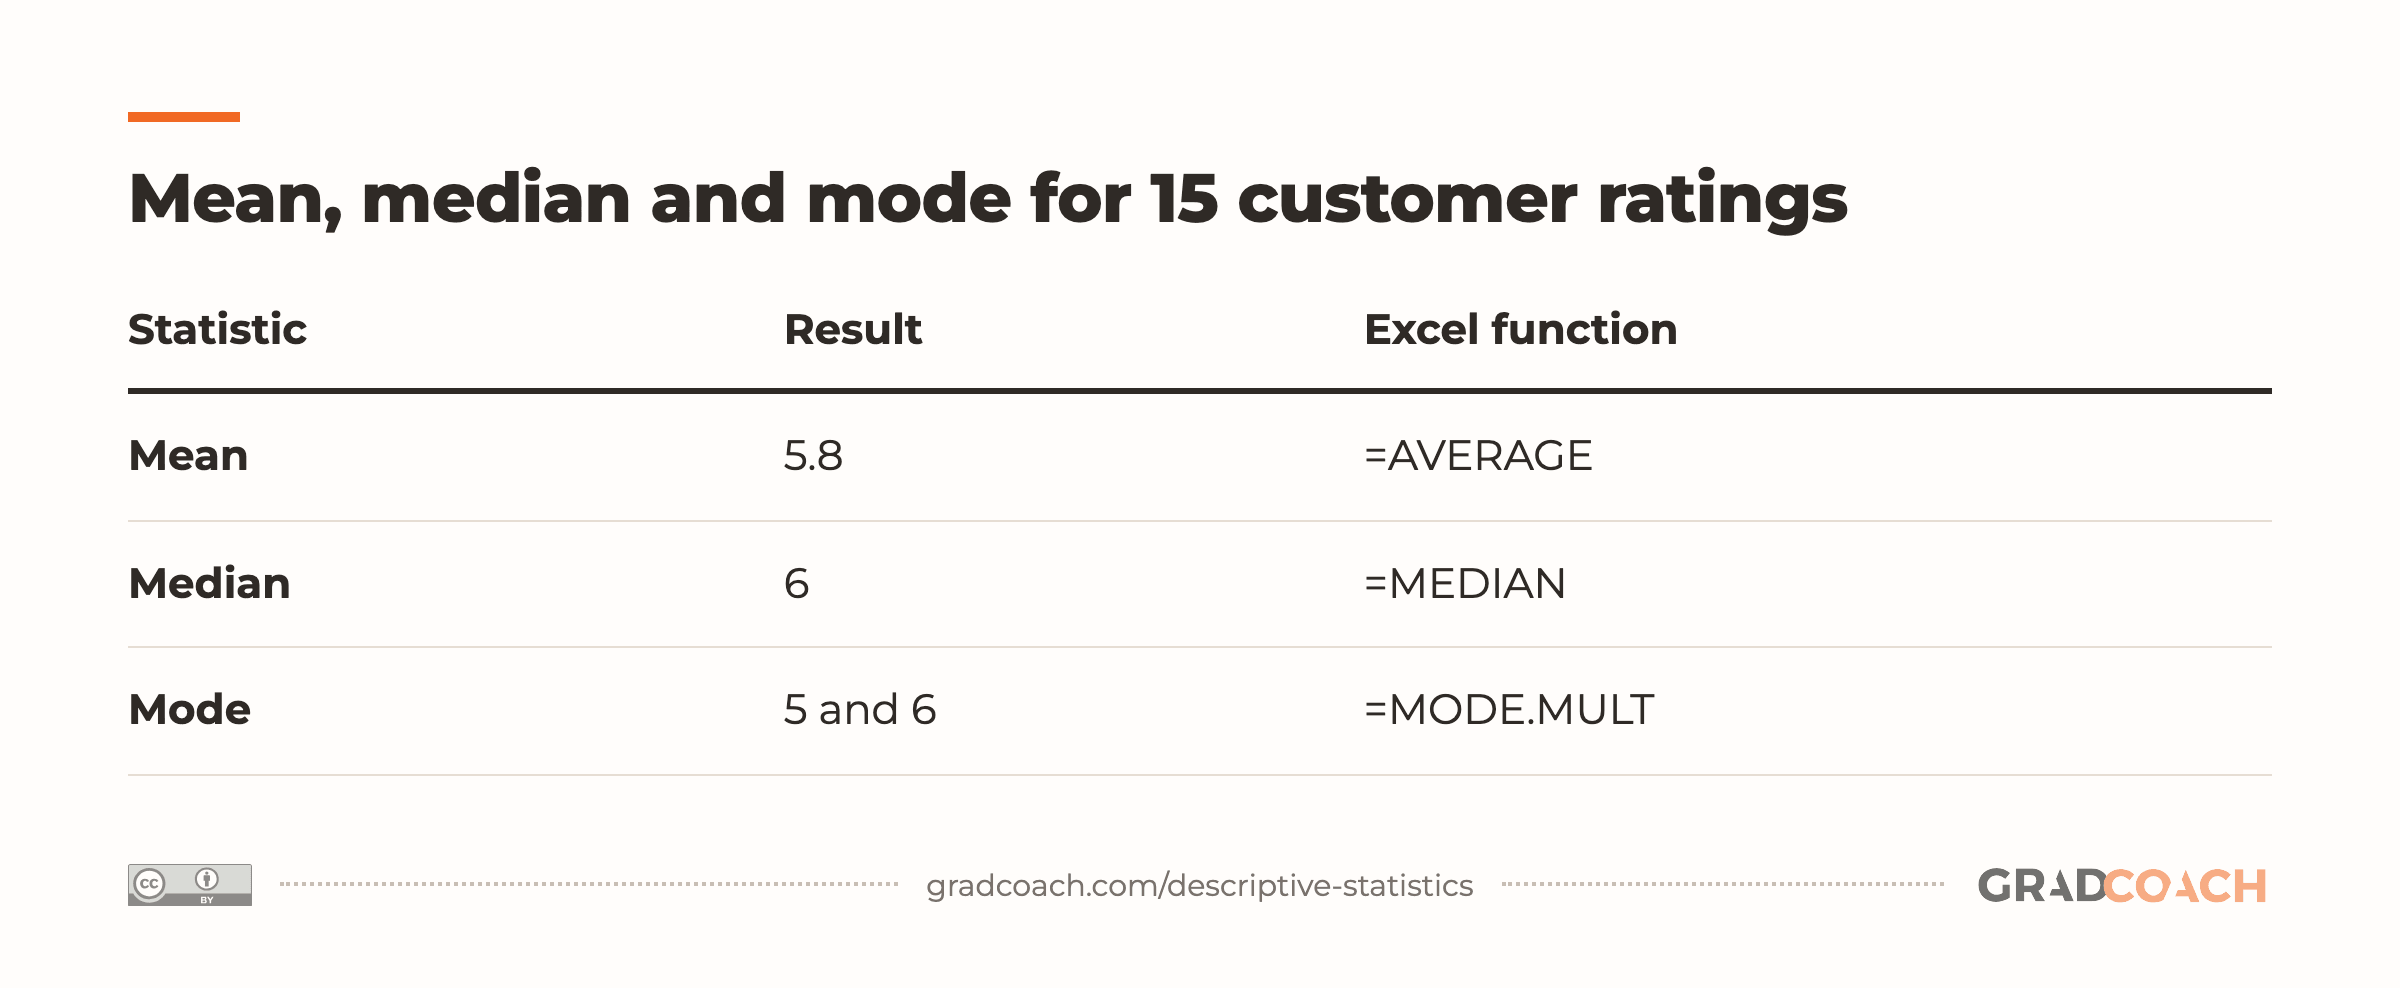
To make this concrete, here’s a small illustrative dataset: 15 customers rated a business’s service on a scale of 1 to 10 (a single rating, so in a write-up you’d lead with the median; more on that below). Their ratings, in the order they came in, were 3, 5, 6, 10, 5, 5, 9, 6, 8, 4, 6, 7, 4, 2 and 7. Here are its measures of central tendency, with the Excel function that calculates each:
| Statistic | Result | Excel function |
|---|---|---|
| Mean | 5.8 | =AVERAGE |
| Median | 6 | =MEDIAN |
| Mode | 5 and 6 | =MODE.MULT |
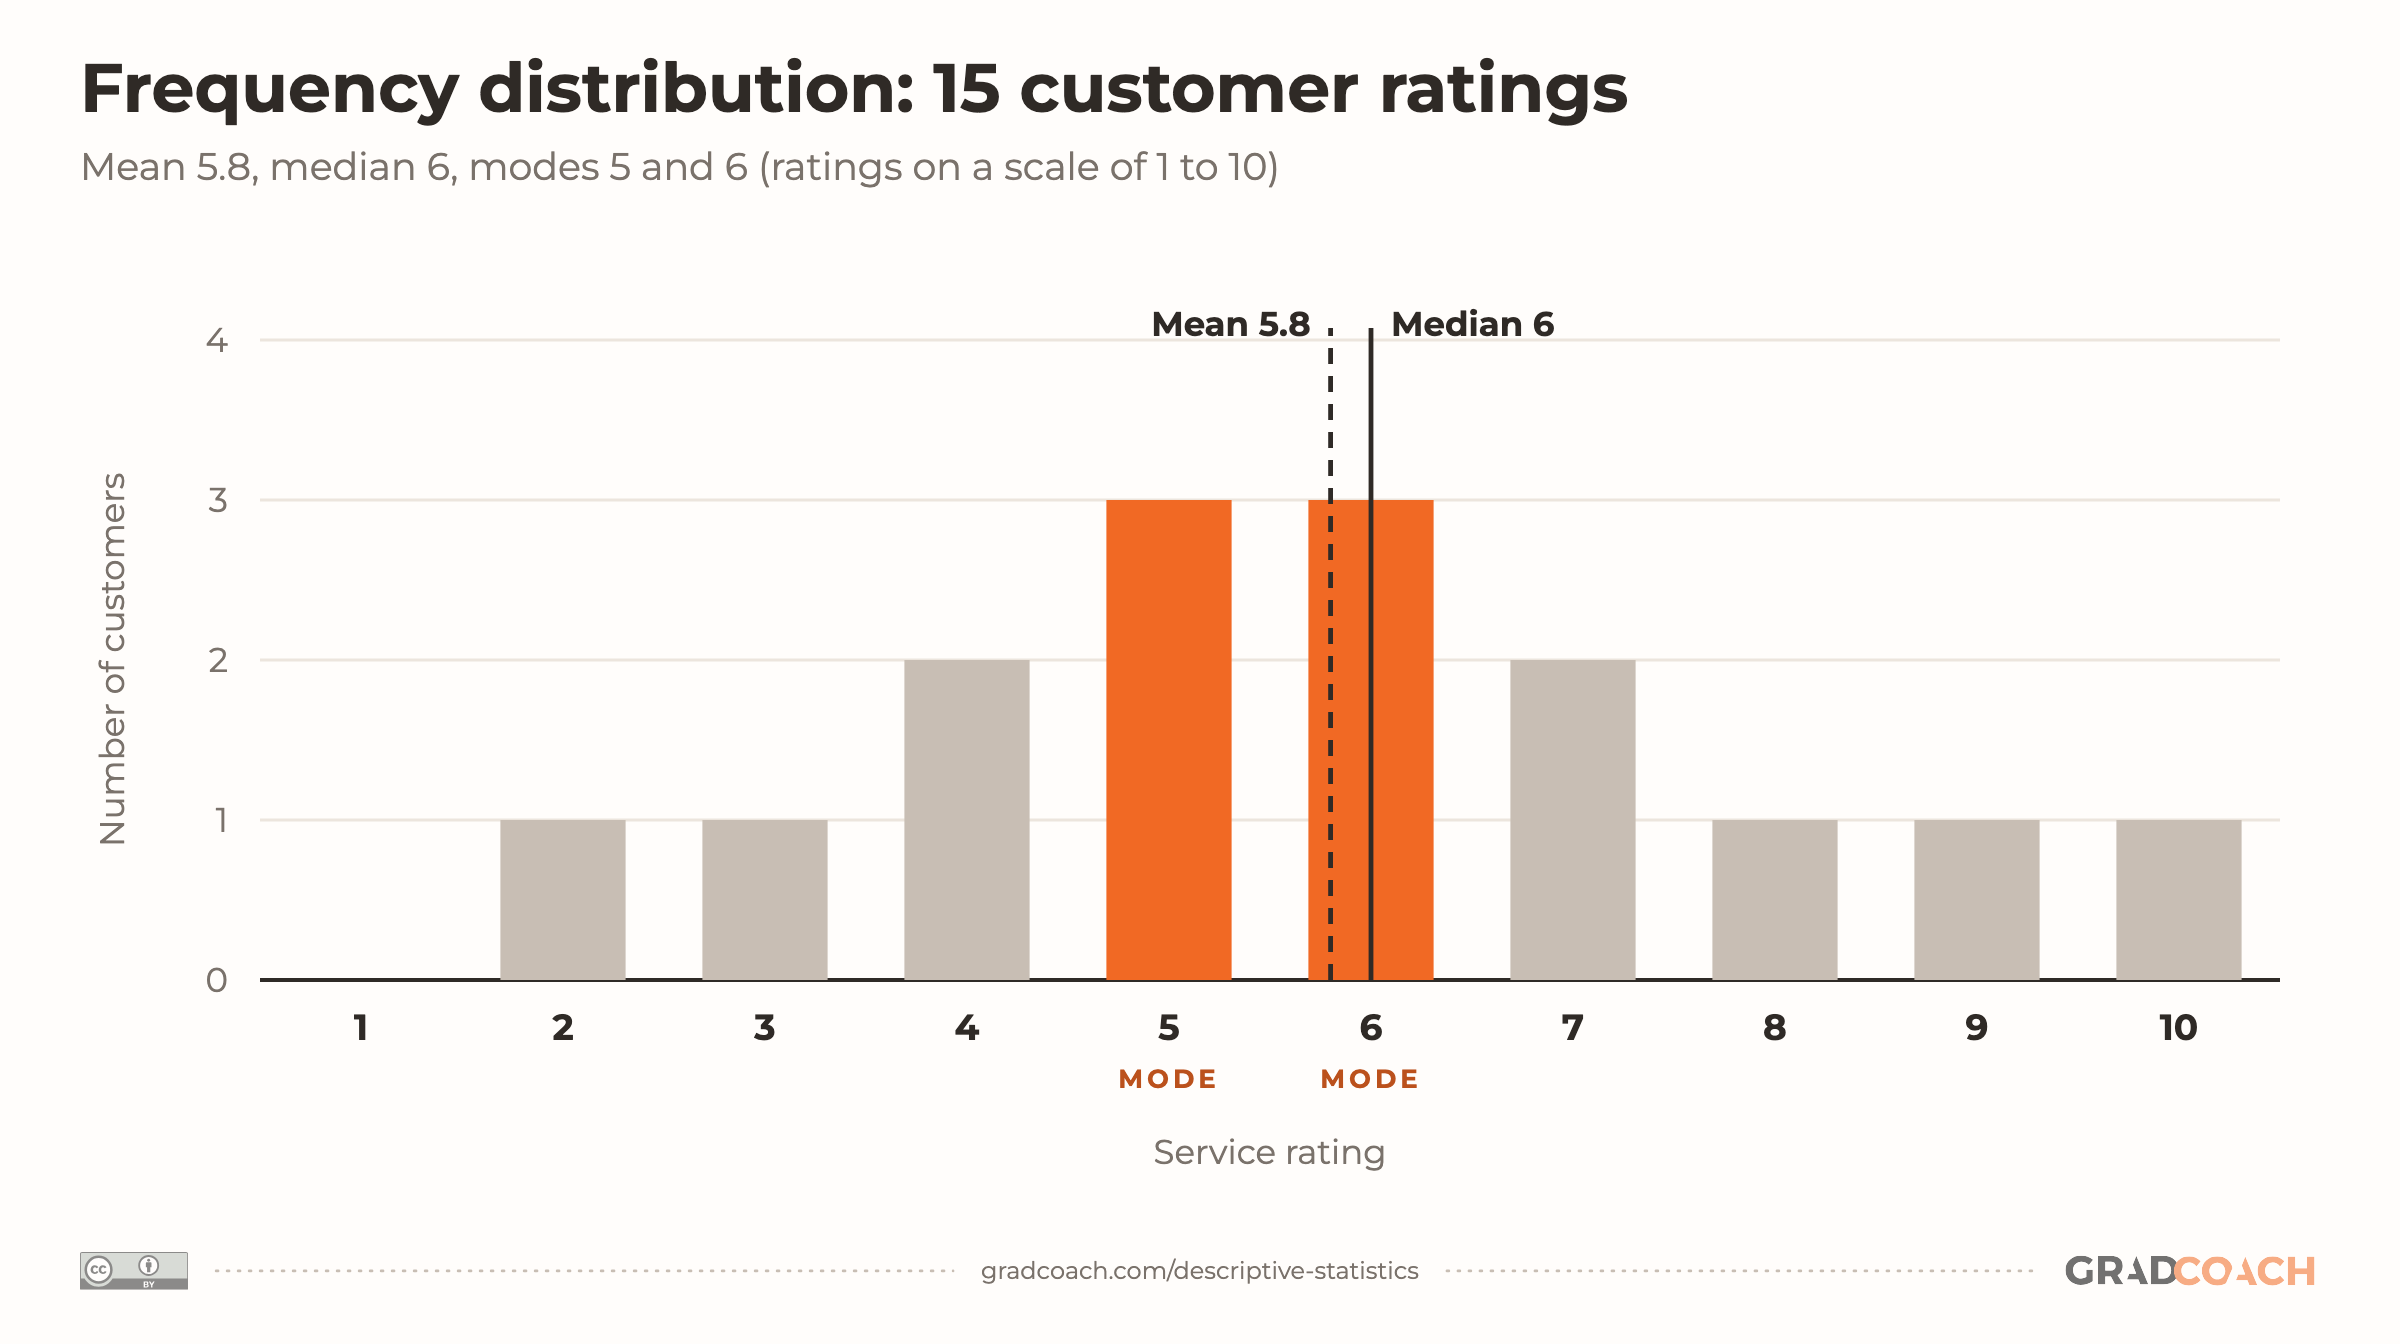
The mean of 5.8 is the 87 rating points divided by 15 customers. For the median, sort the ratings (2, 3, 4, 4, 5, 5, 5, 6, 6, 6, 7, 7, 8, 9, 10) and take the eighth, which is 6. There are two modes, because 5 and 6 each appear three times. That makes the data bimodal, and it’s a good reason to use Excel’s MODE.MULT rather than MODE, which only ever returns one value.
Together, the three tell a consistent story: a typical customer rated the service a lukewarm 5 or 6. Because the mean and median sit close together, the ratings are roughly balanced around the middle.
You can see that balance if you count how many times each rating was given and plot the counts as a bar chart, which is called a frequency distribution:

The ratings cluster in the middle and thin out toward both ends, a little like a bell. With only 15 values, though, I wouldn’t call that a normal distribution. A small sample can look bell-shaped by chance, and the skewness, which I’ll come to below, is a better guide.
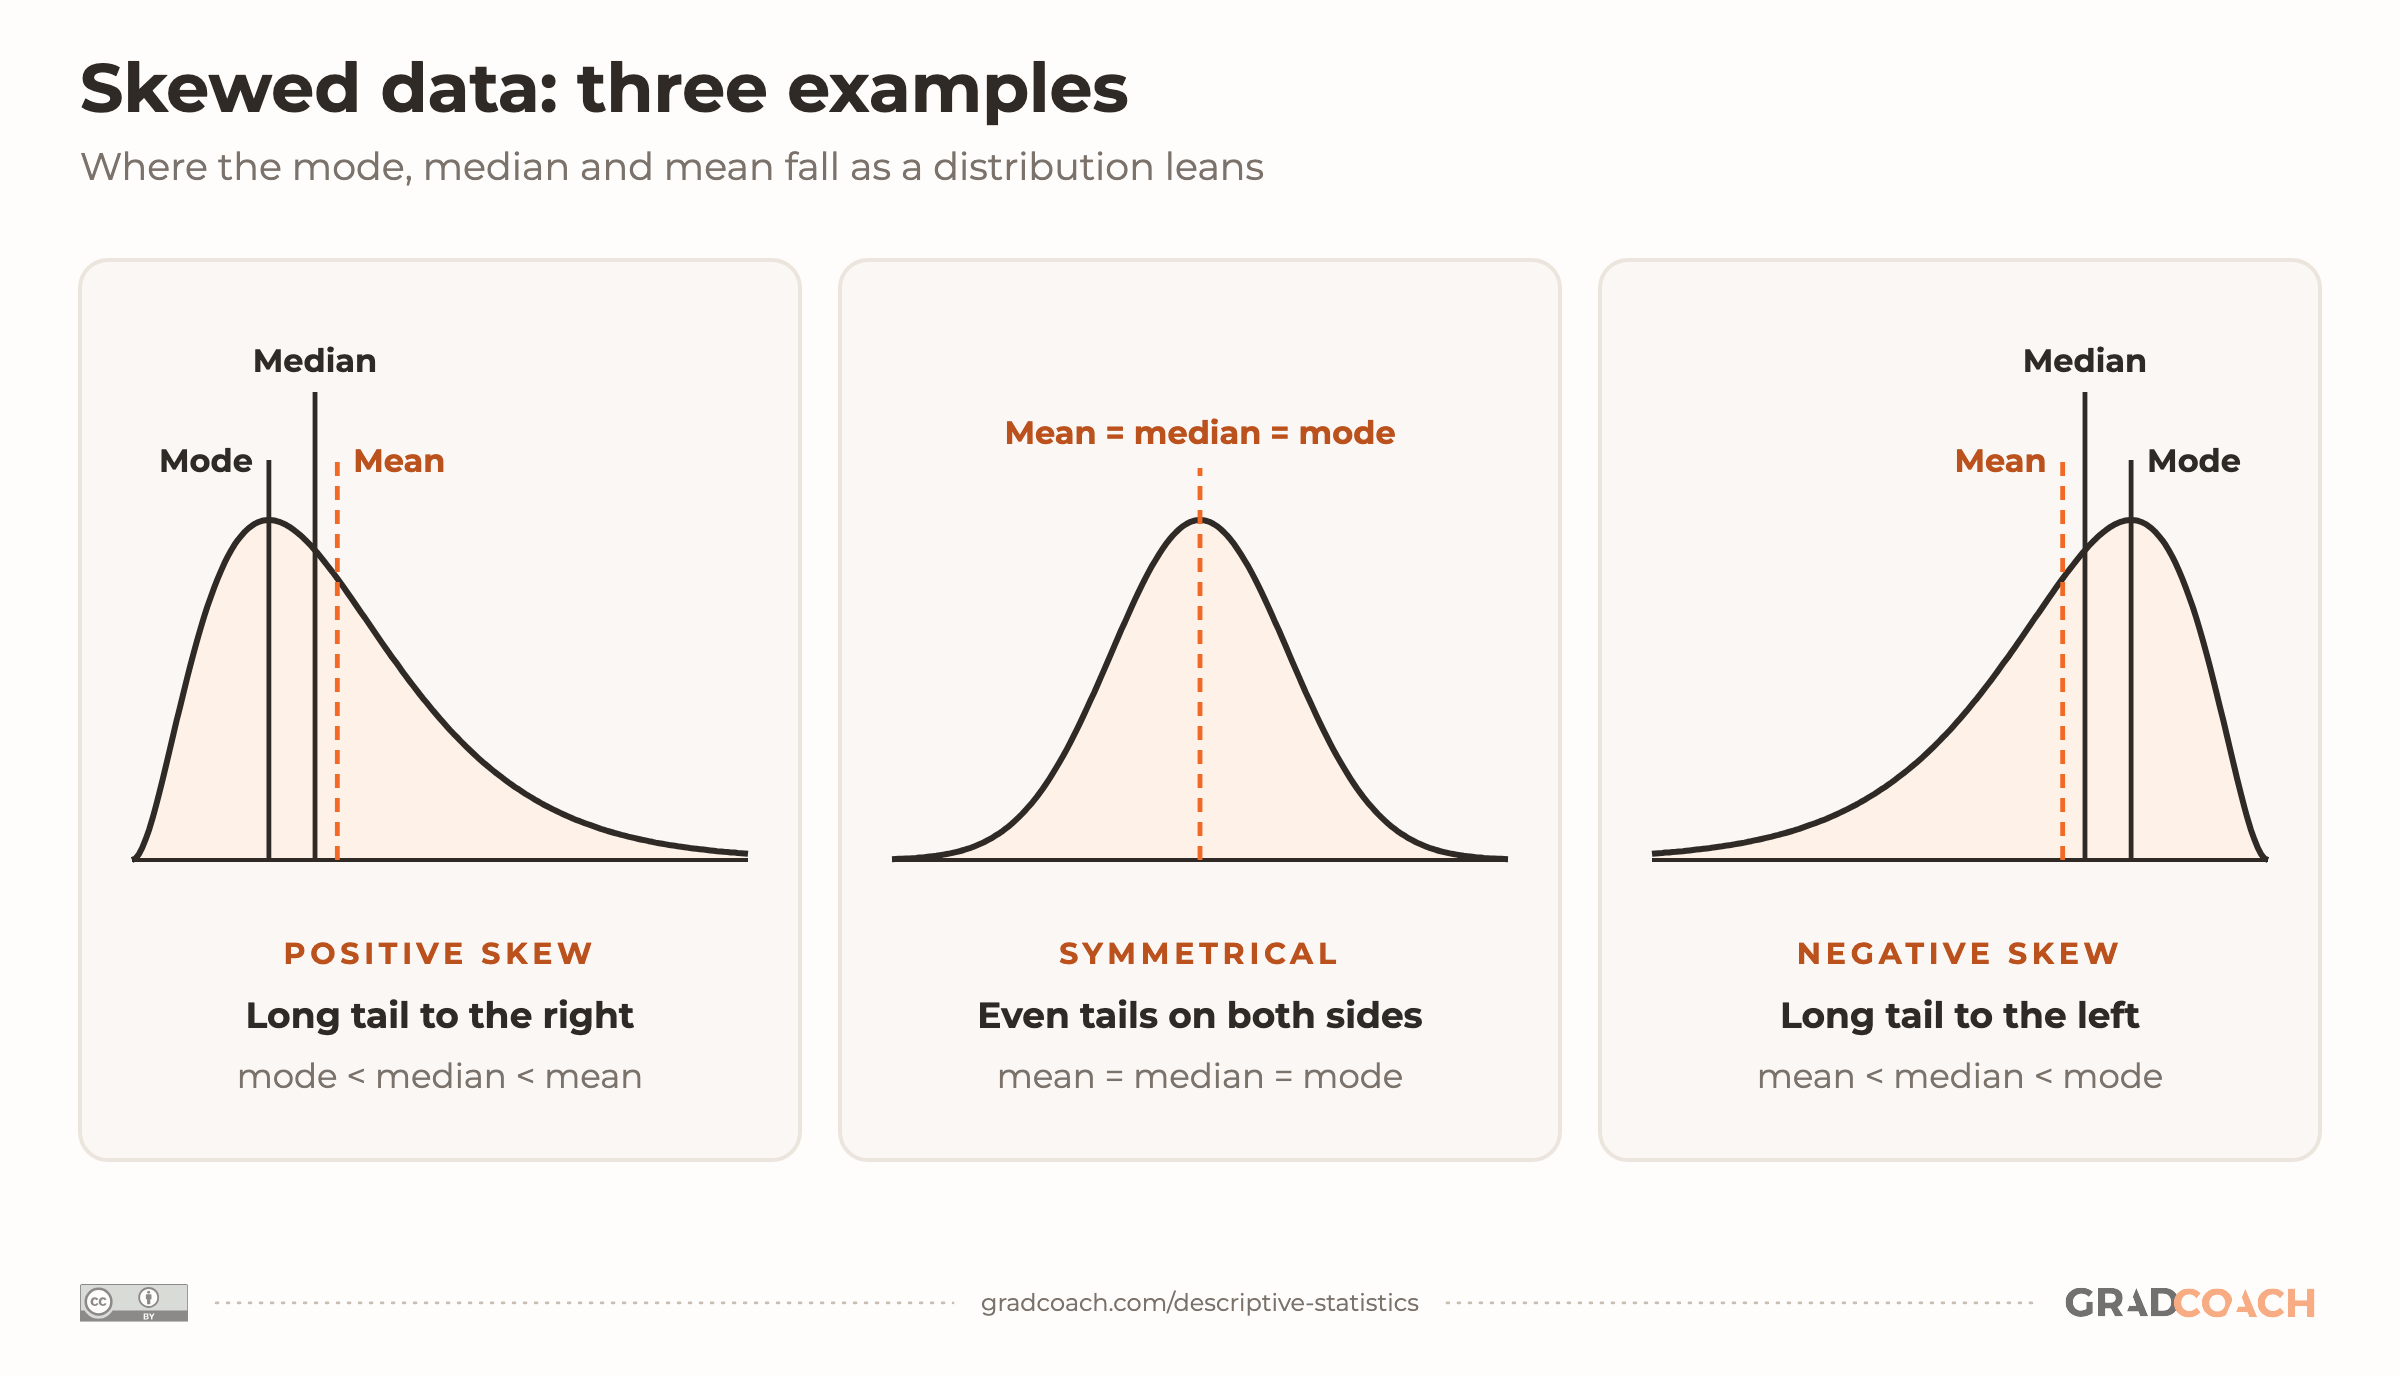
Plenty of datasets aren’t balanced at all. The values can lean toward the low or the high end, and that lean is called skewness. It matters for two reasons: it changes which measure of center describes your data honestly, and it matters again when you choose your tests.

Skewness is named after the tail, not the peak. Positive skew has a long tail toward the high values, which pulls the mean above the median; negative skew has a long tail toward the low values, which pulls the mean below it. Our customer ratings have a skewness of 0.25 (Excel’s =SKEW), a slight lean toward the high end, but close enough to zero to call the data roughly symmetrical.
You’ll often see kurtosis beside skewness in software output; it describes how heavy the tails are, and it’s usually mentioned only when it’s extreme.
Measures of dispersion
Measures of central tendency tell you where the middle is. Measures of dispersion tell you how tightly the data cluster around it, or how far they scatter. Two datasets can share a mean and look nothing alike. The four you’ll meet most often are:
- The range: The highest value minus the lowest. It’s quick, but a single extreme value can stretch it.
- The interquartile range (IQR): The spread of the middle half of the data, from the 25th percentile to the 75th. Because it ignores the extremes, it’s the natural partner for the median.
- The variance: The average squared distance of each value from the mean (software divides by one less than the number of values, as Excel’s VAR.S does, when you’re using a sample to estimate the population’s spread, which is the usual case). Larger means more spread out, but it’s in squared units, so it’s hard to read directly.
- The standard deviation (SD): The square root of the variance, which puts it back in the original units. It’s roughly the typical distance between a value and the mean, and it’s the measure you’ll report most often, alongside the mean.
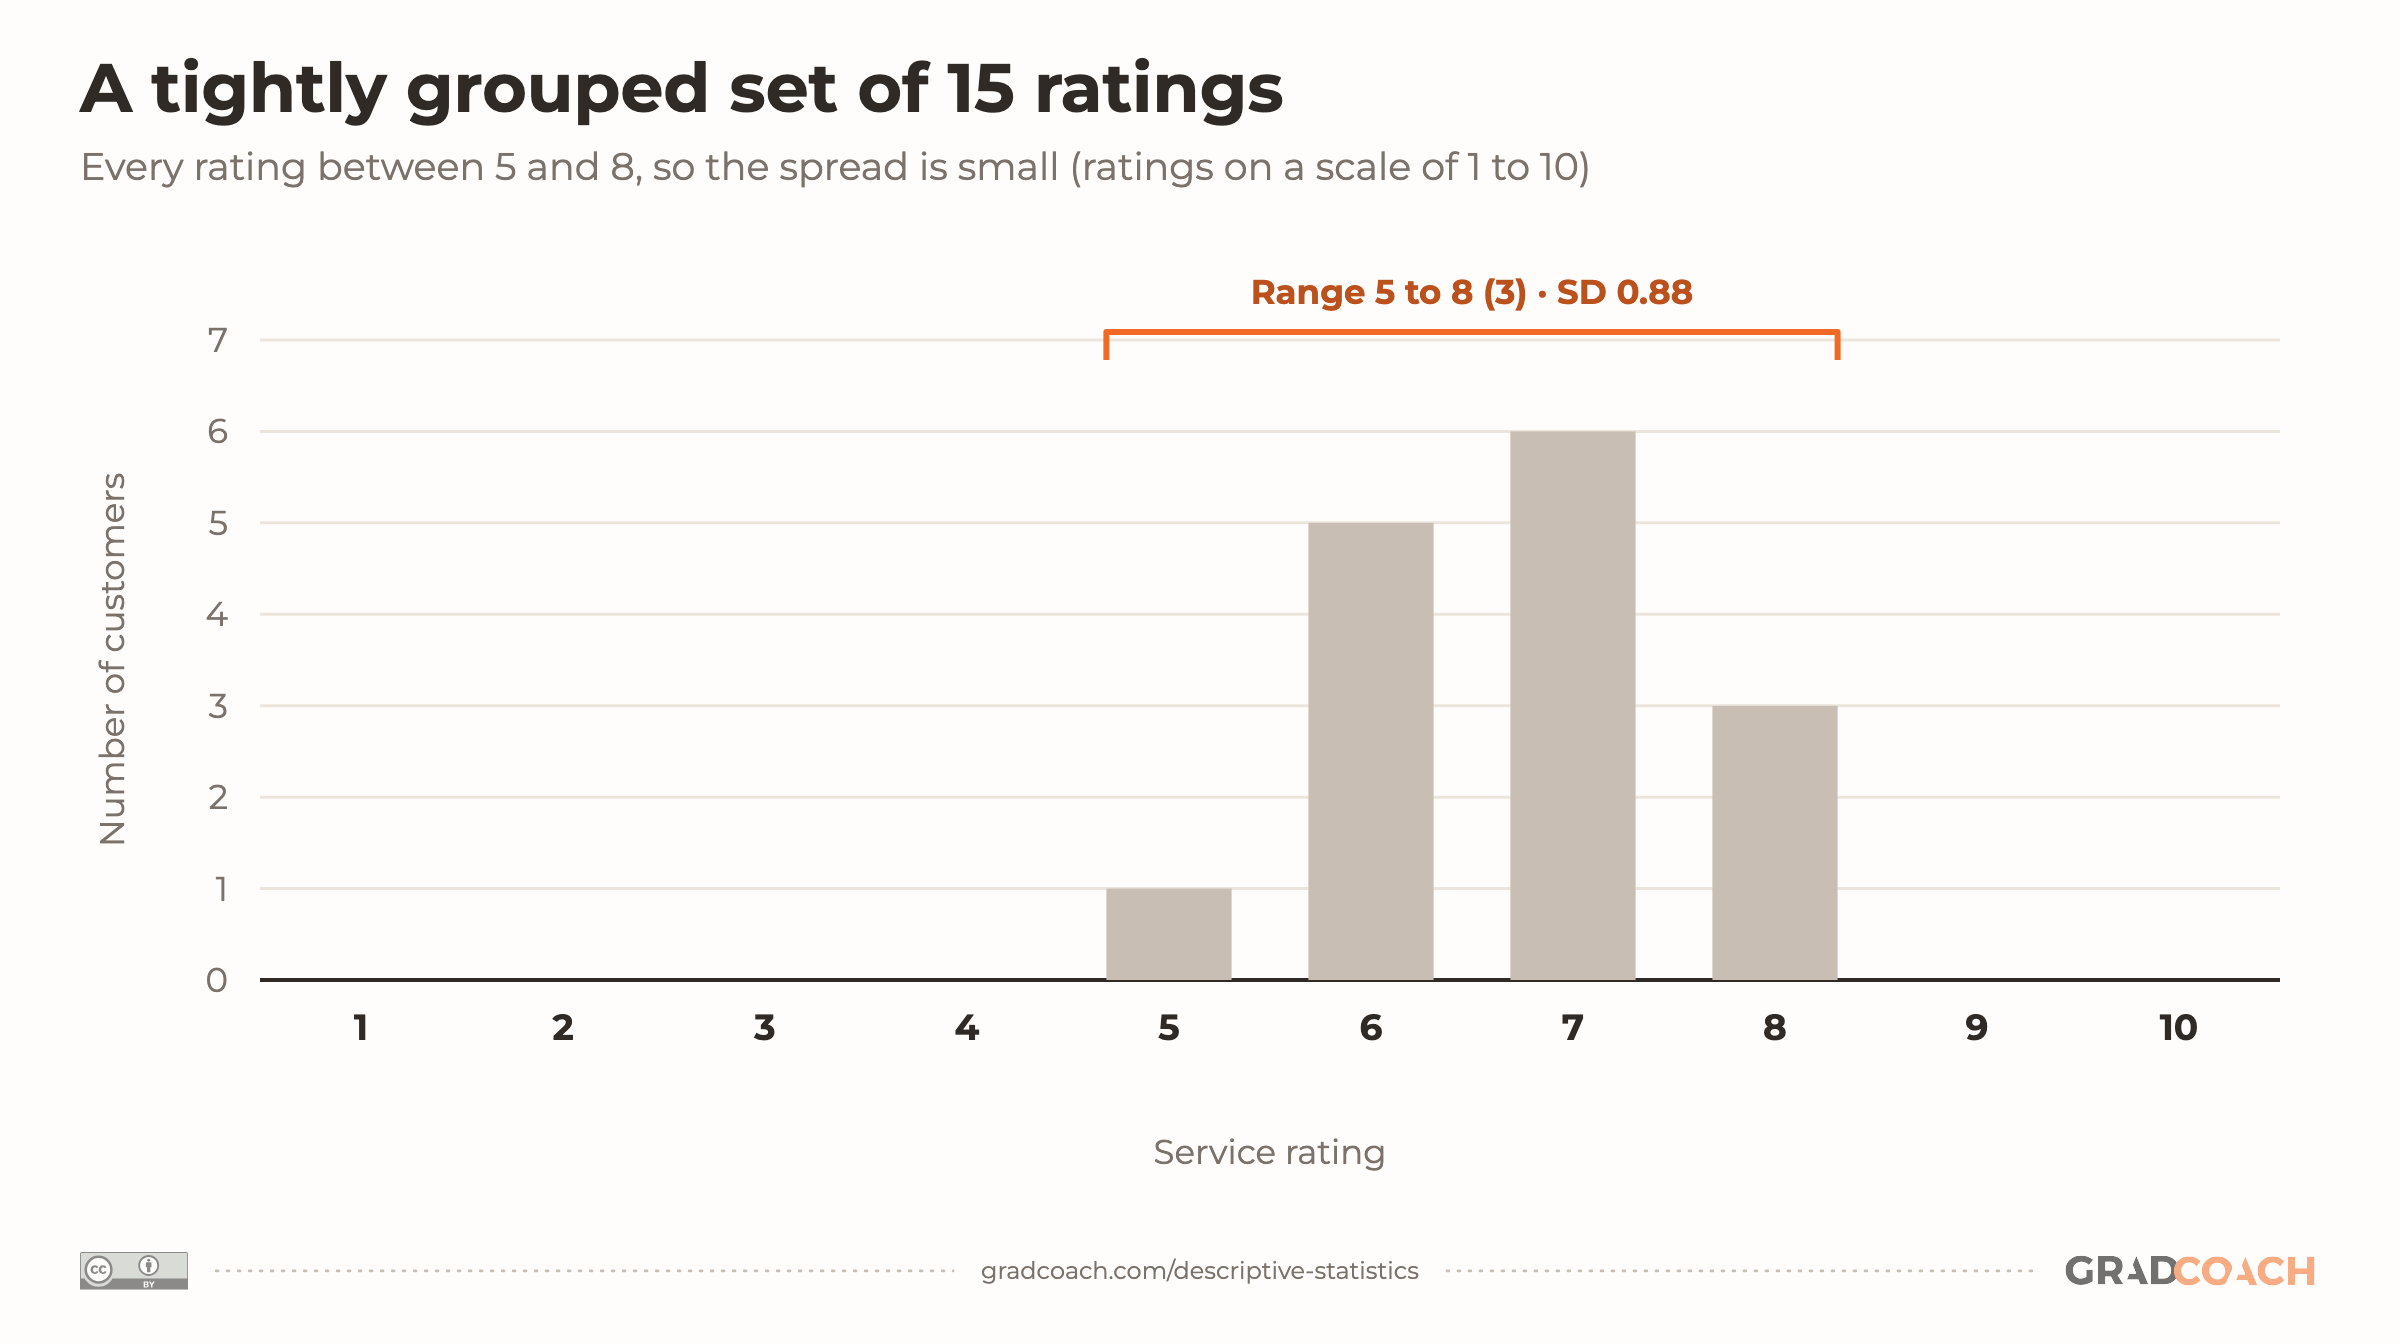
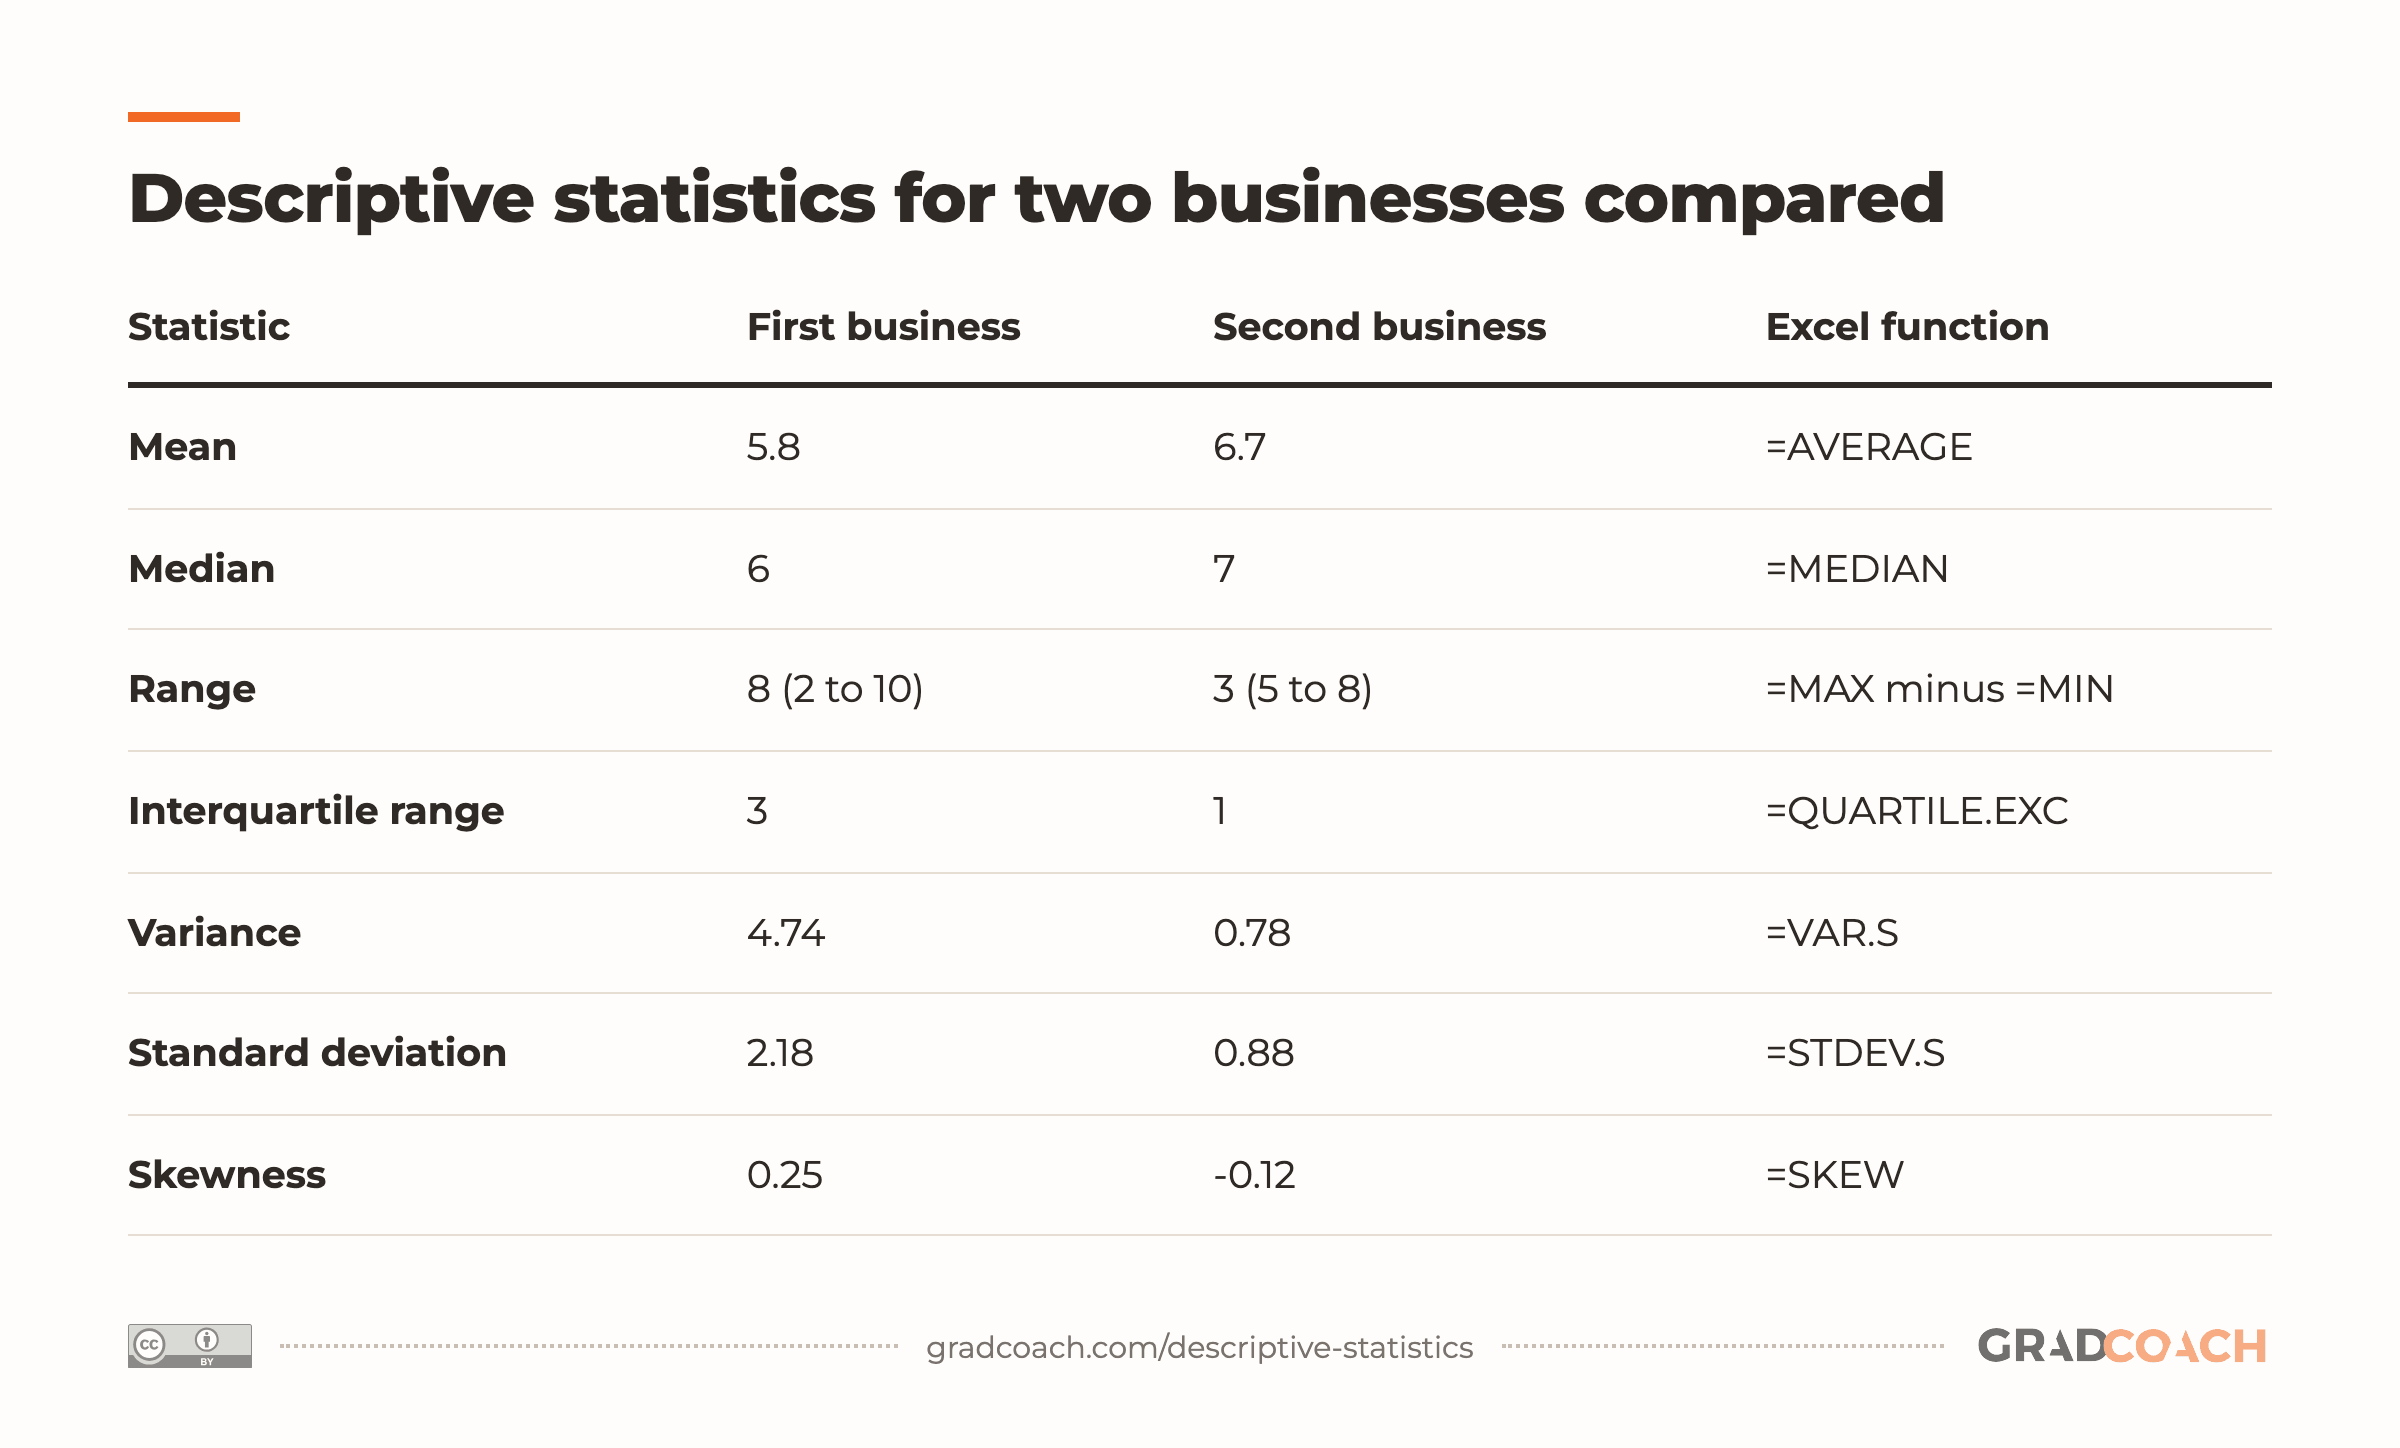
Dispersion is easiest to understand by comparison. So here’s a second illustrative set of 15 ratings, from a business whose customers mostly agreed with each other: one 5, five 6s, six 7s and three 8s. Compare its statistics with the first business’s, and watch the spread measures in particular:
| Statistic | First business | Second business | Excel function |
|---|---|---|---|
| Mean | 5.8 | 6.7 | =AVERAGE |
| Median | 6 | 7 | =MEDIAN |
| Range | 8 (2 to 10) | 3 (5 to 8) | =MAX minus =MIN |
| Interquartile range | 3 | 1 | =QUARTILE.EXC |
| Variance | 4.74 | 0.78 | =VAR.S |
| Standard deviation | 2.18 | 0.88 | =STDEV.S |
| Skewness | 0.25 | -0.12 | =SKEW |
The table shows working values to two decimal places; when you report them, round as the next section explains (2.18 becomes 2.2). Software also differs on quartiles: for the first business, QUARTILE.EXC puts them at 4 and 7, so the IQR is 3, while QUARTILE.INC gives 4.5 and 7, an IQR of 2.5. Name the method if your IQR matters.
Here’s the second business’s distribution:

Every measure of dispersion agrees. The first business’s ratings are widely spread: a range of 8 and a standard deviation of 2.18, and most ratings sit within about two points of the mean. The second business’s are tightly grouped, with a standard deviation under 1.
In roughly bell-shaped data, about two-thirds of the values fall within one standard deviation of the mean. For the first business, that’s the band from 3.6 to just under 8 (7.98), and 10 of the 15 ratings land in it (the 8 falls just outside). To get that SD by hand, square each rating’s distance from 5.8, add those up (66.4), divide by 14 to get the variance (4.74), and take the square root.
The second set’s skewness of -0.12 is a very slight lean toward the low end, close enough to zero to call symmetrical.
So never report a center without a spread. A mean of 5.8 with a standard deviation of 2.2 describes customers who disagree a lot, and the “typical” rating hides that. A mean of 6.7 with a standard deviation of 0.9 describes customers who largely agree, so the mean genuinely represents them.
Which ones should you report?
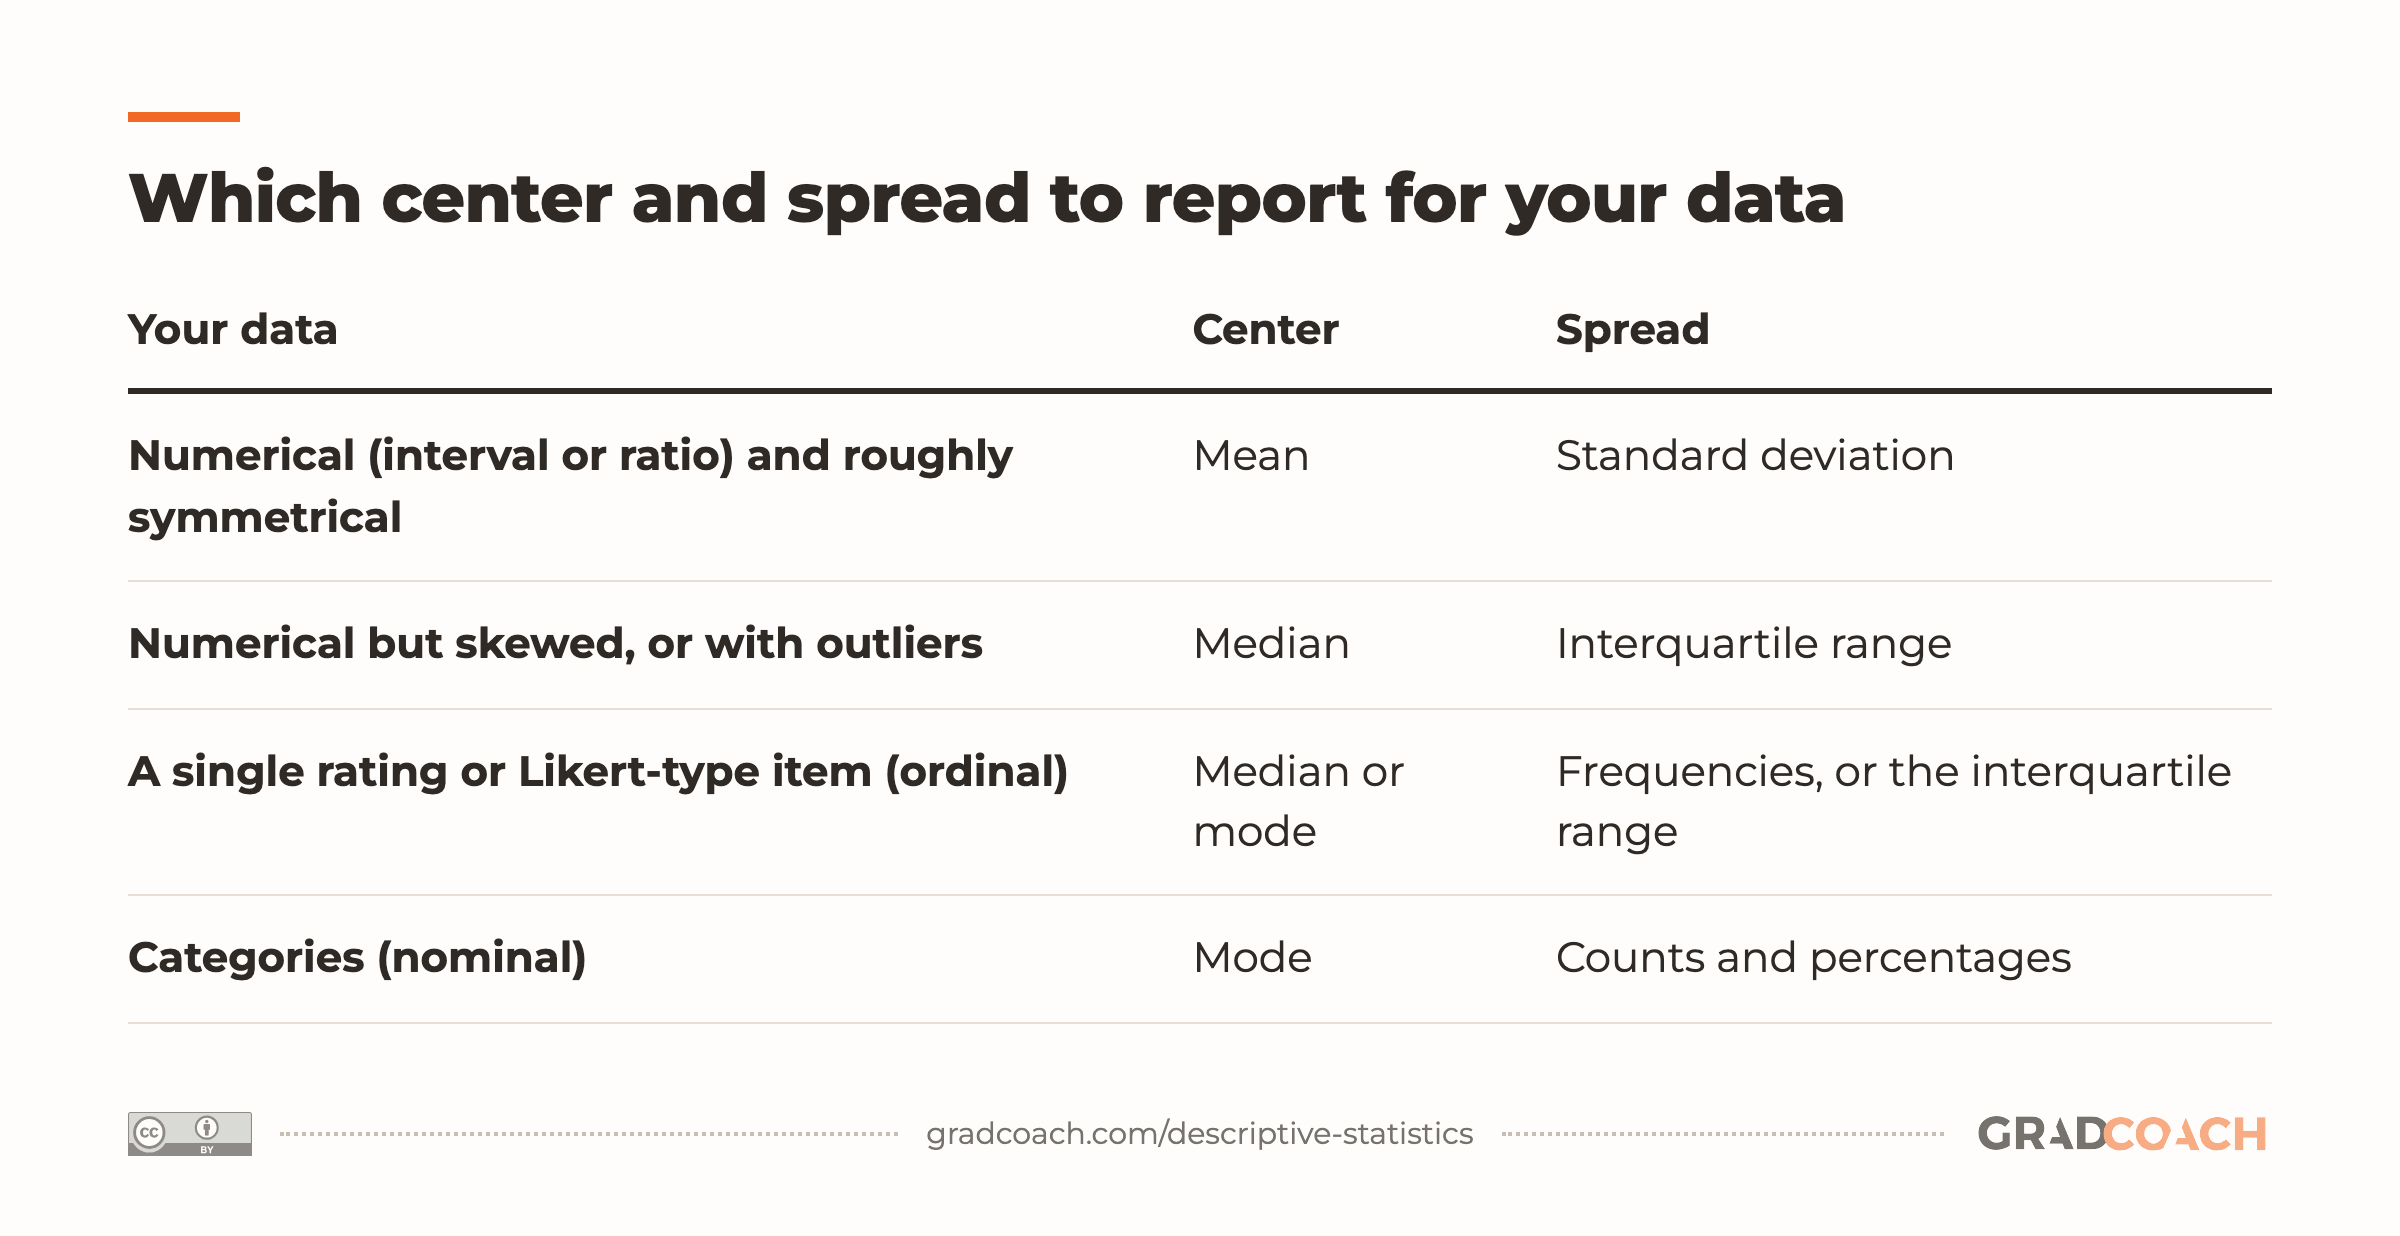
That depends on your data, mainly its level of measurement and its shape. Purdue’s writing lab puts the baseline simply: present at least one measure of central tendency and one of variability, usually the standard deviation. Which pair you choose follows from what kind of data you have:
| Your data | Center | Spread |
|---|---|---|
| Numerical (interval or ratio) and roughly symmetrical | Mean | Standard deviation |
| Numerical but skewed, or with outliers | Median | Interquartile range |
| A single rating or Likert-type item (ordinal) | Median or mode | Frequencies, or the interquartile range |
| Categories (nominal) | Mode | Counts and percentages |
The mean is the default for numerical data, but it’s pulled around by extreme values, while the median isn’t. The same review warns that when data aren’t normally distributed, the mean is “not a representative value”. Income is the classic case: a few very high earners drag the mean up, so the median describes a typical person better.
The third row needs a word of explanation, because rating scales are where students get caught. Strictly, a single rating item is ordinal data (the gap between “agree” and “strongly agree” isn’t a measured distance), so a widely used guide to Likert data recommends the median or mode and frequencies for single items, keeping the mean and standard deviation for scales built by combining several items, though even that is debated.
So if your variable is a single item, stay with ordinal methods: describe it with the median (or mode) and frequencies, and use ordinal tests if you go further. A single 1-to-10 rating is safest treated the same way (some researchers treat longer scales as interval, but that’s debated, so justify it if you do), and our customer ratings are exactly that. I’ve used them to show how the mean and standard deviation work, because the arithmetic is easiest to follow on a small set, but the write-up below reports them the way the table says.
If the levels of measurement are hazy, this video covers each one:
How to report descriptive statistics
In a dissertation or thesis, descriptive statistics go near the start of your results chapter, usually starting with your sample’s demographics (some departments put these in the methodology chapter instead), and before any inferential tests. If you follow APA style, which is widely used in the social sciences, education and nursing, you need only a few rules, all from the APA’s own numbers and statistics guide:
- Use the symbol with an equals sign (M = 3.9, SD = 0.9), but the word in running text (“the mean rating was…”). Statistical symbols such as M, SD and N are set in italics, and you don’t need to define them.
- Round sensibly. Means and standard deviations for data on whole-number scales, such as survey ratings, go to one decimal place.
- Don’t repeat a table in your text. The guide’s rule is not to give the same statistics in both. In practice, that means your paragraph points to the table and says what the key figures show, rather than copying every mean and standard deviation into prose.
Your university or department may follow a different style guide, so check its handbook first; the principles carry over even where the details change.
Applied to our first business, whose ratings come from a single item, a write-up could look like this:
Notice that it reports a center (the median) and a spread (how the ratings are distributed), and ends on what the numbers mean rather than leaving your committee to work it out. For a scale score built from several items, the same sentence would give M and SD instead, each to one decimal place. In our coaching, that last step is the one we most often see skipped.
Real dissertations follow the same shape, even with very different data. The finance doctorate below, one of our business examples and a study of banks in sub-Saharan Africa, introduces its summary statistics table and then talks through the key variables. Finance has its own house styles (it writes “mean =” rather than APA’s M), so copy the shape, not the symbols:
In a single sentence about its main variable, the passage names the center (the mean), the spread (the SD) and what both mean for the study. A paragraph later, it does the same for shape, describing one set of variables as “strongly right-skewed, reflecting infrequent but occasionally large adjustments”.
The table holds every number; the prose says which ones to look at. Do the same in yours: point to the table, pick the few figures that answer your research questions, and say in plain words what each one shows.
Before you write any of this up, run the practical checks on your own dataset. This short tutorial walks through six of them:
Your descriptives are one step in a longer chapter, and our guide to writing up quantitative results walks through the whole structure, from the sample to the hypotheses.
Still have questions?
What are the four types of descriptive statistics?
The four types are frequency (counts and percentages), central tendency (the mean, median and mode), dispersion (the range, interquartile range, variance and standard deviation) and shape (skewness). Many guides list only the first three and treat shape as part of the distribution. In our experience, a thorough dissertation write-up uses all four: frequencies to describe categories, then a center, a spread and a shape for each numerical variable.
What are five examples of descriptive statistics?
Five common examples are the mean (the average exam score in a class), the median (the middle household income in a survey), the mode (the most common answer to a multiple-choice question), the standard deviation (how far test scores typically sit from the average) and a percentage (the share of respondents who are first-generation students). Each one summarizes a set of data without making any claim beyond it.
Is ANOVA a descriptive statistic?
No. ANOVA is an inferential test: it uses sample data to judge whether the means of groups (typically three or more) differ in the wider population. The group means and standard deviations you report alongside an ANOVA are descriptive statistics, and they usually appear in a table before the ANOVA result.
Are descriptive statistics qualitative or quantitative?
Descriptive statistics are quantitative, because they summarize numbers. They can still describe non-numerical data once it’s counted: the number and percentage of interviewees who raised a theme, for example, is a descriptive statistic. Qualitative analysis itself, which interprets the meaning of words and images, isn’t.
What are the limitations of descriptive statistics?
Descriptive statistics describe only the data you collected, so they can’t tell you whether a pattern holds in a wider population or whether one variable causes another. A single summary can also hide detail: two datasets can share a mean of 6 while one is tightly grouped and the other widely spread. When you need to generalize beyond your sample, that’s the job of inferential tests.
Can’t find your answer here? Ask a Grad Coach directly – the initial chat is free.
Speak with a friendly coach →


Cite-worthy sources
Cite this article
Jansen, D. (2023). What Are Descriptive Statistics?. Grad Coach. https://gradcoach.com/descriptive-statistics/
- American Psychological Association. (2024). APA Style numbers and statistics guide [Handout].
- Baldassari, J. (2026). Improving health care proxy procurement rates for hospitalized adults - A nurse led intervention [Doctor of Nursing Practice project, University of Massachusetts Amherst].
- Boone, H. N., Jr., & Boone, D. A. (2012). Analyzing Likert data. Journal of Extension, 50(2), Article 48.
- Kasonde, R. (2026). Essays on the Basel III leverage ratio: Leverage procyclicality, bank risk, and liquidity creation in sub-Saharan Africa [Doctoral thesis, Lincoln International Business School].
- Mishra, P., Pandey, C. M., Singh, U., Gupta, A., Sahu, C., & Keshri, A. (2019). Descriptive statistics and normality tests for statistical data. Annals of Cardiac Anaesthesia, 22(1), 67-72.
- Purdue Online Writing Lab. (n.d.). Descriptive statistics. Purdue University.
- Trochim, W. M. K. (n.d.). Descriptive statistics. Research Methods Knowledge Base. Conjointly.
Found this helpful?
Keep us near the top of your Google results.