Outliers in Research: The Basics
How to find, handle and report outliers in your statistical data


The 30-second summary
An outlier is a value far from the rest of your data. You can remove one only when you can say why it doesn’t belong; being extreme isn’t enough.
- Errors get corrected, or deleted if you can’t recover the true value. A 77 on a 1-to-7 scale is a typo to fix, not a finding.
- Cases from outside your population can be removed, as long as you state the reason that puts them outside it.
- Genuine extreme values usually stay. Use methods that cope with them, or report your results with and without them.
- The 1.5 × IQR rule flags values more than 1.5 IQRs outside the box. It shows you where to look; the decision is still yours.
- Your write-up names the rule, how many cases you removed and why. Ideally, set the rule before you see any results.
Want a head start? Our free methodology chapter template has a data analysis section ready for your outlier rule.
Navigate
A statistical outlier puts you in an awkward spot. Delete it and you may be throwing away a real participant; keep it and it can distort every result you report. Either way, your committee (your examiners, in the UK) will want to know what you did and why.
We’ve worked with 10,000+ students, and one mistake we see again and again in analysis chapters is deleting outliers on reflex, as if flagging a value settled the question. In this post, I’ll explain what outliers are and how to find them, then show you how to decide what to do with one. I’ll also show you how three doctorates handled theirs, and give you a template for reporting your own decision.
What is an outlier in statistics?
The NIST/SEMATECH engineering statistics handbook, from the US National Institute of Standards and Technology, defines an outlier in one sentence:
That word appears is doing a lot of work. An outlier is a suspicion, not a verdict.
Here’s what one extreme value can do to an average:
Outliers in research data work the same way. A participant who took ten times longer than everyone else to finish a task, a company far larger than the others in your sample, or a score typed in wrong: each one sits far from the rest.
Why outliers matter in your research
They matter because a single extreme value can pull your mean and inflate your standard deviation (the typical distance between a value and the mean), and with them every inferential test built on those numbers. That’s why screening for outliers comes before any of the quantitative analysis methods you plan to run.
In a small sample, one or two cases can be the difference between a significant result and a non-significant one. In our coaching sessions, we’ve seen an apparently significant effect disappear once two extreme cases came out.
That cuts both ways, which is why examiners watch this step closely. Deleting values until a result turns significant is a recognized problem: a study of outlier removal in psychology journals starts from the premise that it is “a questionable research practice that appears to be commonly used in psychology.” The study itself failed to find that removing outliers went with weaker evidence, but that concern is exactly why your committee will look.
So before you remove anything, make sure you can show a reader why it had to go.
“Surely if it’s extreme, it’s wrong?”
Not necessarily. Some outliers are mistakes, and some are the most interesting cases in your data. Which one you have decides what you’re allowed to do with it.
The three types of outlier
Before you reach for a formula, look at the case itself. Leys and colleagues’ widely cited guide to managing outliers sorts them into errors, “interesting” outliers that may point to something worth studying, and “random” outliers that turn up by pure chance. For a dissertation, the practical sorting comes down to three causes, and each one points to a different action:
- It’s an error. A typo, a coding slip or a faulty measurement. The guide’s example is a “77” on a 1-to-7 scale, caused by hitting the 7 twice. Correct it from your raw records if you can. If you can’t recover the true value, delete it, because it was never a real observation.
- It comes from outside your population. Your study is about first-year teachers and one respondent turns out to have taught for twenty years, or a participant didn’t meet your inclusion criteria. You can remove the case, but you need a stated reason that puts it outside the population you defined. A big number on its own doesn’t do that.
- It’s a genuine extreme value. A real participant, measured correctly, who happens to sit far from everyone else. Large samples throw these up by chance. This is the case where removal is hardest to defend, and where you should usually keep the value and choose methods that can cope with it.
In practice, the first two are easy to defend and the third is where students get into trouble. Ideally, errors are caught before any outlier test, during data cleaning, when you check that every value is possible. A rule like the IQR rule (which we’ll look at in a second) then flags what’s left, and a flagged value that isn’t an error or a misfit is usually a genuine one.
How to find outliers: the IQR rule
Start by plotting your data: a histogram or box plot for one variable, a scatterplot for two. Values that sit apart are your candidates. A rule then makes the call consistent, and the one most people mean when they talk about finding outliers is the interquartile range (IQR) rule, also called Tukey’s fences after John Tukey, the statistician who popularized the box plot.
It’s the rule behind the separate points on a box plot: R’s default box plot, for example, lets the whiskers reach up to 1.5 box-lengths from the box and returns any point beyond them as an outlier.
The IQR is the spread of the middle half of your data, from the first quartile (Q1, the value a quarter of the way up your data when it’s in order) to the third (Q3, three quarters of the way up). The rule builds a fence 1.5 IQRs beyond each end of that box:
- Find Q1 and Q3, and subtract to get the IQR.
- Multiply the IQR by 1.5.
- Add that amount to Q3 to get the upper fence, and take it away from Q1 to get the lower fence.
- Treat any value above the upper fence or below the lower fence as a potential outlier.
Both fences count: a value can be just as extreme at the bottom of your data as at the top.
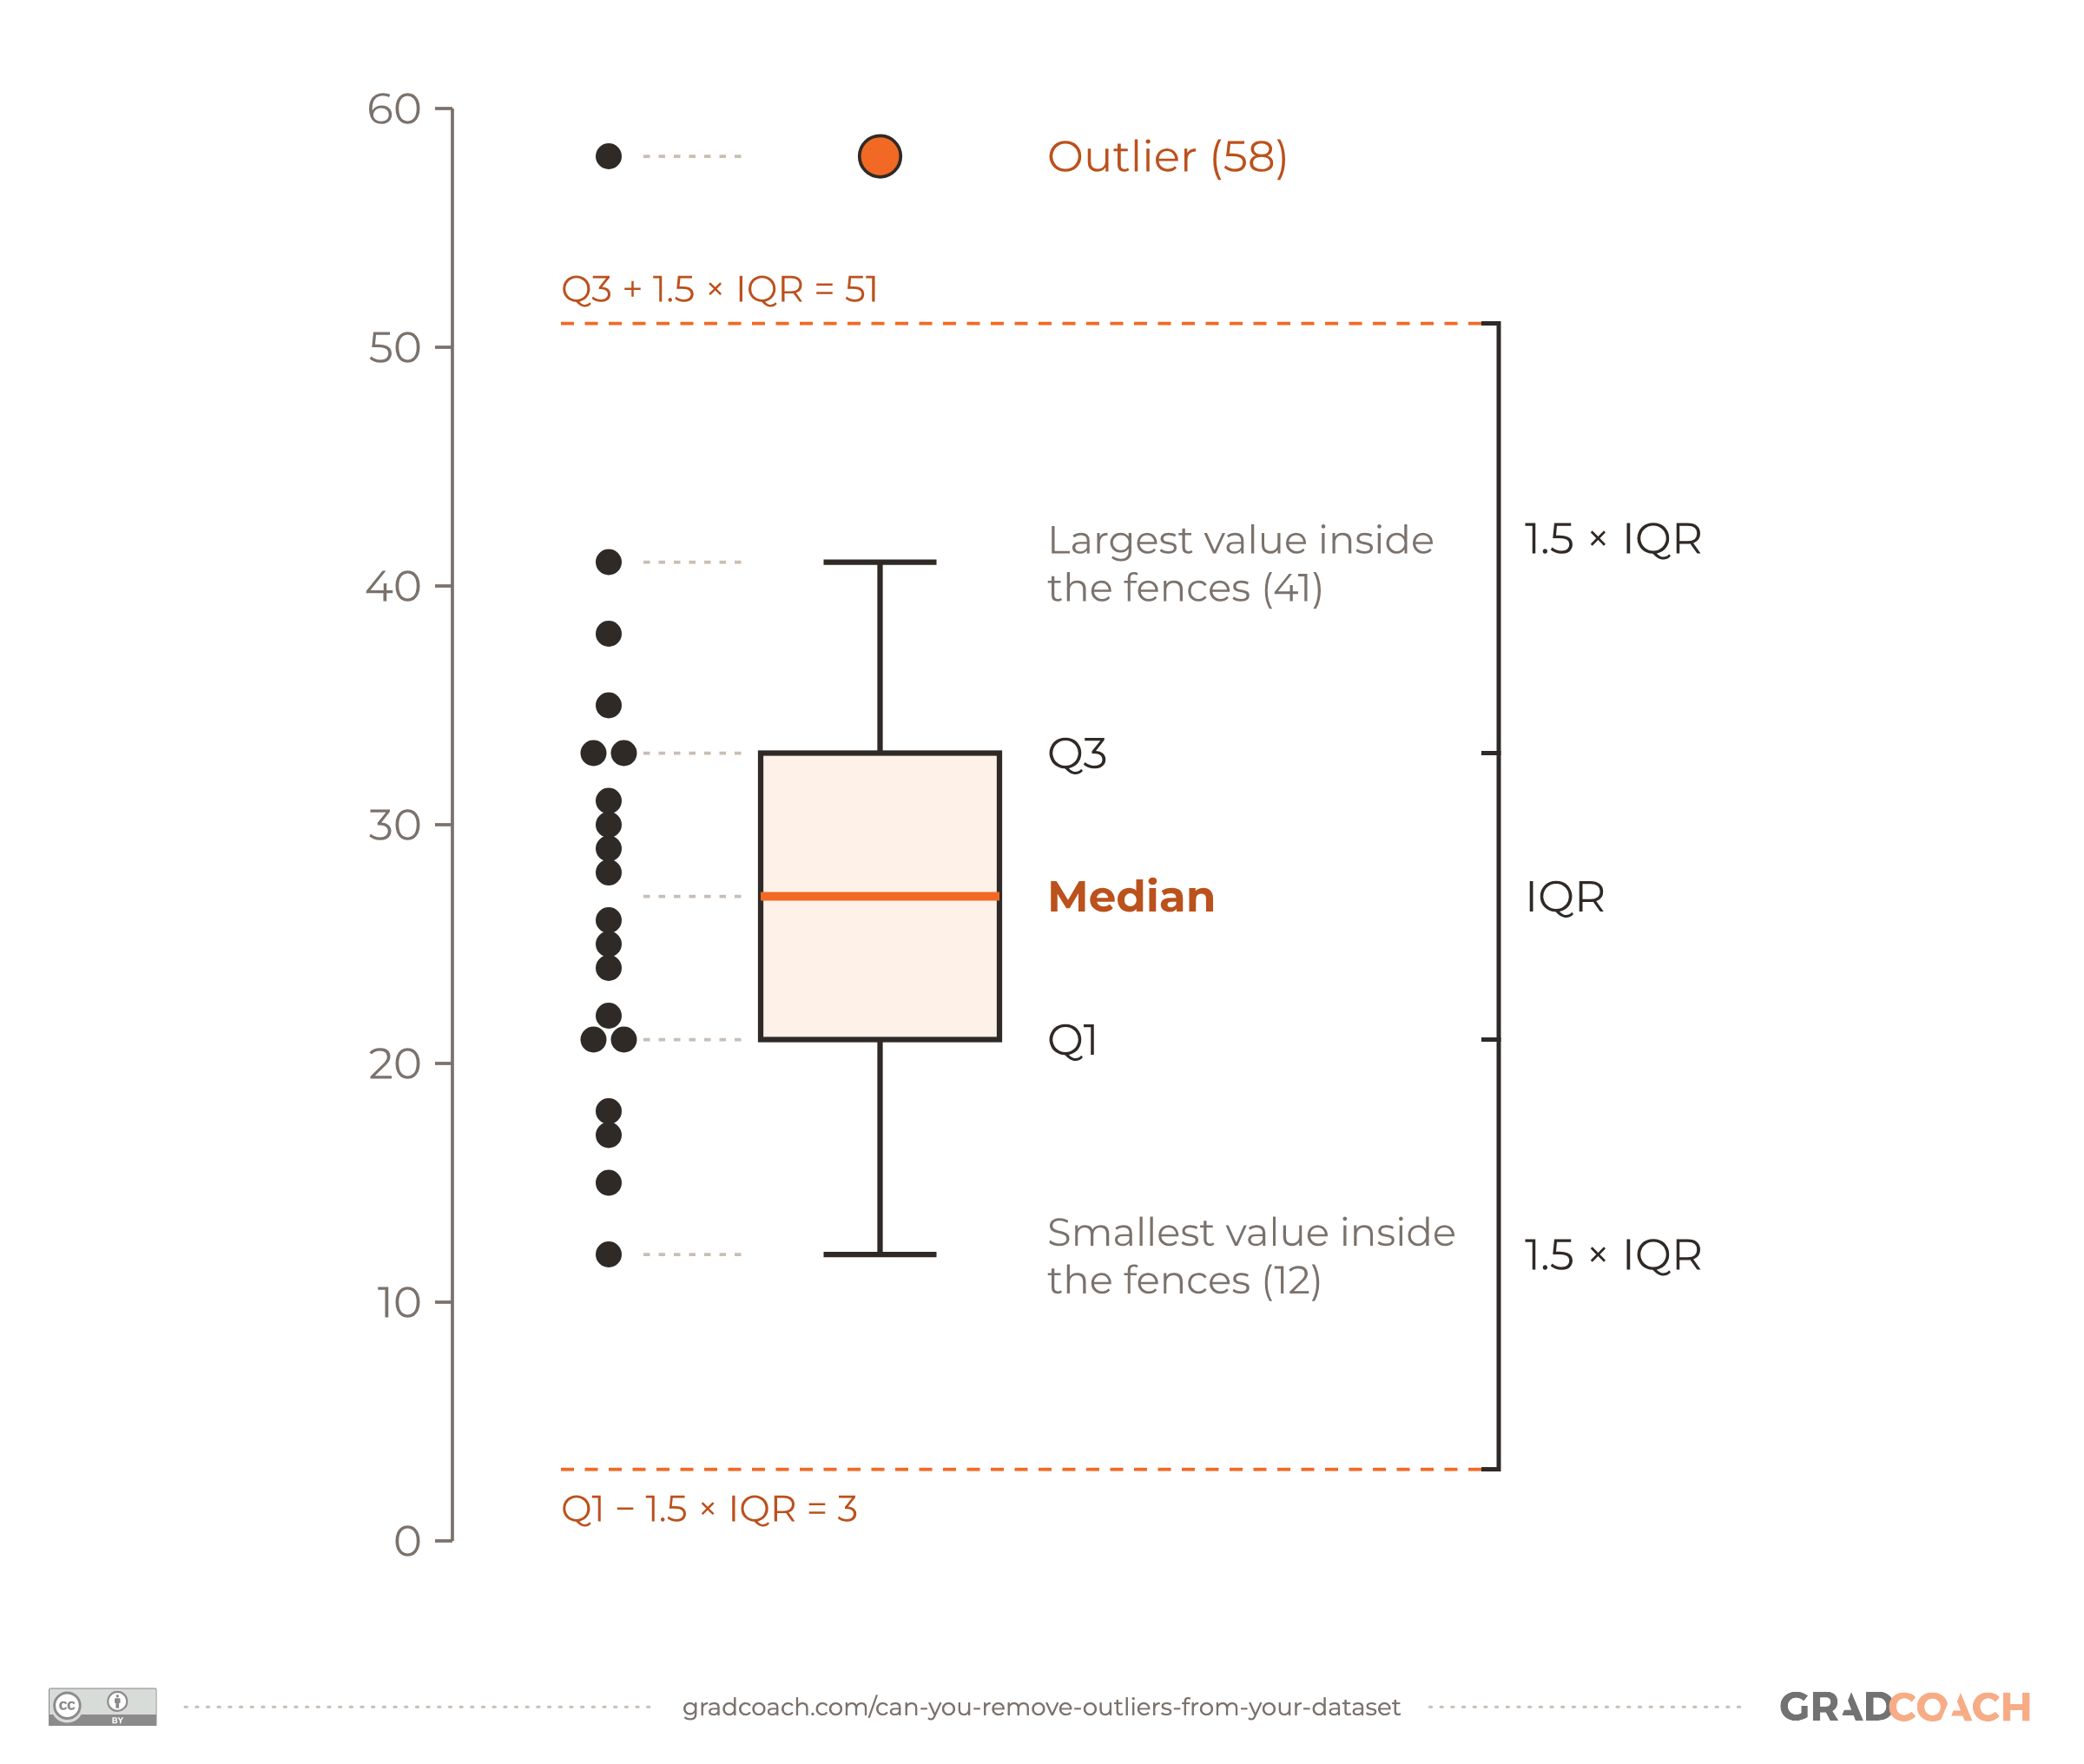
To see it working, take these 20 values: 12, 15, 17, 18, 21, 21, 22, 24, 25, 26, 28, 29, 30, 31, 33, 33, 35, 38, 41 and 58. Q1 is 21 and Q3 is 33, so the IQR is 12. One and a half times that is 18, which puts the upper fence at 51 (33 + 18) and the lower fence at 3 (21 − 18). Only 58 falls outside, and the box plot below shows it sitting above the upper fence.

Notice what the plot does and doesn’t tell you. It flags 58. It can’t tell you whether 58 is a typo for 28, a participant from outside your population or a real person with an unusual score. That’s the question from the section above, and only your records can answer it. I’d treat the IQR rule as a screening step: it tells you where to look, and the decision is still yours.
Two details are worth knowing before you cite this rule. The first is that the NIST handbook also describes outer fences at 3 IQRs, and calls a point beyond the inner fence a “mild outlier” and one beyond the outer fence an “extreme outlier”. Here the outer fence is 69, so 58 is a mild outlier.
The second is that software packages calculate quartiles in slightly different ways, which can move a fence on a small dataset. These 20 values were chosen so the common methods agree, but yours may not, so say which program you used. If you’re curious, our guide to descriptive statistics shows two Excel functions disagreeing on the same data.
If you’d like a refresher on the mean, median, standard deviation and the other descriptive statistics these rules lean on, the video below walks through them:
Other ways to flag an outlier
The IQR rule isn’t the only option, and depending on your field it may not even be the usual one. In psychology, the guide cited above reports that researchers mostly flag values more than 3 (or 3.29) standard deviations from the mean, and it recommends an approach based on the median absolute deviation (MAD, the typical distance between a value and the median), “with a cutoff of 3”, because the mean and standard deviation “can be substantially influenced by the outliers they are meant to detect.”
The guide is also frank about the limits of any rule:
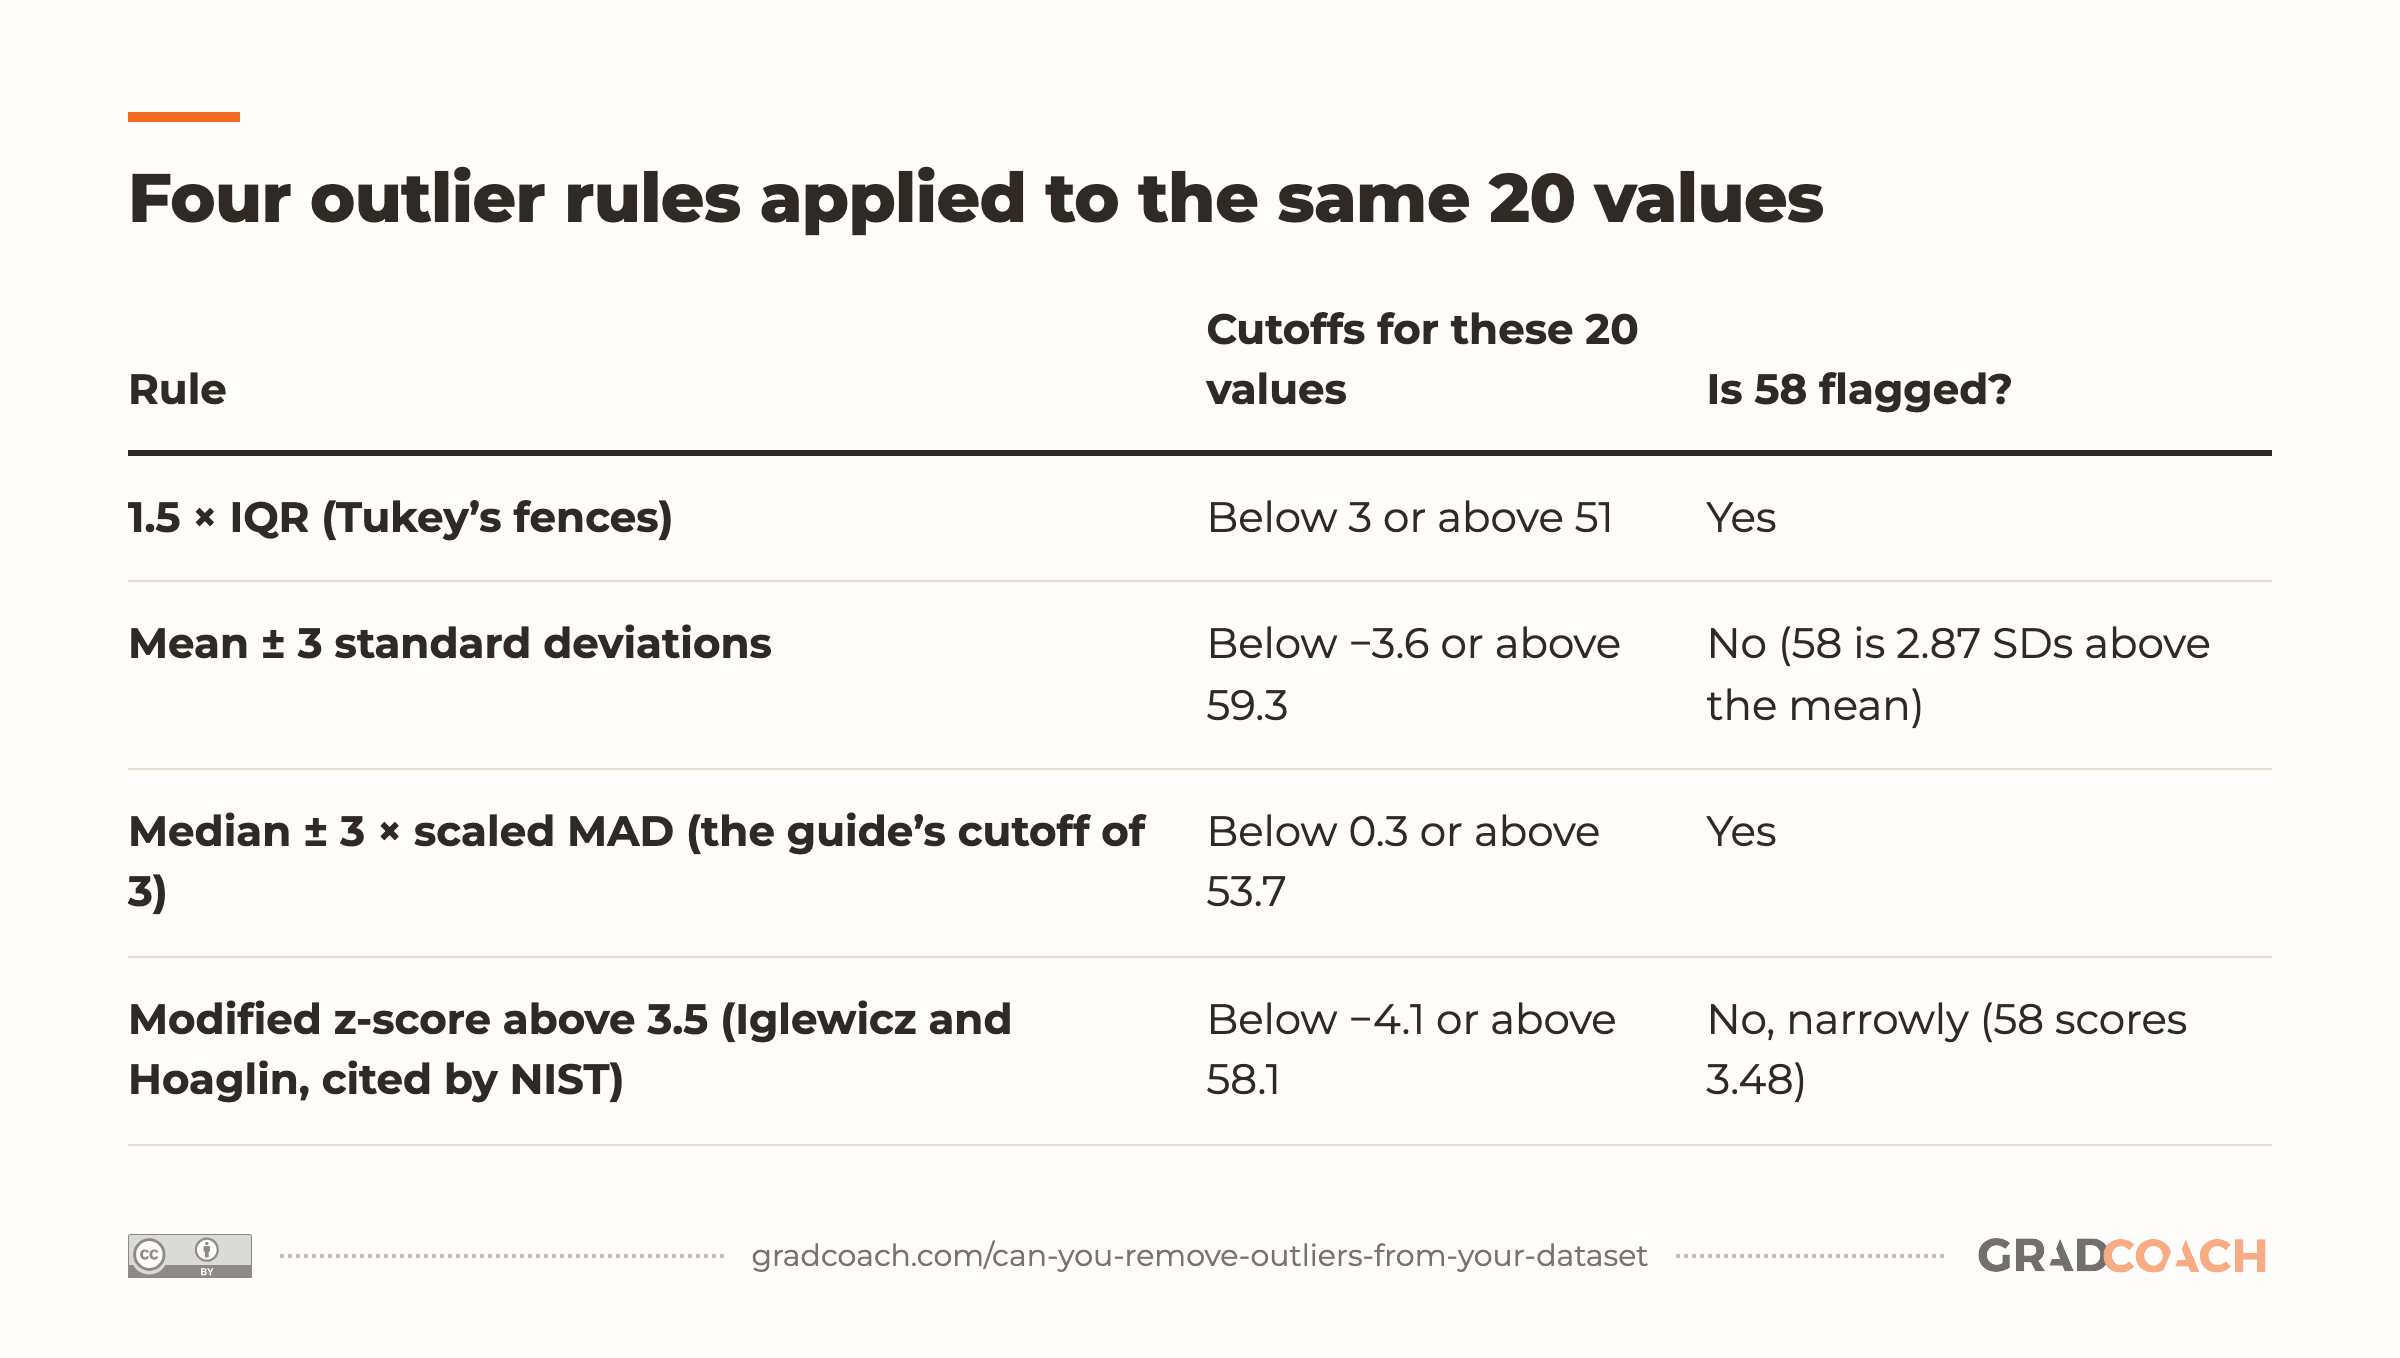
Here’s what four rules make of the same 20 values. Read down the last column: the rules don’t agree.
| Rule | Cutoffs for these 20 values | Is 58 flagged? |
|---|---|---|
| 1.5 × IQR (Tukey’s fences) | Below 3 or above 51 | Yes |
| Mean ± 3 standard deviations | Below −3.6 or above 59.3 | No (58 is 2.87 SDs above the mean) |
| Median ± 3 × scaled MAD (the guide’s cutoff of 3) | Below 0.3 or above 53.7 | Yes |
| Modified z-score above 3.5 (Iglewicz and Hoaglin, cited by NIST) | Below −4.1 or above 58.1 | No, narrowly (58 scores 3.48) |
The standard deviation rule misses 58 for exactly the reason the guide warns about: 58 itself inflates the standard deviation, which widens the cutoff that’s meant to catch it. The last two rows use the same median-based calculation and differ only in the cutoff, which is the whole point: the cutoff is a choice.
Not every mean-based method misses 58, either. For a single suspected outlier in roughly normal data, the NIST handbook names Grubbs’ test as “the recommended test”, and on these values it does flag 58 (its statistic is 2.87, above the 2.71 cutoff for 20 values at the .05 level).
The practical lesson is that your choice of rule can decide the outcome, so choose it before you look at your results.
All of these rules look at one variable at a time. A case can also be ordinary on each variable but unusual in combination, such as a participant who is young and very senior in their job. That’s a multivariate outlier, and if you’re running a regression or a MANOVA, your committee may ask whether you checked for them.
The usual check is Mahalanobis distance, which measures how far a case sits from the center of all your variables at once. It has the same weakness as the standard deviation rule, so Leys and colleagues recommend a robust version based on the minimum covariance determinant (MCD).
How to handle outliers
Once a value is flagged and you know what kind it is, you have three options. Leys and colleagues’ guide lists them:
- Keep the outliers
- Remove the outliers
- Recode the outliers
Errors get corrected or removed. For everything else, here’s what each option looks like in a real dissertation.
Keep them, and say why
The extract below, from a clinical psychology doctorate at the University of Lincoln, flagged 23 cases and kept every one. Pay close attention to how it separates them from the errors it had already removed:
The passage suggests why that decision holds up: it names the rule and its source, gives the count, explains why the values are plausible, and points to guidance for keeping them. Keeping flagged data needs a justification as much as removing it does, so write the reason down either way.
Remove them, then check it didn’t matter
Sometimes you do want the cleaner analysis. The safeguard is to show that your conclusion doesn’t depend on it. The extract below comes from a replication study, written with co-authors, inside a publication-based psychology doctorate from the University of Bamberg. Here the authors did remove outliers, and they say plainly that the rule wasn’t preregistered (set out in advance in a time-stamped registry):
Three things make this defensible:
- The exclusion is labeled as not preregistered.
- The rule is tied to a published convention in that research area.
- Two follow-up analyses are reported as not sensitive to including or excluding the outliers.
The main comparison wasn’t significant before the exclusion either, so nothing hinged on it. If you remove values, run your key analysis both ways and report what changed; a sentence or a footnote can be enough to show the decision didn’t create your result.
What removing one value does
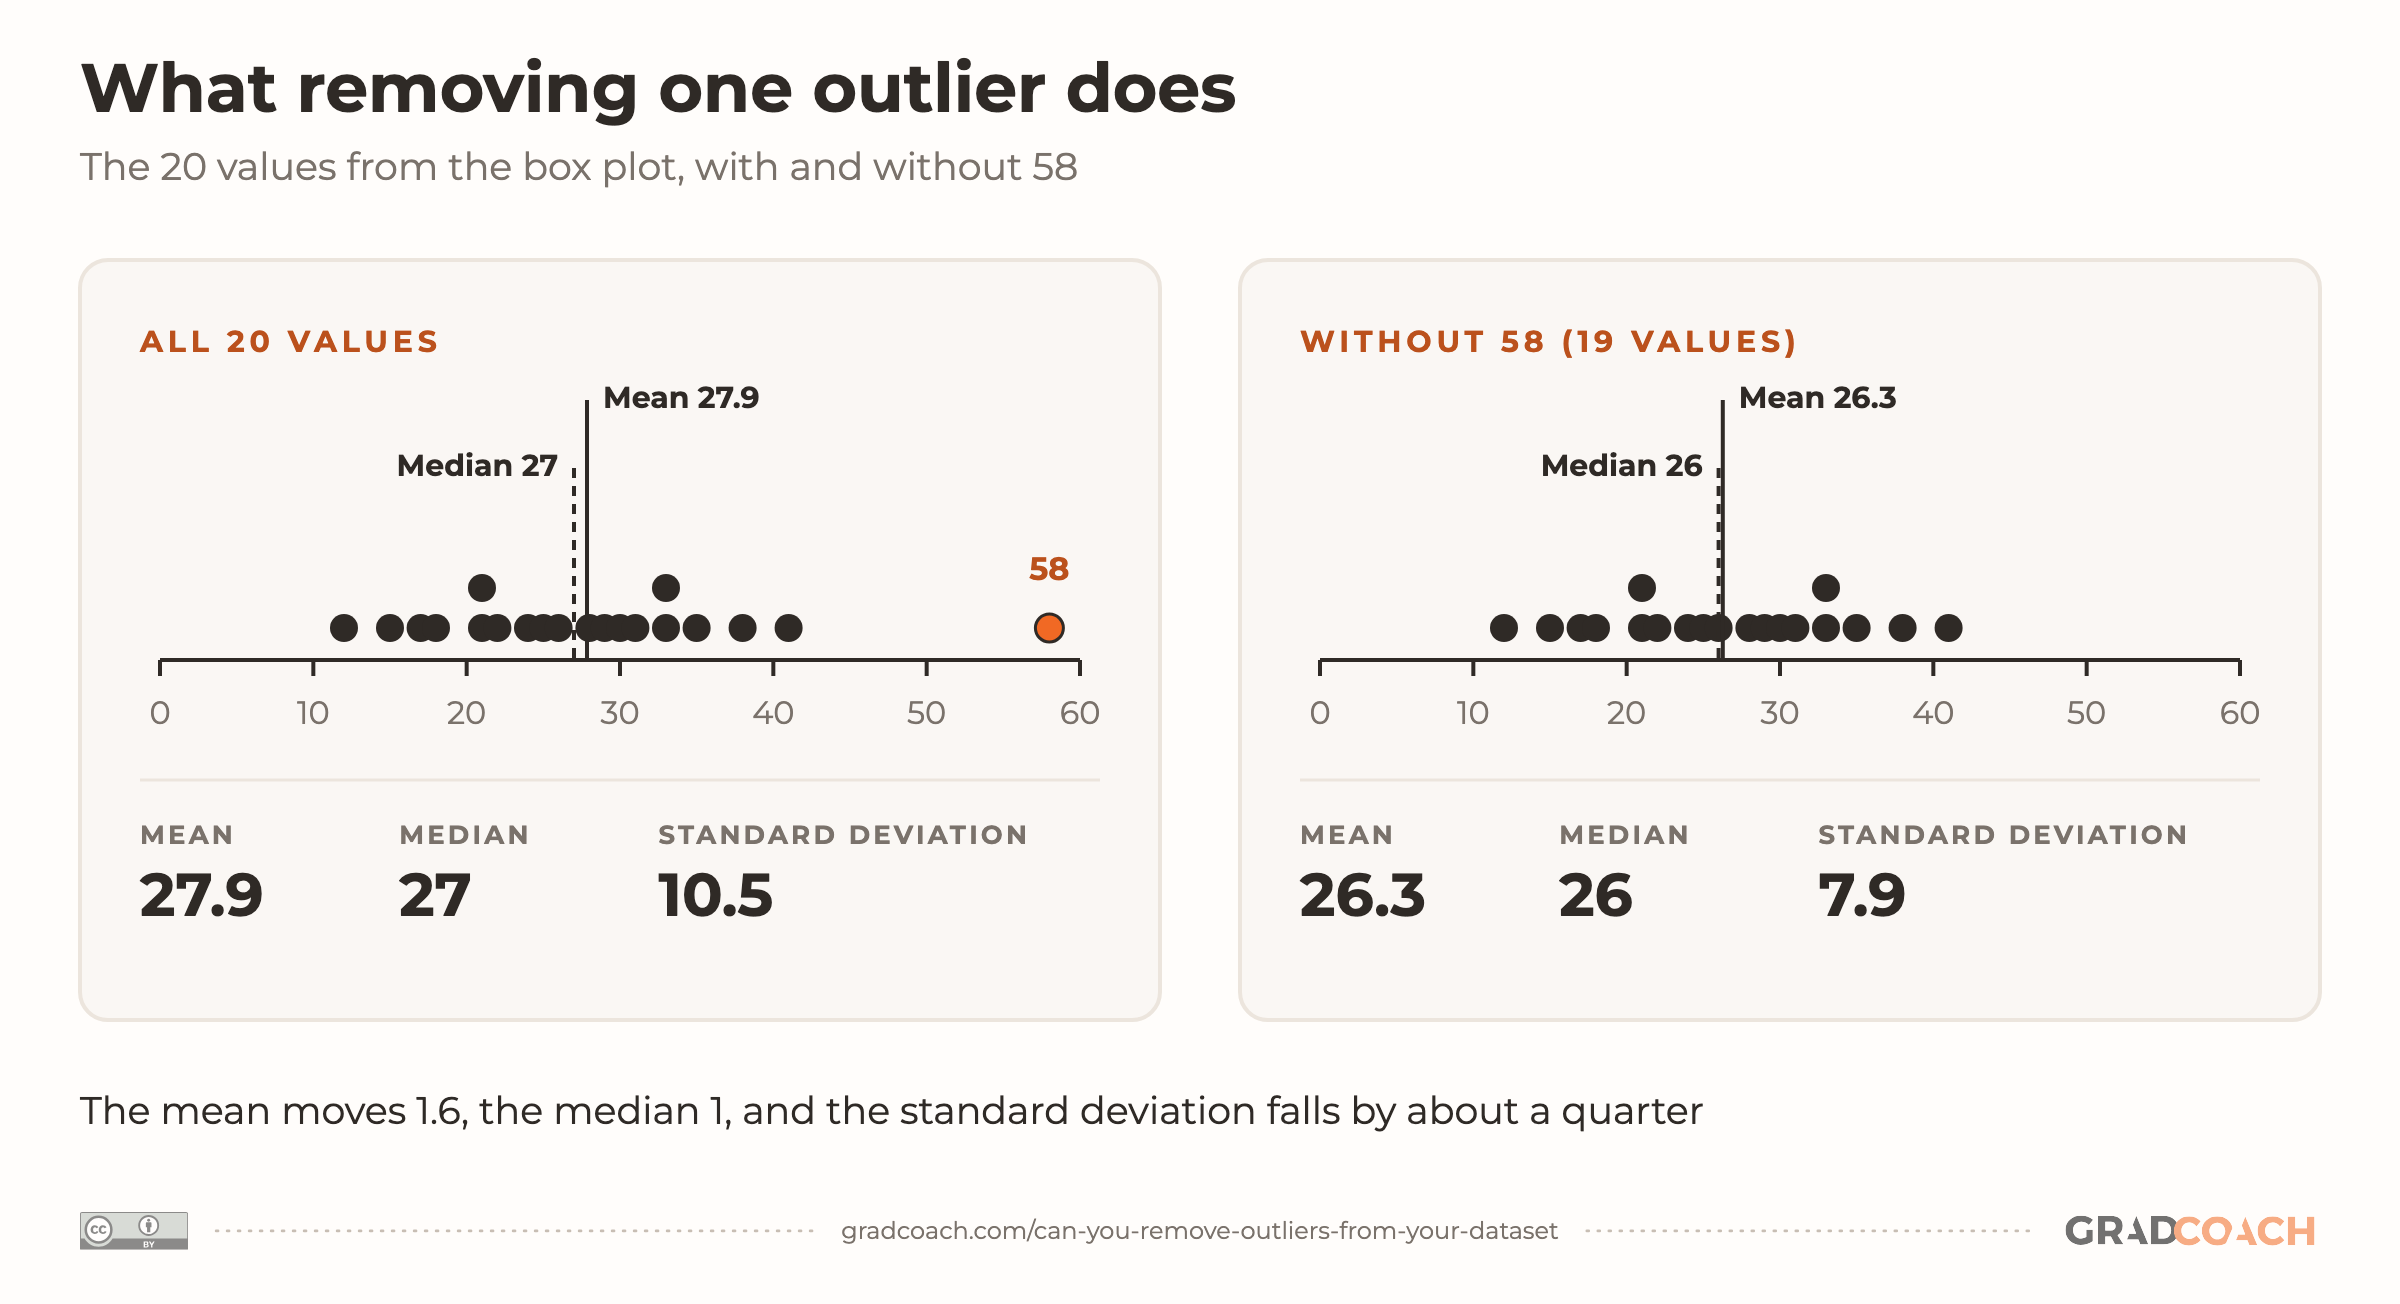
It helps to see the effect on paper. Take 58 out of the 20 values above and the mean falls from 27.9 to 26.3, while the median only moves from 27 to 26. The standard deviation shrinks by about a quarter, from 10.5 to 7.9.

That narrower spread is the hidden cost. A smaller standard deviation makes differences look more certain, which is why the guide warns that removing values that genuinely belong “artificially decreases the error estimation.” A short review of data preparation methods makes the same point about trimmed estimates: they “decrease the variance in the data and cause a bias”. And if you keep an outlier, the median is the safer summary: it moved 1 point here, the mean 1.6.
Recode them instead of deleting
The third option keeps every case but limits how far an extreme value can pull. The usual version is winsorizing, where values beyond a chosen percentile are replaced with the value at that percentile. The business doctorate below, from Bamberg, uses it in an event study, a method that measures how a company’s share price reacts to an announcement. Notice where its cutoff comes from:
The passage calls winsorization “the widely applied” approach and cites a source for the 1st and 99th percentiles, which is what makes them a defensible choice. If you winsorize, name the percentiles and the source, just as this passage does.
How to report outliers in your dissertation
Whatever you decide, write it down. In my experience, a committee will accept most reasonable outlier decisions. What they won’t accept is a sample that shrinks between your methodology and your results with no explanation.
That gap is common, and it’s visible. When the study of psychology journals mentioned earlier checked articles that reported no data exclusions, it found a mismatch between the stated sample size and the reported degrees of freedom (a figure most tests report, which depends on how many cases went in) in 14 of the 34 it checked (41%).
The authors are careful to say the gaps may have other causes, such as unreported missing data, but they read the pattern as “common failure to report data exclusions (or missingness)”. Your examiners can do the same arithmetic on your tables.
Avoiding that gap starts with how you edit the data. Never change your raw file: make your corrections and removals in a copy, and keep a log of each change (the case, what you changed and why). The log is what you’ll write your methodology paragraph from, and it lets you rerun the analysis with the original values whenever you need to.
Your methodology chapter should cover four things:
- The rule you used to flag outliers, and its source
- When you set it
- How many cases it flagged
- What you did with each kind
Here’s a template you can adapt; replace each bracket with your own details:
The template keeps the three kinds of outlier apart and gives a count for each, so your committee can see exactly what changed and why. Notice the last sentence, too: reporting the result both ways answers the question an examiner would otherwise ask in your defense (viva).
If your results did change, say so plainly and explain which version you treat as your main analysis. The rule belongs in your methodology; the counts and the with-and-without comparison go in your results chapter, and our walkthrough shows how to report them there.
Check your field’s norms
Fields differ on which rule is standard, and the extracts above show it. The psychology dissertations flag values at 3 or 3.29 standard deviations, while the event study winsorizes at the 1st and 99th percentiles, citing a source for that cutoff. Neither is wrong, and a committee in each field will expect its own convention, or a good reason to depart from it. My advice is to follow your field’s convention unless you can explain why your data need something else.
So before you settle on a rule, check two things. Look at how three or four recent dissertations in your department, or papers in your target journals, handled outliers, and ask your advisor (supervisor, in the UK) whether there’s a house preference. Then cite your rule the way those sources do, whether that’s a statistics textbook, a methods paper or the guide to managing outliers used throughout this post.
Set your rule before you see your results. The guide recommends pre-registering how you’ll detect and handle outliers, and for most students the proposal is the natural place to write it down. If you didn’t, that’s fixable: say so, and report your analysis with and without the flagged cases.
Still have questions?
Is it cheating to remove outliers?
Not if you have a reason you can state and you report what you did. Correcting a typo or removing a participant who didn’t meet your inclusion criteria is ordinary data cleaning. Removing values because they weaken your result, or trying rules until one gives a significant answer, crosses the line. If you can, write your rule into your proposal before you collect data. That’s a student’s version of the pre-registration one widely cited guide recommends, and it answers any suspicion that the rule was chosen to fit the result.
Why does the IQR rule use 1.5?
The 1.5 is a convention, from John Tukey’s work on box plots. In normally distributed data, fences at 1.5 IQRs fall about 2.7 standard deviations from the mean, so a little under 1% of values land beyond them by chance. Some guides add outer fences at 3 IQRs to mark “extreme” outliers, and a fence that wide flags almost nothing in normal data.
Are outliers 2 or 3 standard deviations from the mean?
Three is the more common cutoff, at least in psychology, where some researchers use 3.29 instead. In normally distributed data, about 4.6% of values fall more than 2 standard deviations from the mean, so a 2 SD rule would flag around one value in 22 even when nothing is wrong. Beyond 3 standard deviations it’s about 0.3%. Bear in mind that an outlier also inflates the standard deviation, so the rule can miss the very value you’re worried about.
What happens if you remove an outlier?
Every statistic built on the mean shifts. The mean moves toward the rest of the data and the standard deviation shrinks, which can make differences look more certain than they are, while the median and other rank-based statistics barely move. That’s why a removal needs a stated reason, and why it’s worth reporting your key result both with and without the removed values.
How many outliers can you remove from a dataset?
There’s no fixed number or percentage. Any value that is an error, or comes from outside your population, can go, however many there are. If a rule flags a large share of your data, though, those values may not be outliers at all: your data may simply be skewed, bunched up at one end with a long tail stretching toward the other. In that case, a transformation or a method based on medians or ranks will usually serve you better.
How do you justify removing an outlier?
Give the reason the value doesn’t belong, not just the fact that it’s extreme. A justification names the case’s cause (a data-entry error you couldn’t correct, or a participant outside your target population), the rule that flagged it and where that rule comes from, and how many cases it affected. Then show that your main result holds, or say how it changes, with the case included.
Can you remove outliers from Likert scale data?
Not usually by extremeness alone. On a 1-to-5 item, a 1 or a 5 is a legitimate answer, so there’s nothing to remove. A value outside the scale, such as a 55, is a data-entry error to correct. Once items are combined into a scale score, you can screen those scores with the usual rules, and it can be worth checking for patterns such as a participant giving the same answer to every item.
Can’t find your answer here? Ask a Grad Coach directly – the initial chat is free.
Speak with a friendly coach →


Cite-worthy sources
Cite this article
Jansen, D. (2026). Outliers in Research: The Basics. Grad Coach. https://gradcoach.com/can-you-remove-outliers-from-your-dataset/
- Bakker, M., & Wicherts, J. M. (2014). Outlier removal and the relation with reporting errors and quality of psychological research. PLOS ONE, 9(7), Article e103360.
- Drechsler, K. (2023). Promoting digital innovation and transformation: Innovation champions in the digital age [Doctoral dissertation, University of Bamberg].
- Kwak, S. K., & Kim, J. H. (2017). Statistical data preparation: Management of missing values and outliers. Korean Journal of Anesthesiology, 70(4), 407-411.
- Leys, C., Delacre, M., Mora, Y. L., Lakens, D., & Ley, C. (2019). How to classify, detect, and manage univariate and multivariate outliers, with emphasis on pre-registration. International Review of Social Psychology, 32(1), Article 5.
- NIST/SEMATECH. (n.d.). Detection of outliers. In e-Handbook of statistical methods. National Institute of Standards and Technology.
- NIST/SEMATECH. (n.d.). What are outliers in the data? In e-Handbook of statistical methods. National Institute of Standards and Technology.
- R Core Team. (n.d.). Box plot statistics (boxplot.stats). In R: A language and environment for statistical computing. R Foundation for Statistical Computing.
- Röseler, L. (2021). Anchoring effects: Resolving the contradictions of personality moderator research [Doctoral dissertation, University of Bamberg].
- Tunstall, C. M. (2026). Confirmatory factor analysis and further validation of the Trent Measure of Vicarious Trauma (TMVT) [Doctoral thesis, University of Lincoln].